2026-09-09 08:00:01
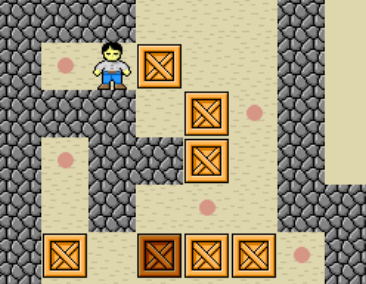
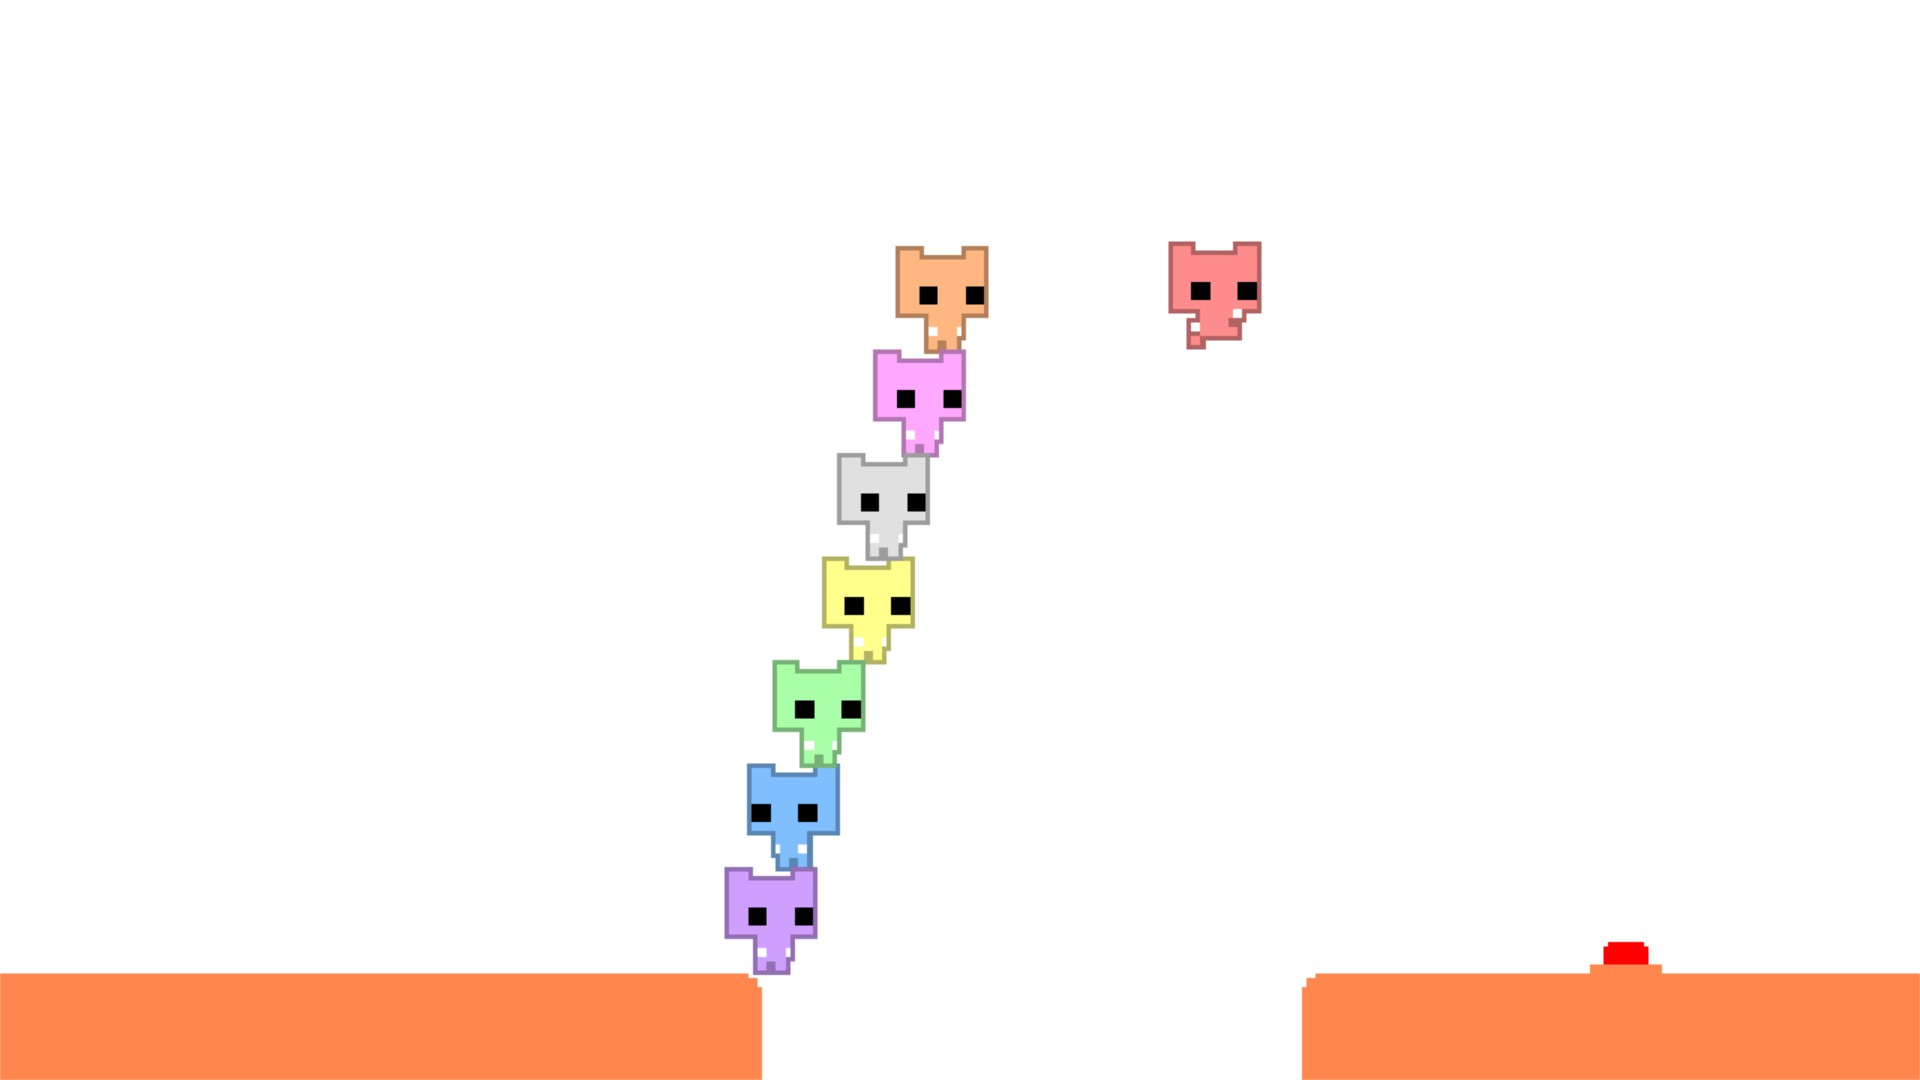
Just a reminder that all those one-shot three.js games generated by language models are not games, not even demos. They are 3d environments with minimum interactive elements. Meanwhile, these are good games that language models are currently not capable of creating:
2026-05-08 08:00:01
I have an old project box in the closet. I’m living in the old project box.
Hello and welcome to the Hackaday podcast. I’m Elliot Williams. And I’m Tom Nardi. This is episode 369, IR, E-Ink, and Avgas.
This week in Hackaday news, you’ve seen the chip shortage and the memory shortage, now prepare for the PCB shortage. News agency Reuters is saying that because of the Iran war, they are having trouble getting epoxy resin precursors through. This combined with other increases in the price of copper may lead to, hold on to your hacker hats, an increase in the price of PCBs.
“Oh no.”
I kept on saying that, well, not just me, right? But I kept on saying, well, why bother making PCBs at home when they’re so cheap and they’re so easy to do? And all you got to do is send away and in a week have these things on your doorstep for a couple bucks. But it seems the world is trying hard to take that away from us.
We’ll survive. We’ll survive. I—everyone out there, I’m sure—remembers the chip shortage. We all have not very fond memories of the chip shortage when it was hard to get any sort of microcontrollers. There were even crazy stories about people salvaging chips from washing machines and things like that. Remember those crazy times?
Memories. Yeah, I don’t know what to salvage resin out of. If that’s where we’re at, we’re in big trouble.
We’ve got tons of old PCBs lying around. Yeah, right. We just have to find one with the right footprints and glue them all together. Of course, you don’t have any epoxy resin glue to glue them.
Anyway, my hot take on this is that this is going to be a tempest in a teapot and it will resolve itself soon. But we’ll see. In a couple months, if you can’t get PCBs made, you can send your pitchforks to editor at hackaday.com.
Luckily, we have no shortage of instructional posts on how to make your own PCBs. That could be the real renaissance in homemade PCBs. It’s like, you know what? The hell with this. Doing tariffs and resins, I’ll just figure out how to make the things at home.
Yeah, but what you really need is a stockpile of already copper clad FR4, right? If the substrate has gotten incredibly expensive, it’s not going to help you. If you can etch your PCBs at home, you have to have enough raw material sitting around already. Buy it now. I’m going to start just getting copper plate and doing it.
Yep. Buy it. Etch right into the copper. I’ve got about three kilos of assorted random copper clad over there in the closet. I think I’m good for a couple of years. I was like this during the chip shortage. I’m such a bad person. I shouldn’t gloat about this.
During the chip shortage, I had just bought like 50 of those blue pill boards because they were so cheap. They were a buck or two. And I’m, all right, I was a buck 50. I found this deal and I’m all right, I’m just going to buy an infinite number of them. And I did. And I still think I have a few of them kicking around actually.
But they’re pre-counterfeit blue pill boards. Oh, they were worth a million dollars during the chip shortage. I should have sold them all off. See, the normies were hoarding toilet paper. And stuff like that. And we’re over here hoarding microcontrollers for the revolution.
In other Hackaday news this week, we are judging the Green Powered Challenge. We’re recording early this week. So our judges are still out. And consequently, I don’t know what the results are yet. But they should be coming out anytime soon now. Possibly even already out as you hear this podcast. So if the results are out for the Green Powered Challenge, give it a look on Hackaday.
And speaking of next week, Hackaday Europe is next week. If you are at all interested in joining us down in Lecco, Italy, please come along. You’ll find the link for tickets and the workshops and all that over at hackaday.com. I’ll throw the link in the show notes. Can’t wait.
Mailbag? You have to read this one, right? I have to read a bunch of them now. Who uses words? Who’s using the written word in 2026? Yeah, last week we got nothing but spam in the mailbag. This week, the good news is we still got spam for the Streamflow Ultra K2B4 pump. I don’t even know what it is, but it actually sounds like something I’m interested in. I still got the B1 version. I got to upgrade.
But we also got two, count them, two mail-ins from actual people. One from Conran Farnsworth.
“My new job has me with a lot less free time to browse Hackaday and read your articles. It’s nice to hear hacker banter during my 45-minute commute, and I pull a lot of inspiration from my projects from the community as a whole.”
Don’t we all. I just hope he’s not an air traffic controller or anything. I can’t read it, but I can still listen to it while I’m working. Nate is on his commute. On his commute.
On the way to the tower.
He’s just listening to it.
It is no secret that a number of people read Hackaday at work.
I do.
I did before I worked here, too, though.
Thanks, Conrad, for writing in.
“Don’t anyone follow his advice.”
“Go read Hackaday.”
“Don’t listen to the podcast.”
Wait a minute.
He’s sabotaging us here.
We’re shooting ourselves in the foot with this podcast.
Go over to Hackaday and read the website.
I only took 380 episodes, whatever we're at.
Wait a minute.
No, no, this is the opposite of what we’re trying to do.
And the other entry in the mailbag from Michael Pete:
“Is there a hack that was featured on the site that you use in your day-to-day or professional life?”
That is an excellent question.
The answer is definitely yes.
I think picking the one or two would be the hardest one.
I could say, for me, several things come to mind.
But definitely the most common thing around me would be the firmware that Aaron Christophel did for the cheap Bluetooth thermometers.
I have, I probably have a dozen of them in almost every room of the house, all over the place.
And they’re all running his firmware.
Or, as he would point out, because I’ve actually communicated with him back and forth about this a little bit, the project has sort of taken a life of its own.
So he did the initial groundwork.
And now there’s a fork that he kind of points everybody to.
But he’s still the father of cheap Bluetooth thermometer firmware.
So that’s been something that literally in my day-to-day life; I can see one of them right now from where I’m sitting.
And I never would have bought them if it wasn’t for the open firmware and to be able to do all kinds of stuff.
We see that a lot.
So definitely for me, I think the replacement firmwares for a lot of stuff are the one kind of thing I, and I’ve said that before, it’s one of the hacks that I get the most excited about.
And consequently, I end up using the most in my day-to-day.
I thought about this one a little bit, and I don’t know that I have any exact hacks from Hackaday, but tons of things that I’ve been inspired by.
Last week, Christina and I were talking about do-it-yourself computer peripherals.
And of course, I got fooled into making my own keyboard from an article I saw on Hackaday, and I can remember it.
It was a hand-wired mechanical keyboard, and I remember looking at it thinking, “that absolute maniac spent three hours point-to-point wiring all of these hundred-and-something switches.”
What kind of absolute insane would do that?
So anyway, where’s my soldering iron?
It percolated in the back of my head for a few months, and I thought all right, I’m just going to make a small keyboard.
And so I built what was going to be a travel keyboard, and I’m still using it to this day; what, six years later or something.
But it was a hell of a lot of soldering.
It was an insane amount of soldering.
It took me two nights because I lost patience.
After about an hour and a half of little twitchy point-to-point soldering, “okay, I got to take a break.”
I’m done with this.
And you do something else.
But I spread it over two nights, and it was actually quite enjoyable.
It’s worked for whatever, six, eight years.
I don’t know what.
It’s my daily driver.
I bring it with me as a travel keyboard, too.
It’s long past time for me to make a full-size keyboard.
“Don’t fall into the trap of making yourself a 48-key keyboard, people.”
Live large.
Go with as many keys as you possibly can.
I ended up doing it as kind of my own design, but I totally ripped off this guy’s project.
We use the word inspired.
I followed his beautiful example.
I guess it kind of goes without saying, but maybe not.
Certainly more projects that I could possibly count have gone the opposite way, too.
I’ll find something, use it, and think, I should write this up for Hackaday.
So when you look at it from that direction, then I couldn’t even tell you how many.
I’ll find something, maybe somebody posts about it on Reddit or whatever, and I’ll mess around with it.
For me, anyway, I want to be able to say in a write-up on Hackaday that I use this.
This is really cool, and here’s why it’s cool.
I think that’s a lot more compelling to read about than just, somebody made a thing.
I download a thing and play around with it before I even write the first word of the post because I want to be able to say, “this is legit.”
I’m looking around me right now.
There’s also, I rebuilt Ted Yapo’s TritiLED project, which was a super low-power LED driver circuit, basically.
It pulses them with a low-duty cycle, but super, super, super low-power. And actually, I’ve got one on my bed downstairs that I taped to the corner of my bed so that I don’t stub my toe on it when I’m sneaking in late at night and my wife is sleeping. Thing’s been running for, God, also six years or so, but I have a bunch of the little versions of his circuit that I made myself kicking around all over the place here. They’re fun.
This is one of those things, once, ages ago, when 3D printing was not what it is now, Mike Szczys asked me,
“Yeah, sure, 3D printing, it’s good for making tabletop figures, but can you actually make anything useful with it?”
And I just looked around me, and I could find 40 or 50 3D printed useful things within arm’s reach, or at least within eyesight at that point in time. Still probably could.
And I have a bad feeling it’s probably like this with things that I have seen on Hackaday, too. There’s my drawer full of microcontrollers. How many of those was I turned onto by Hackaday? Probably all of them. Debugger over there, definitely read about that on Hackaday.
I forgot that Mike was a secret 3D printing skeptic for a very long time. Yeah, right? I wonder if he… Does he finally have a printer? I’m sure he’s listening. Mike, if you have a printer, let us know. Did you finally cave? Anyway, Michael, hope we answered your question for you. That’s a good one. That’s a great one. And I know neither of us even scratched the surface here.
Oh, yeah. In short, read Hackaday. There’s cool stuff there. In short, I’m inspired by something all the damn time.
Yeah. This is a journey into sound. What’s That Sound? All right, well, let’s head on off to What’s That Sound? This is a brand new sound week. And not to prejudge, but I’m going with it’s a stumper. That’s a pretty safe bit. All right, I’m going to listen to it here. Let me see. Go for it.
“Go for it.”
You know, at first, I thought it was something arcing, but I don’t think it is. Actually, it sounds like, and I don’t know that it is this, but it’ll be ironic. For whatever reason, YouTube occasionally recommends me videos about people making pens on tying little lathes. It sounds kind of like somebody making a pen on a little lathe.
It’s actually a sound I recorded myself. You weren’t making a pen, were you? I was not making a pen. Not making a pen. I’ll give you that. Yeah, I won’t say too much. Audience out there, this is a tough one. If you have any idea what this is, head on over to hackaday.com/podcast. Scroll on down to the What’s That Sound? Click the link to the form. Fill in your handle, your best guess, and we’ll see who gets it right next week.
I was so close to buying a pen lathe. I almost bought one. I was even asking people, you want pens? You want pens? I don’t even use pens. What do I need a pen lathe for? But whatever. If you have no good guess, write in something funny anyway, because I have a feeling not many people are going to get this one, and if nobody gets it, we’ll raffle among the wrong answers.
All right. Well, my first hack this week comes from i12bp8, probably his or her real name, I guess. That sounds like a totally legit name. TagTinker lets you hack electronic shelf labels. These are those e-ink shelf displays. I didn’t realize that there were some of them that are kind of old enough / simple enough that they used infrared codes to reprogram them. I think all the kind of modern ones we’ve seen have used radio, but apparently there is a supply of old infrared ones out there, and if you find one and want to program it yourself, all you need to do is figure out the right IR blinky patterns to send it, and that’s what this is about.
Well, TagTinker is a Flipper Zero application, but as i12bp8 points out, you can also run the same thing on just an ESP32 with an infrared LED on it, and the same code will run just fine. If you head on over to the GitHub, it’s a complete library along with a nice web page to upload images, and this is really cool. I really want to find some of these old tags that A, are dumb enough that all you have to do is blink at them to get them to display, and B, start playing with it. This is one of those that looks really, really fun.
It builds on work from quite a long time ago done by furrtek, and I was, oh, this actually sounds familiar, and so I went digging on Hackaday, and lo and behold, the original hack, this is epic, dates back to May 2014. So, a mere 12 years ago was when furrtek was looking into these devices and found that because they use a non-standard infrared protocol, couldn’t get it working with anything else that used regular IRDA.
And according to the write-up, this includes PDAs:
So, if you’re trying to reprogram this with your Zorus, you’re fully out of luck. You might have to fast forward into the modern era and use a microcontroller.
What’s awesome about this original hack, however, is that FurTech found that if you overclocked a Game Boy to exactly the right frequency, you could send the signals that would enable you to change the data on some of these chips in some of these electronic shelf labels.
These really old ones, however, predate E-Ink. This apparently is an ancient protocol that was used to do those old, the first generation LCD changeable price tags, and it’s funny to me to think that there’s some continuity to the modern E-Ink shelf label price tags, but there you go.
Once you have a working system, I guess you don’t change it, right? Infrared, I get it, kind of. I get why it might have seemed appealing at the time. I think there was this idea that you could blink in IR LEDs from the ceiling or something. Because I think you do have to address them with their number. In theory, you could have LEDs in the ceiling of the store, and they all just blink and everybody sees them. But, yeah, we have radio for that now. But, yeah, there’s still plenty of stuff out there that is using infrared. So, I guess it makes sense to a degree that they’re out there. I do wonder realistically how many you run into.
That was the one thing with the project, actually, the Tag Tinker project. It’s kind of hard to say. It would be cool if there was a compatibility list, because, I mean, they have the pictures of them here, but there’s at least two different ones pictured, although they appear to be different size variants of the same thing. So, I’d be curious to see how many tags are actually susceptible to this, and what are they? Not even for anything illicit, necessarily, but if I wanted to go and try to find these things on eBay or whatever to use for my own purposes, now that they can be controlled, it would be nice to know what the hell they’re called. I’ll have a look at them. I think the dead giveaway is the little black IR receiver that’s on there.
Well, yeah, right. The examples that i12bp8 has on the website here both look very similar. Both have an RGB LED as well, so it must blink codes back to the programmer. I don’t know. There’s a lot of speculation about whether this is run by a central LED network blinking out codes, but my guess is that it’s much more pedestrian than that, and that people had a handheld unit, and they would just go around, type the price in, point it up at the thing, and upload the image to it, or upload the new price to it. It’s just when you used to go around with a price gun sticking labels on things. It’s just the same, but blinking IR codes out instead.
On the furrtek page, there actually is a very low-res, I guess, again, we’re talking about stuff from 2014, I guess. Very low-res picture of somebody using some kind of handheld thing to enter it in, I suppose.
So, “Pricer”, I thought, was just a, something was written on there, but apparently that’s the name of the company. Oh, okay. The two tags say Pricer on them, but that’s just also the name of the company making price tags.
Nah, but some of these are really pretty-looking screens. I mean, they’ve got some of the black and white with red and or yellow accents, e-ink displays. Makes you really want to figure out how they work, honestly.
And I think infrared gets a bad rep these days. I think it’s an awesome way to transmit data, and I’m stoked to see commercial projects using it. Radio is awesome, but it kind of goes everywhere. You can aim an IR LED in a pretty tight cone and put that signal exactly where you want it, which, if you didn’t want to do a whole addressing scheme, for instance, you wouldn’t have to, because you point the LED at this one, only this one changes, right? So, there are a bunch of advantages in using that.
My favorite part of this whole library is the disclaimer with a red caution line that says, in all caps,
STRICTLY PROHIBITED FOR ILLEGAL USE.
So, I guess the idea is you shouldn’t go to stores and change the price tags on the shelf. But, what’s going to happen if you do? The price tag says one thing on the shelf, and then you go up to the scanner or, and they run the SKU, and they charge you the right price for it anyway. So, you’re not going to get cheap Ritz crackers this way. That was not an endorsement.
This episode is brought to you by delicious, buttery Ritz crackers.
“Mmm, I have some right now.”
“Which I actually think are kind of gross.”
“I wish I hadn’t mentioned it.”
“Oh, damn.”
“There goes that sponsorship deal.”
“The shortest sponsorship deal in podcast history.”
“Hooray.”
Anyway, really, really cool project. I love signals hacking, and think IR signals hacking is just as cool as radio signals hacking. Don’t be discriminating based on spectrum. Hack all the electromagnetic waves.
Well, in a sort of related kind of thing, ePaper dashboard reimagines smart homes connection with technology. And this is a really cool, it is sort of one project, but it’s been developing for quite some time now. And Joel Hawksley talks about how he wanted to kind of get off of staring at the phone and wanted to put more status information about the house and schedules and stuff on e-ink. Because it’s a little less gross to look at, to have e-ink hanging around the house. And the resulting journey to kind of make that happen. And it starts simple with little displays.
And it’s actually I kind of thought it was funny that at one point, Joel was using hacked Kindles. That’s where I am on the hierarchy of e-ink hacking for your home. I’m still on the hacked Kindle step. I got a jailbroken Kindle that is pulling stuff down and showing it on the screen. Which is actually very convenient, right? Especially given the availability and price of old Kindles. But they’re Kindles. And they’re not really meant for kind of heavy lifting. And the screen’s limited to, whatever, six-ish inches, whatever they are. So at some point, you’re probably going to want to go bigger and more capable. And that’s where things really start to get interesting on this one.
Joel talks about some of the stuff that’s on the market out there. And these large format displays. And at one point, he got this 32-inch EG panel, which is monstrous. But he wasn’t really happy with that. Because he said that was a lower contrast, an older tech. So then he actually went down to a 13-inch one. And it’s sort of this tour of all the different options that were on the market. And this is, again, this is going back at least five or six years. It goes right up to the present day and what he’s doing now.
And that is sort of he started with this big custom code base that was pulling all the stuff in and making the images. And then the screens would pull them off, basically just pull it over to the HTTP and just show it as an image, right? A static image on the screen. But now he’s really leaning into Home Assistant and finding that Home Assistant does a lot of that pulling in data and organizational stuff. So he’s been able to strip that out of his side of the equation.
And also, I thought it was pretty cool some of the stuff that he was doing with his own code, he ended up merging into Home Assistant, right? Because probably somebody else would be into it, too, if he liked his calendar looking a certain way, well, why not share that with the class? So it’s a really cool kind of give and take. And it does sound like, ultimately, he wants to turn this into a product of some sort. So that’s something I guess that’s still kind of on the horizon. But even without that, it’s really interesting to see one, what’s out there hardware-wise. And then, two, how much of it can be kind of done with Home Assistant and open source code for anybody who has the patience to put it together.
It’s funny. I was looking at these, and one of the things that I really liked was kind of how stylish and clean and whatever the graphics look. He’s got a little bar at the top that just has status information. And so, tells you if the door is open or if the washer and dryer is just finished or something that. But otherwise, it’s left blank. His family has a lot going on. Aside from the technology involved, I feel I should be doing more of my life because this dude’s got a full schedule every day. Up to and including I’m pretty sure it says what he’s going to eat for lunch and dinner on there. Right? He says chicken salad and then strength training. I’m not so sure about the strength training, but I’m down for the chicken salad.
So, at least some of this stuff I could utilize, perhaps. But, yeah, it did strike me that there’s an incredible amount of information on there. But then also, you said, it just looks really good in a way that I don’t think a lot of other display types would, really. Obviously, you have the advantage of power saving, right? You write to it once and it’ll stay there wherever for as long as you need. But it just looks a lot classier. I feel if there were TVs on their side all over the house showing similar imagery, it would just kind of look tacky. It would almost look like the menu in a restaurant or an advertisement. And maybe that’s just being programmed by the culture on our expectations. But they just definitely, they look like something you want to have in your own house. Or at least I would. Absolutely.
Well, for my next hack, I wanted to talk about a three-axis camera slider built from 3D printed parts by CNC Dan.
And actually, we covered not one, but two camera sliders this week. And I think they’re fun and interesting to compare and contrast them in a way. CNC Dan’s is a second version of a camera slider he built.
He found himself shooting with a real video camera, one that weighs 1.4 kilograms. So it’s a pretty heavy camera. And so he needed to make himself a fairly strong, sturdy camera slider that’s able to move this thing. It’s a 3D camera slider, so it moves along a track. In this case, it’s a V-groove aluminum slider, but then it also rotates in two directions. It can pivot left, right, and aim the camera up, down.
His goal is to make it do nice regular speed pan shots, but then also to enable it to do super long time-lapse shots where it’s moving along a predetermined path as well. And that gives you kind of two different constraints:
And he found that he was having problems, especially with the ladder here. And it was jerky and jumpy. And that’s actually what this build has in common with the other camera slider build we featured this week. The HyperFix is also having camera slider problems. “Camera slider build instead of buy goes awry.” It’s funny, he also has this steppiness problem. And both of them, I think, conclude that it is in their software that they’re trying to drive the thing.
CNC Dan, as the name would imply, has a lot of CNC home machining equipment at home. And that means that his particular slider has a bunch of custom-built aluminum parts. And he is not afraid to use bearings to smooth things out or big reduction gears coupled with timing belts to give the stepper motors that he’s using a little bit of a chance at moving smoothly here. But then, when it comes time to writing the software, the first versions of this are jumpy and jerky and absolutely no fun.
What he actually needs to do is work on his motion control routines. He does that, and it ends up working beautifully smoothly. He then even writes a little web-hosted motion planner app that lets you put it into one keyframe and another keyframe and another keyframe and move smoothly between them, dwell at this one for that long, move to the next one. Really, really cool in the end, and good he got the jerkiness figured out.
Hyperfix, you should go check out CNC Dan’s code. It’s all up on GitHub. That will probably also solve your problems.
Talk about stuff that you’re inspired by on Hackaday. I always want to make one of these right after seeing one of these projects. I think, realistically, I don’t make videos, right? So I don’t really necessarily need this. But I love the idea, and to the point that I actually put an aluminum extrusion over the top of my bench. With the idea that I would have some little thing riding on it. And that never happened. But I do clamp lights to the rail sometimes. So that’s halfway there. I even have a little truck, for lack of a better word, with the wheels. That I do, I do put the DSLR on it, and I can slide it back and forth, but it’s not motorized.
There are so many of these out there, and thankfully, a lot of them are open source, at least to some degree. So I think if this is something you’re into, certainly look around at what’s out there. And not everybody has to reinvent the wheel. I suppose have at it. But definitely take a look at some of the stuff that’s been done before. Because it really is incredible what they’re accomplishing with spare parts and little printed bits.
The irony of this all is that CNC Dan, CNC’s in his name. And the first thought I had for this firmware is, “run GRBL on it.” Like, run a known, established motor controller software. And GRBL has nice acceleration profiles in there. You can tell it to limit acceleration. You can make it as smooth as you want. “What do CNC Dan’s CNC machines run on?
G-code.
Why couldn’t he make his camera slider run on G-code?
And just throw one of the nice modern ESP32 GRBL interpreters on there.
FluidNC even has a little web interface.
That’s the way I would do it if I were approaching this project.
Because then it turns the whole pre-processing stage into how do you turn keyframes into G-code? That’s one of those things that a simple afternoon’s Python scripting could solve for you.
That’s what universal machine movement languages are for.
And then he wouldn’t have to deal with the acceleration profiles and generating the steps.
And the Hyperfix who has problems with having the Arduino that he’s using not able to make pulses fast enough to drive the stepper drivers.
Any time past 2010, I think, you do not want to be writing your own stepper driver at that level.
Just put GRBL on the thing and move on.
But the irony that he took these things off of the machine that already spoke G-code and un-GRBL’d it.
What an irony that his parents named him CNC Dan, too.
Sometimes it happens. You get these names and it just determines your whole life.
Yeah, right? Well, little CNC Dan. What do you think he’ll do when he grows up?
Related in the sense that it’s made with CNC parts.
My next one is cutting steel gears with homemade EDM.
This is further developments in the field of home EDM.
And no, that’s not… We’re not talking DJ.
And this is electric discharge machining, which is basically sparky wire cuts metal, to put it simply.
So in this case, it started its life as a desktop CNC router.
And we all know how well water and electricity mix.
And the end result is that you could basically just kind of erode a workpiece with sparks, for lack of a better way to explain it.
And it works phenomenally well.
The picture in the article is a gear that was made on this thing.
I gotta say, I don’t know that I realized you could do such detailed work with a home EDM setup.
This gear is smaller than a thumbnail, but has, I don’t know, 12 teeth or whatever.
Super, super tiny gear. And perfect.
Dimensionally perfect, really.
I would… I don’t know that I’d print it. It’s small enough that printing it on a desktop 3D printer, I’m, eh, I don’t know. The teeth might be kind of mushy.
This thing’s cutting it out of a pretty substantial chunk of metal.
The downside is it takes hours, because you can only move through the workpiece very slowly while you’re just sparking it apart.
I think there’s an obvious comparison with desktop 3D printing, right? Where, okay, yeah, it might take hours for the thing to make this, but it’s gonna be dimensionally perfect and repeatable, and you don’t really… It’s not like you’re really doing anything for that time, right? You start the thing, and then you can go sleep if you wanted to.
So, yeah, it’s not a fast process, but I think the results are certainly worth it.
And to get these kind of custom metal parts, okay, so if it takes it, you talk about, 10 hours, 12 hours for some of these things. I mean, that’s a decent amount of time, but it’s certainly faster than having somebody make it and ship it back to you, right? So, I think you’re still ahead of the game in terms of getting these kind of custom parts.
What does he use as a power supply? That’s always the hook with EDM machines.
What kind of beefy high-voltage power supply has he got that can stand it arcing all the time?
Yeah, doing the thing they usually don’t like to do.
Imagine the microcontrollers driving this machine that’s making tremendous amounts of EMI, right? What does he use? Because I know I’ve seen projects. Oh, yeah, we’ve covered that for sure.
But, yeah, your point is absolutely taken that if it’s a slow machine, but you don’t have to stand there and watch it. If you can just walk away and let it do its thing, it doesn’t matter if it’s a slow machine. You probably sleep at night. That’s eight hours right there.
And certainly for the quality of the part. I would never, if somebody showed me that gear, I would never think it was made at home with some hacked together piece of hardware. Or maybe not even made at home at all, frankly. I mean, it really does look like a professional part.
So, yeah, if it takes the thing ten hours, have fun. It’s well worth it.
I don’t know that I would ever need enough metal. I guess if somebody told me one day you’ll have a thing that sits on your desk and makes stuff out of plastic, I’ll be like, well, how much plastic stuff do I need? You know what I mean? That’s right. It turns out I need a lot of plastic stuff.” Four more plastic stuff than I ever imagined, right? So, I suppose if I had a similar device to do it out of metal. Although, but you are limited, geometrically, right? It’s got to be stuff that you can cut out of a flat plate. So, it’s not quite as flexible. But, yeah. I suppose if I had one, there’d be a whole lot of stuff made out of flat plates of metal.
Next up from me, Victor Frost. ESP 32 hosts Solar Punk message board. And this is just a sweet little project. It’s kind of a modern reimagining of a pin board or a message board in a neighborhood gathering place. We used to have these in our supermarkets.
“dog walking services.”
“I have a TV I need to get rid of.”
This is that, but in website form, in a sweet laser cut box with a solar charging circuit attached to it. So, it runs on solar power, powers a website over an ESP 32 that has a little captive portal on it. And you can post to it. It’s really cool and weird because it’s a website that is hosted on the ESP 32 and it’s only local. So, you have to be in the immediate vicinity of this thing to log into it with your cell phone or whatever. So, it has the same kind of localizing function that a cork board does. And anyone who wants your dog walking services is probably also in the neighborhood. So, it kind of makes sense. It doesn’t need to be on the big internet that you’re walking people’s dogs. And so, the same thing with this. It’s just a sweet little device.
It’s entirely stripped. The whole webpage setup, actually, it’s in ProgMem. It’s burned into the program memory. But the messages, because they’re volatile, are stored on the disk space. You know, the effective disk space. And he actually says he makes a point of using LittleFS instead of the kind of standard SPIFFS file system that people often use on ESP 32 devices because it has a lot better power off behavior. And so, if this solar thing drops power for whatever reason, there’s a lot less risk of getting corrupted files on LittleFS. The whole webpage is stored in the program memory, but it’s not such an inconvenience because he’s also got the ESP 32 setup for over-the-air flashing. So, if he wanted to change the website, he’d have to modify the files anyway. Here, he just modifies the whole image and then sends it back up to it.
There are a lot of little details here. It’s got an admin page, and A shows up in the comments and says, “I was playing around with websites hosted in ProgMem and couldn’t figure out how to do the authentication for things like admin pages and have it not kind of statically stored and broadcast out to people who can read HTML code. How did you get around that? And I don’t think you did. And actually, I looked at it and you didn’t. And here’s a couple suggestions.” And Victor, whose project this is, comes in and says,
“ooh, thanks.”
And the two of them go off to GitHub and work on it together. So, that’s exactly what we like to see in the Hackaday comments here. And this is just such a sweet little community-building tech project. I love the spirit of it.
Looking at it, it reminds me a lot of what we’re starting to see with a lot of the mesh networks, right? I mean, there is this sort of rejection of the big internet, you know? Although we are fans of the big internet, as you may be aware. I definitely think it’s cool, this idea of these smaller, independent, local networks, be it a LoRa mesh or a Wi-Fi message board. And it’s cool to see how open source and cheap hardware enables this. You know, just, again, just like if you wanted to go on MeshTastic, $10 worth of microcontroller and free code get you there. It’s a very similar setup here. I mean, obviously, there is, in this case, there’s batteries and there’s solar-powered and the laser-cut lantern-looking case, which is pretty sweet. But, you know, just if you wanted to get a basic, hey, I want to have a little web page for everybody in the neighborhood to whatever, you could do that in a sitting, right? And I think that’s really cool to see. And I might be the only one using it, but I might set up a similar thing, with this kind of project.
That is sort of the one challenge, is getting your non-nerd friends on these kind of things, assuming you have non-nerd friends. If that’s the biggest problem, right, is convincing local people to hook up to this thing with their phone and post to it, that’s not a terrible problem to have, you know, if everything else is solved for you. Yeah, and it is one of the problems he mentions here, especially the captive portal. Some cell phones, I think he said Samsungs do, when they hook up to a network, they try to hit a website to see if the network they’re attaching to Has kind of broader internet connectivity.
And so you hook up to this thing at
192.168.4.1
and your phone says, > “this thing doesn’t have internet connectivity.” And so that can cause confusion for some of the users. He says that the solution to this is to actually just put up a QR code with the URL on it. And that’s perfect, right? That works for normies. You’re standing here at the device. The device is only its local network anyway. It doesn’t hurt to have the QR code there on the physical device as well.
In my mind, actually, the local QR code access kind of contributes to the the whatever, the hyper local network of this thing. And I think that’s pretty cool. And plus, it’s solar powered. It runs on batteries. It’s just going to sit there serving out local wanted board for whatever community.
Where did he, where did, does he say where he installs it? This should be in a library or Brooklyn, right? Ah, or a Brooklyn Borough Hall. Right, exactly. And to your point, the old school cork board, what people stick, you had to stand there anyway, right? So if I have to stand there and put my little flyer on the board, I might as well scan a code and save the paper.
Well, my last one is using NFC to power devices instead of Qi, which is actually how you pronounce that. If you’re ever curious, the Qi wireless charging is said as Qi. This kind of is a little bit of an explainer of the concept because, whether it’s wireless charging or NFC, you’re still sort of dealing with the same kind of inductive thing. Just one isn’t really made for transmitting power. But of course, there is some degree of power being transmitted when you do this.
In this case, it goes kind of over the numbers and at least theoretically, for wireless charging, you could get up to 25 watts, whereas NFC is maybe one watt. But in practice is going to be considerably less than that. Because again, it was never meant to charge anything, right? But, if you have a maximum ceiling of one watt, even with losses, if you can get 100 milliwatts out of it, that’s enough to run a microcontroller, right?
The one kind of thing you got to watch out for in this particular video is that it looks like the hardware itself is pretty custom on both sides of the exchange, right? So you have this custom NFC transmitter being picked up by the receiver that’s then able to power something. If you’re trying to do this with stuff in the wild, just NFC on your phone or whatever, you’re not going to have that custom transmission side. So this is sort of pushing the theoretical maximums, a little bit of a cheat maybe. But it does show what is possible.
And, if you say, oh, well, okay, well, what’s good, what good is that if I can’t do it in the real world? I can put them in the show notes that have shown that, yeah, with a coil of wire and an ATtiny, you can get enough juice to run a small microcontroller or light up some LEDs and that kind of thing. So while NFC was certainly not designed for it, you can bend the rules a little bit without breaking them. And I think there’s just some interesting potential there for all kinds of low energy projects.
We should do a low energy contest. That’s not a great idea. We should have done that. Oh, wait, we did. I love that you put ScanLime’s ATtiny chip RFID hack here. This is one of those to answer Michael Pete’s question before. This is one I do not use it anymore in my everyday life, but I have absolutely done this and cloned. This was, yeah, ScanLime’s old hack. I’ve definitely used that to clone an RFID card I had at the time. Don’t use it anymore. Loads of fun.
I saw the headline here and I watched through the video and he’s getting 200 milliwatts of power across NFC. And I’m like, wow, that’s pretty awesome. And I’m thinking, yeah, but this is lab conditions and aligned coils and all this. What could we do to steal power from NFC readers out in the world? And I don’t know the answer. It’s an open question, I think. I think it’d be really cool to build an NFC power harvesting variable load with display or something. And you could just go around and try to get more juice out of people’s NFC readers until they crash out or burn or, oh, maybe this is a bad idea. But, you see what I mean. It would be a fun experiment to see what you could get out of readers that are out there in the wild.
I mean, this is how NFC cards work. It’s not, in some sense, it’s not a hack, right? They draw microwatts of power from these things when they activate and chirp out their codes, right?
All right. Well, my three quick hacks this week start off with learn electronics repair matching transistors.
This is kind of a long lost art, forging your own horseshoes, who needs to match the analog characteristics of different transistors these days?
Well, you might.
If you’re building any kind of high power device with the transistors and you’re using a bunch of them in parallel to share the load, you want to make sure that one of them doesn’t run hot and then cascade out and take all the load itself.
Or if you’re building audiophile amplifiers, you want your push transistor and your pull transistor to be well matched with each other.
There are tons of reasons to do this, but raise your hand out there if you’ve ever thrown a bunch of transistors on your desk and pick the ones with the most similar hFE.
I’m guessing I’m the only person with a hand up right now.
Michael Fitzmayer, a tool for testing CANopen networks.
CANopen is a particular flavor of CAN networks, but this is actually a piece of software that works for basically any CAN network.
And it’s really neat.
It just gives you a terminal that decodes all of the signals going on.
It’s kind of Wireshark, but for CAN buses.
And that is really powerful.
It’s not limited to automotive, but I think you could do OBD2 with it.
And it’s not limited to CANopen, but you absolutely can do that.
If you’re playing around with CAN networks, give this one a look.
We actually covered a similar browser-based tool a few months back.
You’ll find that as well.
This one is sweet.
Just the basics in the terminal.
Last up, Elehobica, a digital audio recorder for Toslink.
This is really the simplest device in a way.
It’s a Pi Pico that understands the digital audio format that the various laser and Toslink audio transmission systems use and just takes the audio data and stores it to an SD card.
It’s an almost no-cost device that lets you take digital audio in and save it to an SD card.
This would have been the digital audio pirate’s absolute dream back in the early 90s.
And now it’s just a couple simple electronic parts and some clever software.
My first quick hack is running Linux on the PS5 with the Hypervisor exploit.
It’s a quick hack, so we won’t dig too deep into the exploit part of it.
But the short version is that there’s a firmware version 5 for the PS5 that is vulnerable to a software hack that will let you run Linux on the console without any kind of hardware modifications or without even overwriting anything.
It can just run in that instance and then you reboot and it goes back to being a normal PlayStation.
It’s very exciting if you’re into using consoles for things that are not playing video games on them.
Unfortunately, the PS5 is now on firmware version 6, so you would have to have a console that’s several years out of date is my understanding.
It seems like 2022 or so is when the five point whatever series of firmwares come from.
But there’s always secondhand ones and eBay and that kind of thing.
And hopefully in the future they can expand it further and be able to do a little bit more with your PlayStation than just play games on it.
Next up is a shortwave sensor to monitor the ionosphere and this is about as simple as an interface as you can get.
There’s a power switch and a little OLED that has a numerical value for propagation.
The way it actually works is seems that it just kind of picks up anything between 1 and 40 megahertz and amplifies it and turns that into an average received energy sort of value.
With the idea being that if there’s a bunch of under 40 megahertz stuff floating around, it must be bounced off the ionosphere.
That is maybe not the best assumption to always make because there could be various noises in that frequency range and other stuff that’s locally that could be screwing it up. But hey, it’s still pretty cool, rough indicator of what’s out there. And it’s easy enough to put together with an Arduino and a couple parts.
And then my last one is photographing the ISS with a thrift store lens is challenging. I think that’s probably an understatement slightly. This comes from Save It For Parts. And I got to say, every time something comes through from him, it’s almost cheating because everything he does is preposterous and extremely impressive. And I don’t know; I don’t know how the guy has time to live his life because it seems he’s always working on something crazy between whatever insane project he has going on.
He decided to go to the thrift store, grab a $15, 400 millimeter lens and then hook it up to a modern digital camera and was able to figure out where the space station is and grab a couple shots. To be fair, said shots are a little dot that’s transiting the sun. But still, it’s there, right? And it’s a pretty impressive accomplishment given the equipment involved.
All right, now it’s time for our Can’t Miss articles. These are long form pieces written by our fantastic Hackaday writing staff.
This week I got Zoe Skyforest’s
“How Giant Tanks of Fluid Could Help Support the Power Grid.”
And this is the story of vanadium flow batteries.
Well, I mean, the basic problem is that batteries wear out and lithium ion batteries are great for a long time. But then after five years, 10 years, they start losing their capacity. Not so with a flow battery. And a flow battery is kind of, at one point, the simplest battery you can imagine. And at the other end of things, kind of a little bit more complicated than a regular battery. And I’ll explain what I mean.
A regular battery, a flow battery works by having one chemical that has too many electrons and another chemical that has too few. And the electrons want to scoot over from one side to the other. So when you hook up the anode and the cathode, it completes the loop. The electrons can scoot across inside the battery and you’re done. With something like a lithium ion, you can reverse this process by putting power to it.
With a flow battery, you have the same chemical. In this case, it’s a fluid containing vanadium. And they’re just in two different ionization states. So on one side of the battery, it’s two plus. And on the other side of the battery, it’s three plus. That’s the whole gimmick. There’s a membrane in between. The electrons can diffuse across, but the vanadium ions can’t. And that makes the battery.
The flow is that there is a pump connected to a reservoir of fresh battery juice on both the positive and the negative side that literally just push fresh fluid through there. And so the battery itself is two big electrodes, a membrane in between, and then just this fluid pumped through the space in between them.
When you want to charge it up, you run the pumps and you put charge on the different plates. When you want to discharge it, you do the same thing with fresh recirculating fluid and you can get the electrons back out. It’s kind of the simplest possible battery in that sense. It’s complicated in that you need pumps and this is a whole big machine and it requires electricity to run the battery. And that’s kind of weird.
The upshot, of course, is that the electrolyte is easily replaceable. You never have to rebuild this battery. You can always just change the fluid out if it gets in trouble. It’s relatively easy to replace the membranes if they fail in 10 years or 15 years. When the pumps stop, you just put new pumps in line. It’s a lot more easily repairable and maintainable than a normal kind of than a huge array of lithium ion cells or something where when a bunch of cells goes bad, you have to undo it and put some new cells in. But that means basically scrapping those cells, right?
This one is a battery that you can kind of maintain in place and scale up and down kind of indefinitely. If you want more capacity, you just need bigger containers of electrolyte to pump through. If you want higher current density, you just have to scale up the part that has the electrodes. So it’s a really flexible battery technology. I mean, clearly the thing’s got a lot of freaky vanadium fluid and pumps. This is not a battery for you necessarily yet. This is a battery for co-locating with city-scale solar farms and even when that power’s out. And to that extent, there have been projects in China and Australia so far where they’re testing out this vanadium battery technology. And it looks like it’s working well. According to Zoe, some of these ones in Australia are, she doesn’t say making money, but generating significant revenue by smoothing out the solar peaks. So it remains to be seen if this is the kind of battery storage solution at scale for the future. But anything in that direction is a good thing to have because the sun doesn’t shine at night.
I like the almost—it’s almost like a childlike concept at first. Right?
“If the battery’s charged, can’t we just move the electrolyte?”
It seems something that’s too simple to work, right? But I guess it’s a great example that sometimes simple concepts—obviously the implementation of it is not so simple, right? But on paper, it’s okay, well, you got electrolyte and you got the electrodes and it’s already charged. So now what? Well, just pump in, pump, pump in new fluids and then you can charge those fluids.
It reminds me a little bit of the iron air batteries, which we’ve talked about a couple of times where again, this is, well, if I just rust metal, effectively, I just rust metal. Well, I can store power that way and then unrust it and get the power back, yeah, okay. It actually does work and it’s insanely cheap because it’s just a bunch of iron and, well, air is everywhere, except it’s huge. And it is not something that’s probably ever going to be useful for a portable anything.
Plus, I know the iron air—this actually talks about what the actual efficiency of the iron air ones are: super lossy. You get very little comparatively back compared to the other thing, the lithium is incredibly efficient in terms of getting the juice back out of it. Whereas a lot of these mass storage things are not, but again, if you’re charging it off of solar panels that are cranking all day, being able to recover 40% of that or whatever the number is, is better than zero. Which is what’s going to happen at night when the sun isn’t shining.
So it’s just interesting to see these kinds of alternate battery technologies that would really, if your focus is just on consumer electronics and vehicles, you would never, you would never even touch on this kind of research, but there’s obviously a demand for massive static batteries. We’re starting to see a lot of interest there. Yeah, it’ll be interesting to see more of this stuff develop.
And this is kind of the next logical step after pumping water up high and letting it come back down. This is a little bit, a little bit more advanced idea of storing energy in situations where the generation is super cheap and whatever you can get, you can get. Of course, this technology is awesome because it can scale up really big, but actually it can also do the opposite and scale down pretty small. I don’t think you’re going to be seeing flow batteries running any consumer electronics anytime soon. But if you want to play around with the technology yourself, you absolutely can.
And we’ve seen a few projects on Hackaday where people have started experimenting with this technology themselves. I’m going to put the links in the show notes for you. Again, it’s as simple as getting the right chemistry together, getting the right membrane together and pumping fluids through. It is not tricky at all. And actually, as I’m looking through Hackaday for this, I found one that Zoe just wrote up back in March that uses no pump. Instead, it uses the magnetohydrodynamic effect, which makes a bunch of sense because you’ve already got ionized fluids. Why not just push them along magnetohydrodynamically? And I think the answer is because it’s much more efficient to do it with a pump. Cool idea to make a no pump battery.
To answer your question about the efficiency, I went and looked it up, and they’re saying 75% to 90% efficient. Oh, wow. That’s not bad. It’s not at the level of lithium ion, but it surely is not at the level of the rusty batteries either. This is significantly more efficient than iron air. And what? 75% to 90% is kind of NiCad performance. So not bad. No super dangerous chemicals. I like it. I like it. Pump and membrane maintenance is the big downside. But at some scale, that’s not a problem relative to keeping an entire container full of lithium ion cells from going up in flames. Now I want to see somebody come to Supercon with a backpack, flow battery.
These ones we’re looking at here that you put in the show notes are surprisingly small.
Experimental but tabletop size.
Something you can play around with.
Well, this week it’s going to be a twofer for Zoe and energy storage, I suppose, now that I think about it.
This one is why leaded fuel is still a thing.
And I have to admit, I did not know it was.
So it was very interesting for me to read this one.
Long story short, AV gas used by airplanes.
And to be clear, this is not turbine-driven aircraft.
They use a refined kerosene.
But propeller-driven airplanes still use leaded gas.
And it’s even more lead than the lead would have had back in the day when you would have got leaded gas at the pump for your car.
The rationale is still the same as it was back for the cars.
And if you are not aware, I suppose increasingly more and more listeners would probably not be aware that there was lead in gas at one point.
It was largely to protect the engine.
It had a sort of lubricating kind of effect on the valves.
The theory at the time was not only did it help the engine run smoother, but it was good for the engine.
So, of course, we’ll put lead in the gas.
The problem, obviously, with having a bunch of cars burning leaded gas was there was lead everywhere in the environment.
And that turns out to not be so good.
So, metals inside the engine and lubrication technology improved.
So they stopped putting lead in the gas and just took up that challenge of making an engine that could run without it.
Doing that same thing on an airplane is a different proposition.
Obviously, airplane engines do not have the luxury.
You can’t just pull off to the side of the road if there’s a problem with your airplane engine.
So reliability is absolutely paramount.
Even as it is, an airplane engine has to be torn down and rebuilt every couple hundred hours, depending on the model.
So making that kind of change in airplane engines has been tricky.
And also, a lot of piston-driven airplanes, as you might imagine, a lot of them are fairly ancient.
Unless you’ve looked into it, you may not realize a lot of private airplanes.
It’s not unheard of to be
“I bought a Piper Cub from the 70s or whatever.”
They’re still out there.
And the second and third and fourth-hand market for these planes is very active.
It’s going to be very hard to get the momentum necessary to change all that.
The good news is it does not seem there’s a whole lot of these planes.
At least, the FAA in 2019 estimated that there’s 167,000 planes in the United States that are still using leaded fuel and less than a quarter million worldwide.
So that’s not a lot compared to, obviously, cars.
But still enough that there is some interest in trying to phase out the leaded fuel in the U.S.
It was originally supposed to happen years ago.
I think 2014, the FAA first tried to do it and get some proposals, and then it kind of just got kicked down the road a bunch of times.
And now the idea is to try to end it by 2030.
We’ll see.
It’s been delayed several times, and it could certainly get delayed again.
The goal looks to create a replacement fuel.
Because, again, getting all those engines rebuilt or changed is realistically not going to happen.
So they need to have some kind of a replacement unleaded fuel that has the same properties that the leaded stuff does with, namely protecting the engine parts and also increasing octane and all the stuff that an airplane engine needs that a car doesn’t.
So I thought the whole thing was really fascinating to hear that there is still a not insignificant amount of users of leaded gas and that even that is, in theory, on the way out.
So that there will be a time within maybe the next decade or so that finally even that kind of holdover will be gone, in theory.
We’ll see.
We’ll check back in 2030 and see how the leaded AV gas is doing.
I hope it’s the case that it can get phased out by then.
But you said, the age of some of the flying stock out there, especially if you’re talking about propeller airplanes, they’re not built recently.
They’re built from a time when it was hard to make engines lightweight and powerful enough to make airplanes work.
And so they had to use high compression ratios.
And so they had to use high octane fuel and leaded fuel was the panacea.
It was the “just add this cheap, environmentally toxic stuff and boom, you get the high compression ratios you need.”
That’s wild.
I didn’t know about this either. Of course, does Zoe talk about what the substitute fuels are made of? What—what’s the deal with them?
There are three that are competing to be the next standard for high octane fuels that will still work the same way.
The article does mention that it’s going to be a phase rollout.
They’re going to have more and more planes running these alternative fuels and then see how they perform in the real world. And there might need to be more tweaks and that kind of deal.
Again, nothing ever happens fast with airplanes, every kind of any kind of change needs to be very careful.
But, it’s happening.
So I started looking up these different fuels and they’re there for real.
The Aircraft Owners and Pilots Association is testing one of the new hundred octane fuels here.
And they say that this is a brand new article. This is from January of this year, saying they’re testing it out in a bunch of planes and it looks like it’s working well.
And that, so maybe 2030 isn’t unreasonable, actually.
Quote, this is a meaningful milestone as the aviation industry continues to make progress toward an unleaded future.
We congratulate VP Racing and LyondellBasell, which is the company that makes the fuel in question for the work they’ve done and blah, blah, blah, blah, blah.
That’s pretty cool.
Pilots Association is a founding member of the Eliminate Aviation Gasoline Lead Emissions, EGLE, Initiative.
Man. That’s a nice acronym. Love those acronyms.
So maybe it is possible. Maybe there is real movement underway to get the lead out.
No.
That does it for this week’s Hackaday podcast.
Thanks very much for listening.
And until next week, keep on hacking.
“I will not be managed.” You can’t manage me, man.
And the other, and the other entry in the mailbox, what, what was I going to do? It’s a wee, I already got stuff. It’s fine. Yeah, a lot going on. What is the title? I know I changed it. I don’t know. I guess I can’t say that.
Next up is a shortwave sensor to monitor their. Oh no. What is it? Episode 370? 67. No, it can’t be 367. Wait a minute. No. How could it be? The one on the front page says 368. Right. So 367 is after 368. 369 is after 368. Holy shit, man. I’m cooked. Numbers go up, dude. I just, wow. Wow. That I forgot that numbers go, why, how is that possible that I, man, that’s got to be a symptom of a brain tumor or something, right? I got to go, I got to talk to somebody. Okay.
2026-04-22 08:00:01
Designing Data-intensive Applications with Martin Kleppmann
Designing data-intensive applications has been the go-to book for anyone building large back-end systems. Nine years after publishing this book, the second edition is here. Martin Kleppmann is the author of this generational book. I sat down with him and today we cover how working on Kafka at LinkedIn directly shaped the ideas that became the first edition of the book. What’s new in the second edition and why things like MapReduce got removed from this updated version. Formal methods, local-first software, decentralized access, and many more. If you care about how large systems work, where they’re heading, and what the fundamentals are that don’t change, this episode is for you.
This episode is presented by Statsig, the Unit 5 platform for flags, analytics experiments, and more.
This episode is brought to you by Sonar. Sonar, the makers of SonarCube, understands that code quality is about more than just avoiding syntax errors. It’s about long-term maintainability by protecting the structural integrity of the system. As agents generate code at massive scale, they often ignore your system’s structural integrity. This creates tangles, duplicated code, and other maintainability issues. These issues turn a modular design into a big ball of mud, making it increasingly difficult to extend.
But here’s something that’s really helpful. SonarCube’s architecture management.
Whether it’s a human or an AI agent at the keyboard, Sonar acts as a circuit breaker for structural decay. It ensures every commit respects the system’s blueprint, protecting the long-term health of your most complex applications. Head to sonarsource.com slash pragmatic to find out more.
So, Martin, welcome to the podcast.
Hi, Kaka. It’s great to be here.
It’s amazing to have you here. I don’t think you need introduction to many software interns, including myself. You’re the author of this iconic book that I’ve had on my bookshelf for probably about 10 years, not much longer after it came out. Before we get into this book, which we’re going to talk about, how did you get into the technology field?
Yes, well, I did an undergraduate computer science, like many others. And then after that, I wasn’t quite sure what to do with my life, but I thought, well, it’s starting a startup seems like an interesting thing to try. So I started a startup having no clue what I was going to actually do and then spent the first while searching around for things that might be interesting. The first startup didn’t work out that well, but through that, I met some others who then became my co-founders for the second startup, which work better. And we sold that one to LinkedIn. And then after that, I started being interested in teaching these distributed systems concepts. So that’s when I got into writing the book. And then during the writing of the book, I also switched over from industry back to academia.
Can we talk a little bit about your first and second startup?
Yeah, GoTestIt, this was 2008 or something like that.
It was the age where people were having really difficulties getting their JavaScript working cross-browser. Internet Explorer was still pretty big at the time. Chrome had just come out. All the browsers were incompatible with each other. And so GoTestIt was a cross-browser automated testing service for websites. It was based on Selenium, an open source project that still exists. And the idea is you would write test scripts that automate a user clicking through the various interactions with a website and then just check that the right behavior happens. And so, yeah, it was based on Selenium, but just as it provided as a hosted service. So people wouldn’t have to run various VMs with various operating systems themselves. It worked technically, but I found it really hard to actually get adoption for it. A lot of people building websites like in theory said, oh, yeah, this is great. We need to test cross-browser. And in practice, actually, it was really difficult to get them to integrate it into their workflow and just get in the habit of using it and investing in writing the test scripts. So that ended up not really going anywhere.
So it’s like there wasn’t like a business to be done or like revenue to be generated in a meaningful sense?
Yeah, well, there’s at least one other, maybe two other companies from that same era that did manage to make a business. Source Labs is one that managed to actually succeed. But even for them, it was a pretty slow running business. I think it was not an easy business to be in.
And for the startup, were you in the UK building it? I was in the UK at the time. Was it bootstrapped? Did you raise some kind of funding?
How big was the team?
How can we imagine this?
“It was mostly bootstrapped.”
So I did a bunch of consulting in order to fund hiring some people and then hired some friends on the cheap to help contribute to actually building the product. And so it was done all very cheaply. I had a very small amount of angel money in there, but mostly bootstrapped.
And then when you decided to not go forward with this, how did the next startup come?
“Rapportive, right?”
Yeah, the second one was reportive. That went a lot better.
So that was putting social media inside Gmail, basically. So the idea was that if you get an email from someone you don’t know, we had a little browser extension which manipulated the Gmail web interface so that on the side next to the email, we’d show you a summary social profile with a profile picture and a job title pulled from LinkedIn and recent tweets pulled from Twitter and maybe recent Facebook posts or things that. So just whatever we could find about that person and put that as a social summary next to the email.
We started in 2010 or something. It pretty quickly became quite popular. And so on the back of that, we were then able to raise some money from Y Combinator, which was still fairly young at the time. That was very young. You must have been one of the very early batches. Yeah, I can’t remember exactly when they started, but it was certainly in the early years. I think Y Combinator had already built up quite a good reputation at the time, but it was still fairly small.
And then as part of Y Combinator, did you have to fly from the UK to San Francisco to attend that 10-week program, if I remember? Exactly. Yes. So we initially came for the three months or whatever it was of the Y Combinator, but then we were able to get US work visas for ourselves and set up permanently in San Francisco.
How was that shift from the UK, where you spent going to university, your first startup, the first part of this, to coming to San Francisco? It was very exciting because it felt like going to the center of where it was all happening, really. And we, at the start of that, not knowing anybody at all, we knew one or two people in the entire Bay Area. But we contacted them and they introduced us to more people and they introduced us to more people. And so we were able to pretty quickly actually build up a network. And that’s something that I really appreciated, that it was actually so open to outsiders like us who could just basically turn up with an idea and an early stage startup. And we managed to raise some money and managed to, actually become somewhat established in the Bay Area.
And can you tell me how the company grew and at what point did the LinkedIn acquisition offer come? And how can we imagine you were a founder of this company? “It was about in 2012 that we sold it and we were five people at the time.” So it’s all still pretty small, not vast amounts of money involved, but it was a success, I would say, for everybody involved.
The acquisition process itself was fine. It’s, as always with these kinds of transactions, there were twists and turns and moments where we thought it would all fall apart. And then we were almost running out of money and hadn’t really succeeded in raising another round. So we kind of had to sell or shut down. So we were under quite a bit of pressure. We couldn’t reduce our own salaries because to do so would have violated the conditions of our visas. Yes. So we were in a slightly stuck situation. Given our lack of leverage in that situation, actually, I’m pretty happy how it all turned out.
Yeah, it’s nice that, from 10 plus years, we can talk about this, honestly, because oftentimes you see an acquisition by LinkedIn. And of course, you might ask the founders and they would say this was either our dream or our goal or we will do so many things together. But some things that you don’t often hear is, well, that there was a pressure involved as well.
So did you go into this wanting to sell the company because you saw that things were getting a little, either you need to raise a new round or you sell to someone and then you found LinkedIn to be the best of or the only or the best option to go into?
We tried a little bit to see what revenue generating options we had and hadn’t really managed to make that work. So we were just burning money and our user growth was OK, but not really enough to go and raise a big round. So we were a little bit stuck there and selling the company seemed the least bad option there in a way.
And I’m pretty happy how it turned out because LinkedIn was great, actually. They were very good to us. They allowed us to operate as essentially an independent team within the company. So your team stayed together. Our team stayed together. We continued working on the product that we wanted to make.
“Oh, you got to keep working on Rapportive.”
“Yes.”
“Well, Rapportive, the Gmail browser extension, sort of got put on live support, but we were working on a new product at the time, which did eventually get released under the name LinkedIn Intro.”
It kind of got a slightly weird reception at the time and it ended up getting shut down shortly after we released it.
That’s kind of longer background story there.
But I’m still really happy with LinkedIn, how they gave us the freedom to do this and allowed us to launch this product.
And even though it didn’t succeed, they were very good to us throughout that process.
And then after that got shut down, then our team got disbanded.
But we had a good run within LinkedIn building this product.
What tech stack did you work at the time?
What did you use?
Rapportive was fairly unexciting.
It was a Rails app with a Postgres database, basically, and some Redis and some similar things mixed in.
So nothing particularly revolutionary.
We essentially built a graph database on top of Postgres.
So there was a little bit of technical interest in there, but nothing particularly outrageous.
And then you spent time after LinkedIn Intro.
You still work inside LinkedIn.
As I understand, you worked on data infrastructure, right?
“Yes, data infrastructure.”
After our team got disbanded, I switched over to the stream processing team.
So Kafka had just been developed at LinkedIn and had just been open sourced at the time.
“Yeah, they developed it, right?”
“Oh, it was just being open sourced.”
“Yeah, I think it had just been open sourced.”
And then I got to work on Samza, which was a stream processing framework on top of Kafka.
I always wanted to ask this question, so this again comes here.
Why did LinkedIn build Kafka or develop Kafka?
Every time it’s now such a fun foundational technology, I was always curious, why did a company feel the necessity to build this thing that seems pretty generic and it seems everyone would have needed it?
Yes, so I think Jay Kreps has a pretty good blog post from that era called “The Log”, where he explains his motivation behind Kafka and why make it an append-only log rather than a traditional message queue or something of that sort.
I think the motivation was really about data integration because there were a whole bunch of databases and event-generating systems, activity events from users, for example.
They were all generating data that’s in a sort of stream shape and then a bunch of downstream systems that wanted to consume this, wanted to get it into the data warehouse and wanted to be able to get it into the Hadoop cluster at the time in order to run machine learning and things over it.
And there was just this data integration problem of how do you physically get the data out of one system and into another?
And Jay designed Kafka as this integration point, essentially almost the kind of lowest common denominator, but still a general-purpose abstraction for integrating various data sources and to downstream data syncs.
Working at LinkedIn at Kafka and at LinkedIn scale, what did you learn or what surprised you about working at this type of scale?
So, as I understand, this was the first time that you hands-on worked at a really large system, right?
“That’s right, yes, because previously the biggest company I had worked in was Rapportive with five people.”
We had a sizable database, but it was still a single-instance database and not really that big in the grand scheme of things.
And then, suddenly I was at LinkedIn and we got to use their big Hadoop cluster.
That was fun, hand-coding MapReduce jobs in Java at the time.
And so I learned a huge amount there, especially when the stream processing ideas came up and Jay was evangelizing the use of Kafka and the things you could do with it.
That was kind of a revelation for me, where I suddenly felt this kind of makes sense.
I start to understand how these various data systems fit together, what they have in common, what the fundamental principles are.
And so that experience then fed directly into the writing of the book.
At what point did you decide to leave LinkedIn?
To me, in your careers, I’m looking through the career, start out in the UK, do a startup, do a second startup by a combinator, move to San Francisco, get acquired by LinkedIn.
And the arc that most people would draw would be, okay, do something more in Silicon Valley or maybe start a second startup, et cetera.
And instead, you decided to leave LinkedIn.
“Yeah.”
So first I decided to move back to the UK, and I continued working for LinkedIn remotely.
“Okay.”
That was mostly because my girlfriend at the time, now wife, was still in the UK and long-distance relationship is not a lot of fun. And I didn’t feel that at home in the Bay Area. So I wasn’t really encouraging her to move to the Bay Area either. I thought it was better for me to go back to Europe. And I’m very happy with that decision. I still have a lot of great friends in the Bay Area. I love it as a place to visit, but I wouldn’t want to live here, honestly.
Then I was still remotely working for LinkedIn and that worked all right for a while. When I then started writing the book, LinkedIn even gave me 50% of my time free to work on my book alongside my software engineering duties, which is really great.
“Amazing.” “Yeah.” “That is so nice of them.” “Absolutely.”
And they don’t have to do that. And LinkedIn didn’t directly get anything out of it in response other than a book that they could use for internal training purposes. “Well, shout out to LinkedIn for this.” Yeah, absolutely.
Though then I did find then that actually trying to write a book in parallel with doing a software engineering job and being on call, etc. I just wasn’t able to do it. So it’s just too much context switching. And it’s very easy for the urgent things from the on call to dominate and then not to have the freedom that you need in order to write something new. And so then after a while I decided, okay, it’s probably better if I focus full time on the book. So I then left LinkedIn and just took a sabbatical, unpaid sabbatical, i.e. unemployment to just focus full time on the book for a while. And then it’s only after that that I actually even considered getting into academia.
“So how did the idea of the book come?” “What was the point where you decided you would write?” “And in your mind, what were you deciding to write?” “Was it already, this book with this layout or you had an early idea back then?”
I had an idea that, of course, the final product ended up looking somewhat different, but the overall goal, I think, stayed the same. So what I knew I wanted to write something that was a broad conceptual overview. So not about how you use any one specific system or tool, but comparing the trade-offs between many different types of tools. And I knew that I wanted to be practitioner focused, not a theoretical textbook, but something that people could use to build real systems. That was basically the goal with which I approached it.
And this was exactly the book that I wish I had had when I was starting out and working at Rapportive, for example, because we were all searching around in the dark where we’re having performance problems with our database. And we had no idea what to do, basically, because we were totally lacking the foundations to actually understand what was going on and how to diagnose the issues. And so I felt that, well, if I’d had a bit more background on how these data systems actually work internally, then I could have had an intuition about how to debug these kinds of performance issues. And then after a while, after I’d learned more about how data systems work, I thought, well, okay, it’s time to write this down so that others don’t have to learn it the hard way, but can hopefully just get a better idea of how these systems work and thus be better at managing their own data systems.
To start with, how did you learn about, for example, how databases work? Because again, from your story at Rapportive, you build systems, you’ve had some performance issues at a smaller scale, to be fair, compared to LinkedIn. Then you worked at LinkedIn and you saw a little bit of how the sausage was made. But I know a lot of software engineers who have been in this path and they still don’t really know how the fundamental systems work. They just know, okay, we have a platform team inside our company and they build it. I could read the RSCs, but it’s a lot of work. Or the planning docs, I could look at the source code. It feels to me that even at that point, you just went down and tried to dig in. What resources did you use? How did you find out those basics which you later put into the book?
A lot of it was just kind of being curious and talking to people, actually, and just asking them lots of questions. At LinkedIn, there were a bunch of senior data systems engineers who understood this stuff very well, but hadn’t maybe necessarily written it down. And so I just talked to a bunch of them and quizzed them and that way started building an image in my own mind of how this stuff works. And then once I sort of got the basics from these conversations, then I was able to go and read research papers, for example. They go into much more detail of exactly how and why things are designed in such a way. But it is time consuming to read those things. So then what I tried to do was pull out what are really the essential ideas. I just read a ton of blog posts as well. And so the reason why you see so many references at the end of each chapter in the book is, well, that is actually the material that I myself used in order to understand what was going on. And then I thought, well, okay, well, if I found these things useful, then I’ll also cite them in the book as a way for anyone, any reader who wants to go beyond the basics covered in the book. Here are some good sources to further reading.
The structure of the book, this first book, at least, is foundation of data systems, distributed data and derived data. If I understand these are three big parts. Did you already have a structure in mind when you started writing the book or did it shape as you went?
This three-part structure is not that critical in the design of the book, really. That’s sort of more after the fact. I thought, oh, well, it seems we can group the chapters into roughly this sort of structure. But the topics of the chapters were more or less what I had envisaged.
So I knew that I wanted to talk about what a transaction actually is. I knew that I wanted to talk about replication. I knew that I wanted to talk about sharding or partitioning. I knew that I wanted to talk about consistency and consensus. Those sort of high-level topics, I think, were clear from my initial book proposal to the publisher.
The details within each chapter, that is something that I often figured out once I got to that chapter. So I wrote one chapter at a time and started each chapter work with just a lot of background research to actually get up to speed on the topic myself. And it’s often only then that, for replication, I decided, okay, well, it seems the three major ways of doing this are single leader, multi-leader or leaderless, okay?
I would decide on that structure essentially when I started writing each chapter and then try to fit the various points I wanted to make into this narrative structure.
As a fellow author who also wrote a book, one thing I’ve noticed, there’s a bit of parallels between estimating a book and estimating a software project and that you come in with an estimate. And if you’ve never done it before, you tend to be wildly off. How was this in your journey? And in addition, you also had a publisher and publishers are a little bit like project managers. They like to have a schedule. They like to try to keep you on track. They like to ask
“what is it done?”
How did you manage that part as well? And in the end, how long did you estimate it would take, when you started, and how long did it actually take?
As always, it takes vastly longer than expected. It’s the same for software and projects as it is for writing, I think. So I think it took me about four years to write the first edition. That was not four years of full-time, maybe two and a half years of full-time equivalent or something like that, but written over the course of about four years. So it definitely took a long time. The publisher deadline I missed by a ludicrous margin. I think I missed it by about two and a half years or something like that. But fortunately, O’Reilly were pretty laid back with the first edition and were happy for me to just take my time and make it good. When it came to the second edition, then actually O’Reilly got a bit more aggressive and pushy about sticking to deadlines. I guess by that point, the book had been established and people were waiting eagerly for the second edition. So I kind of understand the desire to want to accelerate it. But at the same time, I really appreciated the freedom that I had for the first edition to work on my own schedule. And I had a bit less of that with the second.
The tagline for the first edition, which I believe is the same as second edition, is “the big ideas behind reliable, scalable and maintainable systems.” Reliable, scalable and maintainable. What do these objectives mean to you?
Yes. So they’re all slightly vaguely defined, right? So there’s not a formal definition of those things. But for me, reliability means fault tolerance primarily. So meaning that a system should, on the whole, continue working even if a network link is interrupted or a node crashes or something like that. So a lot of the book is about techniques that support fault tolerance, like replication, for example. So that’s reliability.
Scalability is one of those terms that get thrown around a lot. And it’s sort of so much. And it’s fashionable and cool to make things scalable, because it suggests success and millions of users. And so that’s, of course, everyone wants things to be scalable because everyone wants success. For this book here, I tried to take a bit more dispassionate kind of approach and said scalability is just what mechanisms we have for dealing with changes in load. If load increases, how can we add computing capacity to a system, for example, so that the system still continues working?
And then the techniques that you use to achieve scalability, well, they are sharding, for example.
But in this case, scalability, your definition, do I understand that you’re mostly referring to horizontal scalability so that you cannot compute up or down pretty much?
I guess because that’s the more interesting one. Yes, you can always buy a bigger machine. And what’s interesting about that? There’s just not that much to be said about it. There are details of how you scale even on a single machine.
But I think part of what has become interesting about modern cloud services, just back end services in general, is how they’ve introduced this idea of horizontal scalability and shared nothing systems.
So we can build systems that are able to cope with very high load, even if the individual components are just fairly cheap commodity machines.
But maybe part of the scalability story, which I wasn’t thinking about as much at the time, but started thinking about more recently, is not just scaling up, but scaling down as well.
So actually, how do you run a service in such a way that if it has a very small amount of load, it’s really cheap to run it?
That’s the same question as how do you continue running a service if it has very high load?
Generally, you just want the cost and the computing capacity to be roughly proportional to the load that you have.
And at the low end, that means being able to scale down to something that is extremely cheap to run.
That’s not necessarily given.
That’s something that is hard with on-premises software, for example, because if you’ve got a physical machine, that’s a unit of deployment.
Yes, you could carve it up into two dozen virtual machines and make those small virtual machines. But it still requires some sort of resource allocation.
So part of what’s interesting about some serverless systems, for example, is their ability to scale down and say, if you’re going to handle just three requests per day, that’s just fine as well.
“Can you tell me about the second edition?”
“When did the idea come about?”
It had been clear for a couple of years that the second edition was needed just because the first edition was getting a bit dated.
There were changes in technology that hadn’t been reflected in the first edition.
So I wanted to update it, but I now have an academic job. I’m doing research, and teaching is my main thing. Updating the book is a sideline business.
So it took quite a while to make progress with that because I was always doing it alongside other projects and essentially back to that context switching problem that I had while writing the first edition.
But just now with an academic job that I didn’t want to drop because I quite enjoy it. Initially I made very slow progress with the second edition.
And I realized that I had slightly lost touch with current industry practices because I’d switched over to the academic side.
I’d gone much deeper on the theory, but I was no longer up to speed on what people were doing with data lakes.
So then at some point, I remembered Chris Riccomini, an old colleague from LinkedIn. I had worked with him on the stream processing stuff.
“You worked with him.”
He’s the author of The Missing README.
Wow, what a small world.
I had read Chris’s book, The Missing README, and thought he’s a great writer. I had worked with him as a software engineer and found him a great colleague.
He had been writing this newsletter called Materialized View on latest trends in data systems, essentially, and had become a startup investor in that space.
At some point I thought I have to get in touch with Chris and ask him whether he wants to help out with the second edition. He was keen to do that.
That turned into such a good collaboration because he was up to date on what the cutting edge was in terms of technology in industry. I had strong opinions on how to teach.
So how to explain things in the book: make sure that we were explaining everything in a way that was very precise, with carefully chosen words, but at the same time very accessible, so that it’s pretty easy to read.
We took my writing style plus Chris’s knowledge of latest industry trends to bring the book up to date. That was a great collaboration.
What are the big things that you added that and which ones of these you knew would be missing and which ones did you realize during the writing process that, OK, this needs to be in here now?
Yeah, so the thing we knew from the start that we wanted to reflect was cloud native systems architecture.
It’s a bit of a vague term. But what I mean with that is essentially building data systems on top of cloud services as the foundational abstraction.
In the first edition, the assumption was basically that you have some machines. Each machine has some local disks. You can run the database instance on a machine. It will write its data to the local disk. If you want to replicate it to another machine, then, the database software will replicate it at the database level to another machine, which will also write the data to its local disks.
For a long time, that was exactly the way computers worked. And now suddenly people are building databases on top of object stores, for example. And now the replication happens at the object store level, no longer at the database level. Or maybe there’s still some replication at the database level, but it really changes the nature of things if you’re building on top of an object store. This is different from, say, building on top of a virtual block device like EBS, because these block devices, although they are cloud services, still offer the abstraction that is a sort of single node operating system abstraction of a block device on top of which you run a file system. Whereas an object store is a brand new abstraction. It just looks different from a file system. It behaves differently. And so then building on top of that as a foundational abstraction is something that people were starting to do at the time of the first edition.
Since the first edition, that has really taken off; a whole lot of systems have been built in that style now. And so that’s an idea that we really wanted to incorporate. And we weave that in throughout the book. So it’s not just one section here, but it’s an idea that we’ve integrated throughout the entire narrative.
There are now a lot of managed services as well. The primitives that we use, but there’s also so many managed services that all the cloud providers use. A lot of engineers often just use the managed services as is because they take care of replication. They have SLAs for uptime and so on. But when you build on top of these things, then you kind of use those as primitives as well.
Is there any risk as a software engineer that you’re no longer incentivized to understand the underlying layer? Or are we building better systems because of that? How do you think about this?
It feels there’s a move of abstraction because of cloud, right?
Yeah, it’s definitely a shift to different and higher level abstractions. But, that’s been the story of the entire computing industry since the start. It’s building new abstractions. So it is true that if you rely on a higher level abstraction, you’re no longer thinking about the lower level details. If you’re using a programming language with a garbage collector, you’re no longer thinking about memory allocation; is that a loss? Maybe: if you’re building low level systems, you should still have to care about memory allocation. If you’re building higher level business logic, it’s fine for people not to care about memory management. I think there’s an analogous thing here with data systems: if you’re building the higher level systems that don’t need to particularly care about the underlying infrastructure, then that’s fine. Just use the higher level abstractions. Nothing wrong with that. But somebody still has to build those lower level abstractions and form lower level components. Somebody’s got to implement the cloud services.
Martin talked about tradeoffs that come with using cloud services. And this is a good time to talk about our season sponsor, WorkOS.
If you’ve read Designing Data Intensive Applications, you know that building systems at scale is all about tradeoffs. But one thing isn’t a tradeoff, that’s enterprise features. The moment you land bigger customers, you need:
All the things they expect out of the box. Building that yourself can take months. WorkOS gives you APIs to ship it in days so you can stay focused on your core product. That’s why companies like OpenAI and Anthropic run on WorkOS. Visit WorkOS.com to learn more.
I’d also like to mention our presenting sponsor, Statsig. Statsig built a unified platform that enables both experimentation and continuous shipping. Built-in experimentation means that every rule-out automatically becomes a learning opportunity with proper statistical analysis showing you exactly how features impact your metrics. Feature flags let you ship continuously with confidence.
And because it’s all in one platform with the same product data, teams across your organization can collaborate and make data-driven decisions.
To learn more, head to Statsig.com/pragmatic.
With this, let’s get back to Martin and the tradeoffs that come with using cloud services.
And so those people will have to then specialize even more in actually the details of how you engineer those cloud services, how you make them reliable, how you operate them, and so on.
The skills are still there.
It’s just a bit of specialization happening.
Some people can worry about the higher-level things without having to concern themselves with the lower-level things.
Some people focus on the lower-level things and treat the higher-level aspects as their customers.
“Interesting.”
So it sounds to me that if you’re an engineer who is utilizing a lot of these services, you might not need to know how they exactly work.
“Yes.”
And I would say, the underlying philosophy of the entire book is to give people insights into just the sort of essence of how the systems work internally.
So that if, for example, they start having weird performance behavior, you can have a bit of intuition for why it’s doing that and how you might solve it.
So, for example, say the storage engine chapter tells you about how B-trees work and how log structures, LSM trees, storage engines work.
And the book is not intended for people who are going to actually build their own databases and implement their own storage engines.
If you want to do that, you have to go much, much more, much greater depth than this book covers.
But the idea is that, as an app developer, if you know just a little bit about how the storage engine works internally, you’ll be in a much better place to use it in a way that gives you good performance, for example, and to diagnose any issues.
That philosophy we’ve kept also in the context of cloud services, where, yes, cloud service hides some of the operational details that app developers don’t need to think about anymore, but they should still know a bit about how they work internally just so that they can use them effectively.
Yeah, I guess I’ll argue about the trade-off deciding on which service to use, which characteristics to look out for for your use case, right?
“Exactly.”
And there are huge differences of, say, if you’re doing analytics, whether you’re using row-oriented storage or column-oriented storage.
That’s a bit of a technical distinction and takes a little bit of background reading to even understand what that means, but it has a massive performance implication in terms of the final behavior of the system.
And so those are those places where I feel knowing a bit about the internals is actually a superpower.
Yeah, and I guess, engineers, the one thing that we always need to argue about or should need to argue about is, at the very least, cost versus performance.
And by performance, I mean, latency to the user and, of course, resilience of if something happens, a region, a zone goes down, a machine goes down, a zone goes down, a region goes down, how our product is affected and what’s acceptable.
The basic idea there seems to be how much availability risk are you willing to take on versus the both the overheads in terms of the system itself, the computational overheads, but also the human overheads actually designing and operating the system.
And the cost overhead.
And so, yes, you can have a system that is more able to tolerate various types of faults, but which is more expensive to design and operate versus a simpler system that might go down a bit more often, but which is cheaper.
And there’s no right and wrong with that, everyone needs to figure out where they sit on that, on that trade-off space themselves.
And I would say that multi-region is pushing in the direction of higher availability because it means you could tolerate the outage of an entire region.
But then it has implications on the consistency model that you can get across different regions, for example.
So that’s a trade-off that the book tries to make very explicit to help people reason that through of what is the right choice for them.
In terms of multi-cloud, for example, one thing that I’ve been concerned about just in the last month, really, is European dependence on U.S. cloud services.
So what if geopolitics was to go horribly wrong and tensions escalate and Europe finds itself suddenly locked out of U.S. cloud services?
“I hope that doesn’t happen.”
I still think it’s fairly unlikely, but it’s no longer unthinkable.
And as a result, I, coming sort of from this European perspective, have been thinking a fair bit about how can we engineer systems to be resilient against that sort of thing. And that’s not just a regional outage, but it’s a business risk, essentially.
And a multi-cloud system setup could help mitigate against that sort of risk so that, at least, for example, if one company locks you out, then you could still have systems on another company.
Again, that’s very much towards the expensive but high availability, risk reduction end of the spectrum.
But for the people who have really critical workloads where they think this sort of geopolitical risk is a significant enough risk, I think it’s seriously worth considering that kind of setup.
I’m thinking that, as engineers, we do have the responsibility, because
who else will do this?
Yes, totally.
But I totally agree with you as well that this understanding what the risks are and communicating what the trade-offs are, I think, is going to be a core part of our role as engineers moving forward as well.
Maybe as AI writes more and more of our code, it’s less about the details of how you express logic in a particular programming language and much more about those kinds of high-level trade-offs.
How has the definition of scale changed in this book?
Because as we talk with cloud, before cloud, building a scalable system, it sounded pretty involved.
Because building a horizontally scalable system is complicated.
All the pieces you need to put in.
In the first book, you detail a lot of this.
With cloud, a lot of the services, actually, they do define how they allow horizontal scaling, what the trade-offs are.
Do you feel that it’s made it a lot easier to reason about scale, scalability, when you are using these primitives?
So I think achieving really high scale is still challenging, because even though we have cloud services like object storage, for example, which provide you this very elastic storage model, at least you don’t have to worry about capacity planning on your disks anymore.
And running out of disk space, because those kinds of operational things are being taken care of.
But if you need sharding, for example, that’s something that actually does reflect on the application code as well.
You can’t really make that entirely transparent.
And so, at a sufficiently large scale, sharding is required because a single machine is not powerful enough to process your workload.
Then I think, even with cloud systems, you still have to do quite a bit of engineering thinking of how to realize that.
Where I think the cloud has helped quite a bit is actually at the lower end of scaling down.
If you want to have a very lightweight service that processes only a small number of requests, what we’ve got with serverless systems being able to very quickly spin up and spin down an instance, very lightweight.
That’s quite a good innovation that has enabled those very low scale services.
And that’s something that would be much harder to do without cloud services, because you would have to statically allocate a certain amount of memory and certain CPU resources to a particular virtual machine.
I love serverless.
I have a small website that runs on serverless, and my bill is 13 cents per month because it has very little load.
Absolutely.
It’s just making more efficient use of computational resources.
Let’s talk about sharding.
Fewer engineers have to actually implement sharding.
With cloud-native systems in your research, what have you seen?
What are the cases where putting sharding in place is still important, and where are the places where it might have just disappeared as a concern?
It’s still nice to know, but you might not have to implement it.
I think it’s probably less of an effect of cloud and more of just hardware getting more powerful.
That, actually, a big machine nowadays can do a lot on a big machine.
And that means that more and more workloads you can just run on a single machine, and that is sufficient, actually, to achieve quite significant scale already.
There’s still concerns of how do you actually efficiently make use of hundreds of CPU cores that you have on a single machine?
So parallelism is still a required thing to think about there, and sharding is one way of achieving parallelism.
But at least this sort of sharding across multiple machines has maybe become less of a pressing issue just because more and more workloads can just run on a single machine. Some people still have very large-scale workloads that do have to be sharded across multiple machines, so it’s not going away entirely. And replication is still relevant even at smaller scales because that’s for fault tolerance. That’s not for scalability.
You have a chapter called The Troubles with Distributed Systems, which goes through a lot of things that can go wrong without going through the whole chapter. Can you recall some of the things that are memorable to you or some of the things that you feel are important to remember?
Yeah, the whole idea of this chapter is that in distributed systems theory, there are certain things that we tend to assume. For example, we just assume that there’s no upper bound on how long it might take for a message to go over the network. So you send a message, it might arrive within 100 microseconds, or it might take 10 years. And distributed system theory just doesn’t make any assumptions about that sort of timing if we can avoid it. Or rather, some theory does make those assumptions, but it’s a dangerous assumption to make because occasionally the network delay does become much higher than what is typical.
Another thing is about crashes; for example, distributed system theory just says nodes can crash. But what does that actually mean? What in practice does it mean for a node to become unavailable? Because it might be a software crash, but yes, it might be a hardware failure. It might be somebody unplugging the power cable. It might be that the node is actually still running, but it’s just become disconnected from the network.
The point of this book chapter really is to defend and justify those theoretical models that we use for analyzing distributed systems and just giving a lot of stories and case studies that show that actually tons of stuff does go wrong.
“Don’t believe anyone who says, oh, failures are rare. Don’t worry about it. It’s fine.”
The moral of this chapter is really that, actually, if you want to make things reliable, you really do have to worry about a whole bunch of weird, unusual, but certainly possible edge cases.
Timing is another one of those things. It’s very easy to assume that your clocks are correct and most of the time the clocks are pretty correct, but we just can’t rely on it because actually they’re just not precise enough on the whole. And so a lot of it is about it’s very tempting to make certain assumptions that things are well behaved and in distributed systems, we just have to try to get away from those assumptions if we want the systems to work reliably, even in the face of things going wrong.
But it was a really fun chapter to write because it’s essentially a big collection of stuff that has gone wrong. And so I went through a bunch of post-mortems published by various tech companies, for example, in order to see, OK, what was the root cause of how things went wrong and what kind of lessons can we draw from this that apply to the book in general?
And there’s some fun stuff like the sharks biting under sea cables and damaging them. That just makes for a great story. And then I hear that in recent years, the shielding of under sea cables has got better and therefore the sharks are not biting them anymore. But instead, the cows on land are stepping on cables and occasionally causing network interruptions that way. That sort of thing just makes it a bit more fun.
That chapter is so interesting also because depending on what kind of teams you work on or what kind of people you talk with, when I talk with the S3 team, for them that whole chapter is just their day-to-day. It’s not a weird thing when a hard drive goes up. It might be a weird thing to have a fire in a data center, but they’re prepared for all of those things. They’re at the scale where these things just happen on a regular cadence because they’re one of the largest scales. Whereas at a smaller company, even if you read this chapter you will treat this as, well, this could happen. When it actually happens, it will be a once-in-10-year and it will be a big deal.
Yeah, but I think there’s no right answer. It’s a tradeoff between risk and cost, broadly speaking. And that means a business decision has to be made in terms of where the business wants to lie on that tradeoff. And so the goal of this chapter is really just to give people the information in order to make an educated decision. But I don’t want to make that decision for people. That’s for businesses themselves to decide. That’s very clear.
Have you come across some concepts or systems mentioned in the book in the first edition and now in the second edition that are becoming either more popular or less popular over time? More or less referenced by your readers thinking about from things like streaming systems, batch processing or anything else?
Some things that we’ve been able to take out of the book compared to the first edition in particular, for example, coverage of MapReduce was quite detailed in the first edition.
“But basically MapReduce is dead.”
Nobody uses it anymore.
Its successors, in the form of Spark and Flink, for example, are used.
And so we still reference MapReduce in the second edition, but more as a learning tool in order to understand how these kinds of partition sharded batch processing systems work.
So that’s one thing where we’ve been able to reduce the coverage.
But other areas where we’ve increased the coverage are, for example, systems in support of AI.
Even though this is not an AI book, there are still data systems concerns that arise when needing to support AI applications; a classic one is vector indexes, for example.
We’ve added some coverage of vector indexes to the storage engine chapter.
It fits in really well there because it already covers various different indexing strategies anyway.
And so vector indexes are just another indexing strategy.
We also added some coverage of data frames, for example.
That’s not an exclusively AI thing, but data frames are quite a good data representation for training data, for example.
And that was not one of the data models that we discussed in the first edition, but we decided to add to the second edition because it has actually become a very important data model that people are using alongside all of the classic data models:
And so there are these places where we’ve just expanded the coverage a bit to reflect the kinds of systems people are building, for example, to support AI without it changing the direction of the book entirely.
The final subsection in this first edition, the first few subparts were titled Doing the Right Thing.
And in the second edition, this has its own chapter.
The final chapter is Doing the Right Thing.
And I echoed a little bit from it.
“We, the engineers building these systems, have a responsibility to carefully consider those consequences and consciously decide what kind of world we want to live in.”
Can we talk a little bit about this section and the importance of it?
Absolutely.
The motivation for putting in an ethics section there in the first edition was that I felt it had been quite ignored as a concern during my time in industry.
That was especially in startups; people were very focused on building a product that their customers would love and deprioritizing these sort of ethical questions in the process.
For example, with the consumer facing products, it might be that the products are very much geared towards essentially data harvesting, collecting behavioral data, because that’s what can be monetized in the form of advertising.
There seemed to be very little reflection on what was good and bad about these sort of things.
I really wanted to encourage a bit of thinking there.
Not really wanting to prescribe too much, a particular approach there, but at least to point out, there is this thing such as data protection legislation now, which we do have to think about in the architecture of our data systems.
There is an ethical responsibility.
People say that you get into tech in order to change the world.
If you want to change the world, then thinking about the impacts that your technologies have on the world is part of your job.
It’s a really essential part.
Something that engineers are often prone to ignoring is we focus just on the technology and less on the effects that that technology will have out in the real world.
This chapter is really an attempt to get people thinking about it a bit.
It’s sort of a reflection of my own process as well, because as I started working on these systems, I didn’t really think about ethical things particularly either.
I felt I had to put that section in there for myself as well as for the readers, because it was my own way of grappling with these questions a bit.
Is it fair to say that as engineers building these systems that will have an impact on a wide range of things, potentially societal wide impact, we are in such a good position to directly influence and maybe even change course?
Do I understand that this section is a bit of a reminder that by building it, we have a huge opportunity to shape these.
We probably have a lot stronger voices, maybe as strong voices as later on the regulator might have years down the road, right?
Exactly.
I think engineers have a very strong voice there. And we talked about earlier, engineers need to articulate trade-offs in such a way that business leaders can then make educated decisions about how to address those trade-offs.
And part of those trade-offs is pointing out risks and risks include not just technical risks, the data might get corrupted, but they include societal risks as well.
For example, what negative effects, what harms might arise from this technology, what sort of unintended consequences possibly, or what risk for reputational damage.
If it turns out that technology has some harmful effects, that can reflect badly on the company that made it.
And that has to be part of the trade-off discussion.
And I want people to make intentional and deliberate decisions about those kinds of things and not sweep it under the carpet.
One of the hot topics these days is, of course, AI.
“And you’ve written a very interesting post about this just in December, about formal verification and how your conviction that formal verification might be more important with AI.” Can we talk, for those of us engineers who have heard formal verification, can we talk about what this is and how you envision this becoming more important?
There’s a whole range of formal methods.
The more advanced level is to use actual formal proof.
And in that case, you can write a specification of some system in a formal language, usually using mathematical notation, and then make a mathematical proof that a certain algorithm or certain implementation always satisfies that specification.
And the distinction to testing there is that in testing, you try through a couple of examples, give the algorithm some example inputs and check whether you get the expected output in those particular examples.
But a proof can reason about potentially infinite state spaces.
So it can tell you things about every possible thing that could possibly happen in the entire universe, show that, for example, a certain safety property is always given in those.
Formal verification is a lot of work.
I never used it in my time in industry because it’s too time consuming.
I only got into formal verification when I was in academia and I could afford to take the time to spend a few months proving an algorithm correct.
But there I’ve started finding this very useful, especially if I was working on very subtle algorithms where it’s very hard to tell from reading the implementation whether this actually is always correct under all possible cases.
But if it’s an important algorithm where, for example, it will corrupt data if there’s a mistake in it, or it will have a security vulnerability if there’s a mistake in it, then when it’s high stakes.
And then I feel it’s worthwhile to have formal verification and to make sure that the code is correct.
And so I’ve done some formal proofs using the Isabelle proof assistant, for example.
There are a couple of others as well, Rocq and Lean and so on.
These proofs are really hard to write.
It takes a long time to learn the language of writing those proofs.
And then even once you know the language, it’s really laborious in order to write the individual proof steps.
And when you say it’s hard to write, as someone, I know how to code, there’s so many different languages.
Can you explain what it means to be hard to write?
Does it feel like a strict programming language with all sorts of rules or lots of math formulas?
What makes it hard for you to learn it and get good at it?
You’re trying to make a proof that a certain piece of code always satisfies a certain property.
In some cases, that property might be quite easy to specify.
Let’s say as a simple example, you have two lists and you want to concatenate them.
And then you want to prove that the length of the concatenated list equals the sum of the two individual lists.
Very, very simple property.
How would you prove something like this?
You would have a function that concatenates two lists.
And then you would probably do a proof by induction over one of the lists that shows that,
If you have one list of length i and another list of length 0, then the sum of the two is i.
If you have a list of length i appended with a list of length 1, then it’s i plus 1 and so on. And then by using a proof by induction, you can then show that the length of the concatenated list is i plus j, where i and j are the lengths of the two input lists for every possible value of i and j.
And this is something that in a test case, you would, in tests, you would maybe test it for the cases of
“And then you’re done.”
And j equals interior max. Yes. In the edge case, that’s what we do.
“That’s how I write my unit test.”
Exactly.
And so this is a trivial example, list concatenation. You can easily just read the code and convince yourself that it’s correct. But if it’s a much more complex algorithm, then our brains just can’t grok the algorithm well enough to really convince ourselves that it’s correct if you don’t prove it. And that’s where these proofs then become handy.
If I’m an engineer and I would be interested in getting started with formal verification, for example, because I have the notion that it will be more important with AI, of course, it will be easier to write these things. Where would you point engineers to get started, or how did you get started in this field?
I would suggest starting with model checking. So something TLA Plus or FISB are much friendlier to getting started with compared to proof assistants like Isabelle, Rocq, and Lean. These proof assistants just require a whole lot of additional knowledge. And the resources for learning about writing these formal proofs are, to be honest, not particularly good. I haven’t really found really great books on it as well.
The way I learned it was by working with some colleagues in my lab who had learned it through years of prior experience. And I just sat down with them and paired with them at a desk where I described the thing I was trying to prove. And they showed me how to prove it step by step, how to break it down.
I’m interested to see if you’re thinking will be correct, which is this thing will go more mainstream. And hopefully we’ll have better books and resources for it as well. Yes, I do hope so.
So the reason I think that I believe that this formal verification could become more important in the future is the kind of several aspects to it. One is that the LLMs are getting increasingly good at writing these proofs. And if we don’t have to write the proofs by hand as humans, it just becomes feasible to do them in situations where previously it would have not been economical.
But also LLMs increase the need for these formal proofs because we’re vibe coding a bunch of stuff. If we have to manually review all of that code, then that will become the bottleneck. So we can’t really have humans reviewing all of the generated code either if we really want to get the benefits of AI. So we need some automated way of checking whether the code is correct. And writing lots of tests is a very good starting point. But the thing that proof can do that tests can’t is to consider absolutely every possible thing that could happen. And that’s really important in a security context, for example, where it just takes one little bug to create a vulnerability that destroys the security of the whole system.
And so I feel for those domains where really we want to ensure there’s a complete absence of bugs, that’s the kind of places where formal verification can really shine. And I’m hoping that LLMs will actually make that a lot more accessible to people who would have previously not considered using formal verification because it was just too hard and too expensive.
You’ve worked in the industry and then you went into academia. Can you tell us what the difference is between us, myself and most people watching, work in what you would call industry, in the tech industry, or work at different companies? We’re bootstrapping our own or just building our things. How does academia contrast to this? What do you and your colleagues do inside of academia?
Yeah, within academia, there are lots of different styles, really. There’s not one thing. Some people go full-on theoretical, mathematical, don’t care about the real world at all, just want to work on things that are intellectually interesting, and that’s fine. And some people are very much at the applied end of wanting to do research that is likely to have a real-world impact. I’m more on the applied end, and that’s fine, too. But a common distinction there is that academia can just think much longer term. So if you’re doing a startup, you have to ship something within a few months. You can’t afford to think 10 years into the future. Maybe you’ll have sort of a long-term vision that you’re gradually getting towards, but you do have to really ship things on a fairly short timescale. At a bigger company, maybe if you’re working on infrastructure, so you can think on a bit of a longer timescale, because the requirements of what are needed are perhaps better understood. And in that case, making sure that the system is scalable, operationally robust, and so on. It’s then fairly clear what the requirements are, and it’s still a matter of implementing it. But in that case, you can think a bit longer term.
But in academia, what I really appreciate is the freedom to work on things that are long-term and which are not immediately commercially viable or which are not aligned with the incentives of commercial companies. So one research area that I’ve been on for several years now is what we call local-first software, which is this idea that we want to take away a bit of the power from cloud operators and give it back to end users. So end users should be more in control of their own data and less dependent on cloud services for providing the applications and the data that the users need. And that’s something that doesn’t naturally come to companies, right?
Because software as a service businesses, for example, the whole reason why they can charge a subscription is because they are able to essentially hold a gun to the customer’s head and say, “pay us your subscription. Otherwise, we will delete all your data,” and I totally understand the commercial imperatives that lead to that. But it also leads to this situation where the people have a gun against their head all of the time. That isn’t really a healthy situation to be in, in my opinion.
But changing that in such a way to take away that gun from customers’ heads is difficult if you’re in a business whose revenue depends on perpetuating that kind of lock-in situation. And there I feel, in academia, I have the freedom to work on things that go against this commercial incentive of companies and say, actually, no, I’m going to do what I think is right for the users. And I’m going to say the commercial model of the companies making the software is second priority. And I can afford to do that because I’m not dependent on this commercial model.
So add to this, it’s very interesting and challenging engineering problems, right? Yes, and it’s wonderful to get to work on interesting engineering and computer science problems, while at the same time trying to pursue this higher level vision.
For local-first software, what are some of these really interesting engineering challenges that we will need to solve or we need to solve to get to a more viable local-first software? May that be, let’s say, note-taking. It’s a very popular one, right? Yeah, so with our vision of local-first software, we are trying to get away from this dependency on centralized cloud services. There may still be cloud services involved in syncing data between your phone and your laptop, say, because often going via cloud service is just the most convenient way of establishing that kind of communication. But we just don’t want to have to trust on a cloud service providing a particular function. And if you can get away from assuming this one cloud service, you could, for example, have multiple cloud services on multiple cloud providers side by side, and you just sync by whichever happens to respond first or sync with all of them. And then if one of them disappears, no problem, because you’ve got the other one. And so it gives us a huge amount of freedom and flexibility if we get away from this assumption of centralized cloud services.
But that introduces a whole bunch of interesting research and engineering challenges because so one thing that we’ve been working on lately, say, is access control. Simple problem. You have a document. You want to be able to grant collaborators access, and you want to be able to revoke that access again. Totally obvious. It should be totally straightforward. In a centralized cloud service model, it is totally straightforward. Yeah, you have the rules. You confirm that those sort of things, and you check for the right roles, and that’s it. Yeah, but if you want to run your system over multiple providers or even in a peer-to-peer setting, then, well, what could happen is that a user gets their edit permissions revoked, and concurrently, that user makes an edit to the document whose permissions have just changed. And now:
And now those devices have become inconsistent with each other, permanently inconsistent. So that means, if we actually want to ensure consistency, even for this fairly basic setup, we now have to somehow figure out how to resolve the situation of an edit that is concurrent with the revocation of the user who made that edit.
Solving that problem, then, in a decentralized setting where we don’t have just a single server that can make that decision. In a centralized setting, you just have one server.
“It decides, did the edit to the document come first or did the revocation come first?”
And that one server makes that decision.
But if you have multiple servers, they might make different decisions.
So then, you could have a consensus protocol, but then consensus is messy because it requires some quorum votes and requires nodes to be online.
And so, we’ve been trying to do the whole thing without doing consensus, but while preserving high availability, while preserving the ability for users to work offline, preserving the ability to synchronize peer-to-peer without any servers, for example, that just makes the engineering challenge a lot harder.
And it’s solvable, and we are close to solving it for Automerge, which is the CRDT library that I work on.
But it’s just much less straightforward than it is in the centralized case.
But that’s a nice example of where interesting engineering challenges arise from this desire to get away from centralized services.
And then, we were just talking about clocks earlier, but an obvious thing that came to mind is, if all of them had the same clock exactly to the microsecond, you could just use a clock. You could use a timestamp.
But as you said, in distributed systems, we cannot always trust the clocks are synchronized.
So, I assume a lot of the things that you have been researching and writing about are just coming back to.
Absolutely.
And in this particular setting of a user getting their edit permissions revoked, if a revoked user still wants to vandalize a document, they can just backdate their edits, give it an earlier timestamp.
So, relying on clocks is absolutely useless here because people can forge the timestamps from those clocks and thereby potentially undermine the access control mechanism.
So, in this kind of system, we have to worry about potentially maliciously generated actions as well when the actions come from end-user devices.
This is fascinating because it feels to me that you’re solving a hard or maybe even harder engineering challenge than some startups would do because the startups would go the easy route.
They would take on a constraint, in this case, a centralized server, which makes business sense, makes revenue sense.
But because you are not doing this, you now need to look for a solution for a harder problem.
And if you solve this harder problem, you can give a building block that can move the industry forward, just give an option for either a business or an individual or an institution to have an option not just to centralize, but use this decentralized local first approach.
And then, of course, reason about the trade-off and decide whichever makes sense.
Exactly.
And that’s what I mean with this long-term thinking.
This is an example of it where, because it’s research, we can afford to take this idealistic, principled stance.
I said, yes, we’re going to solve this harder engineering problem because we think decentralization is a valuable feature.
And we know perfectly well that most startups are not going to solve this problem because they will just do the easy, pragmatic thing, which is the right thing for startups to do.
But we have a different set of incentives and we can afford to put in the time to try and solve those hard problems.
And as you said, if we can solve them, then it creates more optionality for anyone, any users of this technology.
They can, if they want to choose to use this decentralized tech, and there’s still trade-offs around it.
But at least if they’re not having to invent it from scratch, it’ll be a lot easier to adopt this kind of decentralized tech for those who want to use it.
So inside academia, you’re also teaching.
What courses do you teach?
I’ve got quite a lot of teaching this year.
So the distributed systems course, it’s available on YouTube.
Can you summarize what people who would go through this course, which, again, is freely available?
Thank you for you and the university for making it available.
What would they learn throughout those courses?
Yes, so that distributed systems course, it’s a bit more theoretical than what is in the book. So it’s more focused on algorithms and sort of how we convince ourselves that the algorithms behave correctly under the assumptions of distributed systems that we talked about, of nodes may crash. Communication might be unreliable. Clocks might be wrong, etc.
So that’s really, it’s not a very long course. It’s just eight lectures worth of material. But it goes into substantially more detail on the algorithms than the book.
So, for example, one of the lectures goes through the entire raft consensus algorithm, which is pretty complex. But I really wanted to show the students exactly how it works, because it’s just such a nice illustration of the challenges of distributed systems and the various measures we need to take in order to handle the various types of edge cases and failures that can happen. And showing that those problems can be overcome. > “It’s not easy.” The algorithms are very subtle and it’s very easy to have bugs in them. But it is possible to solve consensus in a way that works pretty well. And so that’s really the sort of message I’m trying to get across with this course.
And you mentioned that when you’re writing the book together with Chris, you brought a lot of industry inside and being up to date. Then you brought your experience of teaching and what works.
I don’t think I have a particularly unique teaching style. Just in lectures, I will go through slides. I like to annotate the slides by hand during the lectures. I’ve just drawn an iPad to make it a little bit more interactive. But other than that, it is fairly theoretical. That’s partly the way the Cambridge system works. It kind of favors theoretical and pen and paper courses over, say, implementation practical courses. I think it would be possible certainly to do a practical course on this. And I may incorporate a bit more practical exercise in the future. But right now, it’s mostly a theoretical pen and paper course.
The cryptography course that I do is much more hands-on. So that’s about actually getting the students to implement some elliptic curves from scratch, for example.
And how have you seen it in your time in academia, which has been, it’s now a longer time period. How have you seen computer science education changing? How do you think it might change further in the future, especially as we’re seeing AI be part of industry and probably the world as well?
Yeah, I mean, prior to AI explosion happening, actually, the rate of change is very slow in computer science teaching. Partly that might be Cambridge. Cambridge is over 800 years old. everyone thinks on longer timescales. People don’t tend to rush into the latest fad and instead try to focus on the fundamentals and the ideas that a lot of the fundamentals of computer science were developed in the 1930s already and are still true today. And lambda calculus and those types of things, for example. And so we have quite a bit of a focus on those sort of fundamentals rather than chasing the latest fashionable thing.
That said, AI has totally changed the way we can assess coursework, for example, because, of course, now we can try banning AI, but it’s impossible to actually enforce such a ban. And also it’s kind of counterproductive because we do want students to engage with new technologies and figure out how to use them productively for themselves. But we want to somehow do that in a way that supports their own learning and doesn’t undermine it. So how do we get the students to use AI in a responsible way, in a way that’s mature? And we can’t necessarily rely on the students being mature enough to know for themselves what is a helpful use of AI and what is a form of use of AI that undermines their own learning. Because some of them are quite mature and able to decide that for themselves. But many are not. And so we need to provide some guardrails for them.
And we do need to make sure that when we have assessed work, for example, it’s fair and it’s perceived as fair by the students. And if the students feel that some of their co-students are getting really good marks without doing any work, that undermines the trust in the entire system. And so we have to be very careful with how we approach this. And to be honest, we don’t really have good answers yet.
So we do now, for example, have a boot camp right at the start of the first year for the new students to expose them to basic software engineering skills, which is: - “This is version control.” - “This is unit testing.” - “This is generative AI.” And the sort of basics that really everyone should be familiar with. And then the hope is that they will use that throughout their degree in order to just improve the work that they do. But how exactly we handle things for assessment, for example, we’re still in the process of figuring out. So it sounds like the pace of change is going to be fast in the industry and also in academia. We’ll probably adopt it and we’ll see what comes after.
Yes, there’s a difference, though, which is in the desired outcome.
I think with industry, generally, the desired outcome is a working product, for example.
In academia, the actual artifacts that the students produce, like an essay that the students write, that’s not really the point.
“We don’t ask the students to write essays because we love reading their amazing essays.”
We ask them to write essays because we want them to go through a thought process which helps them learn something. And it’s that thought process and that learning which is really the desired outcome here.
And so that means that we do have to approach it a little differently because generally in industry, if you can use AI to get a job done faster and you get an equivalent result, do it.
“Because, yes, that is the desired outcome.”
Whereas in education, we do have to think about how we ensure that the learning outcomes and the thought processes are still preserved such that the students benefit intellectually.
It’s very relevant, especially Anthropic had a recent study where they looked at junior engineers. One group used AI, the other one did not. And they found, unsurprisingly, from what you also explained, that the group who used AI, they had little to no learning. Whereas the group that did not, they actually learned it.
Yes, I saw that study as well. I think the detailed methods of that study we might be able to quibble with a bit. But I think the general principle seems true that, yes, sometimes in order to learn something, you just have to struggle with it a bit. Not struggle too much. So if people are stuck on some technicality and they can use AI to get unblocked and then be able to focus really on the main learning outcome, then I think it’s good to use these types of tools. But if the point is to actually grapple with some difficult ideas and think them through in their own minds, then we need to still find ways to make sure the students are doing that.
You work both in industry and academia. What do you think industry could learn from academia and academia can learn from industry?
The two really could be closer together because often they regard each other with sort of disrespect, really. The industry people will say, ah, that’s theoretical, that’s academic. It’s got nothing to do with the real world and they’re really missing a trick there because actually there are a lot of interesting insights from research that are very relevant to the real world, but they’re not necessarily making their way across that chasm.
In the other direction, the academics will say, ah, this industry stuff, that’s just engineering. They’re not actually doing any interesting thinking. It’s just writing routine stuff. I think I see it as one of my goals to try and build better respect across both in both directions by bringing interesting insights from research into industrial practice, but also by informing our research by the problems that arise in real world. And so that way, like joining those two things up a bit better.
What are your current research topics that you’re working on, ones that you’re excited about?
I have two main areas I’m working on at the moment.
One is local first software. So that’s this idea that we want collaborative software like Google Docs, like Figma, et cetera, but in a way that gives better protection to users’ data. That’s less dependent on a single cloud provider who can lock you out of your files. And that’s therefore more resilient, gives users greater agency and greater autonomy over their own data. So that’s an area that I’ve been working on for the last 10 years or so through a mixture of open source work and algorithm development and formal verification and so on.
I’m now also trying to set up a brand new research area in a totally different topic, which is on using cryptography to prove things about the physical world. So I’m interested there in especially sustainability related things. So, for example, if you want to verify that the carbon emissions involved in manufacturing a particular product were X and you want to be sure that that number is correct, because maybe you want to include emissions as part of your purchasing decision and choose the product with the lower emissions. For that to be meaningful, then the emissions number has to be correct. And unfortunately, at the moment, the numbers are generally not correct because the incentives are to lie and cheat and to use creative accounting techniques all as a way of greenwashing, basically. Or a related thing is happening in the EU, for example, which is bringing in new regulations on preventing deforestation of tropical rainforests so that, for example, coffee, cocoa, palm oil, et cetera, imported into the EU. So the importer needs to prove exactly which plot of land it actually came from and then check against satellite imagery that that was not recently deforested.
And so I’ve been looking into using cryptography as a tool of proving things about the supply chains of these physical products, but without revealing commercially sensitive information.
For example, a company will not want to reveal who its suppliers were and which ingredient to its process it purchased from which supplier, for example, because that might reveal something about its secret recipe that it uses.
And so the hope here is that cryptography can allow us to prove that, for example, the accounting has been done correctly across supply chains, but without having to reveal publicly any of this sensitive data about suppliers or other customers.
What is your view from your vantage point on the impact that AI is having on academia, not just for students studying beyond that, and also industry, with your industry contacts?
“Yeah, I’m not that deeply into the AI things.”
I’m seeing it more through my collaborators who are making very good use of AI tools for software development, especially.
Actually, I personally write very little code these days, and so I haven’t had that much need or occasion to actually use AI agents myself personally.
When writing prose, working on the book, for example, I prefer to still do that the old-fashioned way of just writing every word by hand.
So I haven’t let AI anywhere near the text of the book, for example.
And I don’t know if that’s the right decision.
It’s not really a principled thing that I think it would be wrong to do so.
It’s more that, for myself, the process of writing is the way I figure things out.
And figuring things out is really my goal here.
So I’m trying to figure it out in my own head.
And for that, I just have to write it myself.
There doesn’t seem to be any way around it.
But using AI as a way of getting feedback on ideas or exploring whether an idea really holds up to scrutiny, that seems a very productive use of the technology.
And that applies for both industry and academia, I would say.
So as a closing, for a student or a young professional who is still studying and considering the route into either industry or academia, what have you seen?
Who thrives in one or the other?
Yeah, my feeling is they’re not really that mutually exclusive.
Or rather, some of the best PhD students I’ve worked with, for example, actually have a few years of industry experience.
So they might have done an undergraduate, maybe done a master’s, then spent a few years in industry developing, actual, doing real software engineering, learning about the real world.
And then maybe at some point got bored and thought, oh, actually, I want to work on maybe more idealistic things or have more freedom to choose their own research topics and then start getting interested in doing a PhD.
And that, I find, is quite a healthy route.
You do get people who go straight from their undergraduate degree and master’s into doing a PhD.
But sometimes those people can just lack a bit of the breadth of perspective.
And so I think having seen a bit of just real world engineering is actually really helpful for people, even if they then want to stay in research.
But in the opposite direction, I think it can work very well, too, because in research and academia, we just get to think things through a lot more carefully than people often do in industry.
Often people in industry have short-circuit reasoning.
Don’t quite reason something through from first principles, but I heard this from a conference talk.
I’m just going to go with that.
What academia can teach is this sort of nuanced and critical thinking to really reason through trade-offs, for example, and to really justify why something is true.
And so I think it’s really good, actually, if people can weave in and out of industry and academia a bit and not regard it as two totally mutually exclusive career paths, but actually have a bit of switching between the two.
Well, Martin, thank you very much.
I expected us to talk a lot more about your book, which we did, but I have a newfound curiosity and respect for all the important and interesting academic work that you and everyone else is doing.
So thank you so much for this.
Thank you for the great interview.
This was really interesting.
I hope you enjoyed this rare conversation with Martin Kleppmann.
I found it interesting to learn that the first edition of the book assumed that you have machines with local disks, but actually, today, this is not how most engineers build systems anymore.
Cloud-native primitives like S3 change how you build systems, and this is why this book just needed a refresh. I also appreciated Martin’s take on whether engineers still need to understand systems internals when they’re using managed services.
If you’re building business logic on top of these services, you probably don’t need to know every detail.
But it can become useful to be able to look deeper, especially when you need to debug your system.
By the end of our conversation, I gained a lot of appreciation for the academic research that Martin is doing.
A lot of these are hard engineering problems that few startups would take on.
It was nice to understand how academia is in a good position to do work that has a long-term focus.
Do check out the show notes below related to pragmatic engineering deep dives.
If you’ve enjoyed this podcast, please do subscribe to your favorite podcast platform and on YouTube.
A special thank you if you also leave a rating on the show.
“Thanks, and see you in the next one.”
2026-04-05 08:00:01
过去与未来一样崭新。我是许知远。欢迎收听历史学人播客。我们将探讨历史的偶然与必然,以及生活在历史中的个体的无数的可能性。
可能对黄陂南路或者新天地站不太陌生。出站走几分钟,大概就会看到一排石库门的建筑,上面挂着中共一大会址的牌子。每到节假日的时候,这里一般都会由人如织。熟悉中国历史的朋友,大概都会对这个地方不太陌生。
但是很少有人会想过一个问题:当年的中共为什么会在这个地方开会?这个地方到底是谁的呢?
要回答这样的一个问题,实际上就要涉及到在早期中共史,或者是在中共的创建史上,非常重要但在后来慢慢淡去的一个名字。他的名字就是李汉俊。李汉俊,湖北潜江人,早年东渡日本留学。他在1920年的时候与陈独秀、李达共同筹建中国共产党,但很早就退出。1927年,李汉俊在白色恐怖中牺牲,享年37岁。
围绕着这位青年俊秀和他的传奇人生,我们今天非常荣幸地邀请到中国社会科学院近代史研究所的副研究员、中共创建史研究中心特约研究员李丹阳老师来和我们聊一聊真实的李汉俊。
李老师除了研究者身份之外,还有一层身份,就是李汉俊的兄长李书成的长孙女。李老师,方便和大家打个招呼吗?
“我很高兴和大家谈谈李汉俊。”
各位听众好。我很高兴和大家谈谈李汉俊。
那方便和我们的听众分享一下您的家世渊源,还有您是怎么开始去研究李汉俊的吗?
我原来是在中国社会科学院近代史研究所研究近代中外关系的。我开始研究李汉俊有多种因素促成。1979年,沈雁冰在他发表的回忆录中以相当篇幅谈到李汉俊,这引起李汉俊家乡潜江的一位工人刘日明的注意,就写信给茅盾。茅盾与我的外公冯乃超很熟,知道他的夫人我的外婆李声韵。李声韵是李书城的长女,又是李汉俊的侄女。而茅盾先生的儿子韦韬恰恰与我父母在故乡就认识了。茅盾的儿子知道我,当时也想收集李汉俊的资料,所以把刘日明给茅盾的信转给了我。我们通信以后,刘日明一再催促我利用在北京和在研究单位的条件来研究李汉俊。我也觉得研究李汉俊是我作为学者和后代义不容辞的责任。
于是与丈夫刘建一开始利用业余时间收集李汉俊的资料,包括其著述译文、内外报刊和档案上的记载,还先后采访了大约80位认识或了解李汉俊的老人。40余年以来,我写了十多篇关于李汉俊的论文。我的博士论文《李汉俊与中国早期共产主义运动》。我参与编辑的李汉俊文集已经出版。随着史料的积累和研究的深入,李汉俊这个人物的历史面目趋近于清晰。我希望这次简要讲述能让大家初步了解一个真实的李汉俊。
您刚才也提到在工作的时候利用业余时间找了大量当事人,收集了大量口述材料。这些东西对于我们后面去研究中共创建史、了解那段历史其实特别重要。
说到李汉俊,很多人对他的认识基本上一开始就是在1920年代他和陈独秀他们开始创建中国共产党时的形象,但对他的早年经历比较陌生。您可不可以聊一聊早年的李汉俊,还有他的成长环境是怎么样的?
李汉俊之所以成为一个有反叛精神特质和特立独行人格的人,确实与他成长的环境、他的家庭、小时候受到的教育和影响及他少年特殊经历有关。他原来的名字叫李书思,是思想的”思”。汉俊实际上是他的号。1890年他生于湖北。父亲中年才中秀才,先后当门馆先生和小学教员,母亲操持家务兼种田。他引导学生关心社会、关注时局。受教于他的有加入兴中会参加庚子起义的傅慈祥烈士,有同盟会员牺牲于辛亥革命前夕的刘静庵烈士。李汉俊和李书城兄弟从小随父读书、随母干活。
在近代湖北开办新式学堂之先,清末张之洞任湖广总督期间大力兴办新式学堂,大量派遣学生出洋留学。1902年,当李书城被派赴日本留学,李汉俊到武昌上了高等小学堂。1903年初,他哥哥李书城回国,给李汉俊带来了新鲜的思想。李书城在日本留学期间曾见过孙中山,一起开过会,接受了民族民主革命思想。他与黄兴是同学,一起去日本留学。
李书城归国后参加了以兴中会会员吴禄贞为首的湖北革命知识分子在武昌花园山建立的秘密机关。他们议定了革命方法和途径:先在湖北知识界宣传反清革命思想,再介绍一些有志青年加入新军,然后让他们在军中秘密建立革命组织,进而由新军发动武装起义推翻清朝统治。李书城在这个机关中负责秘密联络军队,他曾经把父亲的学生刘静庵带到武昌从军。哥哥李书城的革命思想和行动给李汉俊以很大的影响。
刚才听您聊的,我感觉包括李汉俊在内,还有毛泽东,很多早期的共产党员都有一段民族民主革命的经历或记忆。有的人像毛泽东可能亲自参与了,有的人像李汉俊是因为家庭环境和武汉当时的革命氛围的影响。在早期中共党员的履历中,留日经历也是一个特别重要的履历,像李达也是,李汉俊也是。您能不能聊一聊李汉俊是怎么去日本留学的?
谈到李汉俊年纪小就去日本,还要提到他的哥哥。李书城回国前写了一篇文章,鼓励湖北学子跳出故闭的小圈子,留学外洋去见识浩瀚世界。回国后,他介绍的外面的世界和思想潮流使李汉俊不再安心于在学堂读书。1904年,李书城准备再赴日本学习军事,李汉俊非要跟哥哥一起去。吴禄贞听说后主动承担了他的旅费和学费。年仅14岁的李汉俊得以跟随李书城到日本留学。
他一去日本时就在革命派的核心圈子里。资助他的人中有吴禄贞。哥哥去日本肩负学习军事、以后推翻满清这样的使命,而且是冒用别人的名字去的。李汉俊到日本的第二年在他哥哥的一个朋友家见到了孙中山。此时同盟会刚成立,李书城已经以李唐的名字入盟。当时一次聚餐,孙中山说他自己是孙权,说刘成禺是刘汉,然后说李书城叫李唐。后来我外公真的以李唐的名字填写的同盟会入会名。那回到李汉俊,当时他更多是在读书、在学校里。
他见到孙中山后,孙中山看到那么小年纪就想往革命,就夸他:”好小孩,有志气,中国有希望了。”以后李汉俊上高等学校时到东京来,经常住到黄兴的家里。李书城与黄兴关系很好。在这些革命党人的启迪下,李汉俊接受了民族民主革命的思想。1912年春天在南京加入同盟会。但从现有资料看,他在留日的十余年里并未参加同盟会的革命活动,看来他比较专心向学。
那时李汉俊在东京的学习情况如何?
在中共创立者中,很多人有留学经历,但唯独李汉俊留学时间最长、在日本的学历最为完备。1904年5月,他先在为中日留学生开设的预备学堂经纬学堂学了7个月,还没读完补习课程就进入日本著名的教会学校晓星中学–是法国天主教传教士在日本办的学校,就连日本少年都很难考进去。学校课程很多,不少课本是法文,用法语授课,几乎全是日本学生,对清国学生严重歧视,但李汉俊脱颖而出。三年级时获得全班第二等优等奖,并以优异成绩毕业。
那时日本中学通常只有约4%的考生能考上高等学校,而他直接考上了作为大学预科的高等学校。1910年从晓星中学毕业后,他没有接着上高等学校,而是回国,可能是没有钱了。后来经历了辛亥革命,民国成立后他随哥哥到了南京。在吴禄贞的追悼会上,他和他哥哥参加了,黄兴等人也参加了。大约1912年秋他取得了民国政府的公费留学名额才又到日本继续上学,这次他上的名古屋的日本第八高等学校(即今日的名古屋大学)。在该校作为大学预科分科时,李汉俊选的是工学科,他当时想以后回国建设祖国。
他学了三年,不仅打下了坚实的功课基础,还学了一些自然科学和社会科学方面的课程,比如:
还掌握了德语等外语工具。我有他历年的成绩单,每年成绩都是名列前茅,以优良成绩毕业,取得了东京帝国大学入学资格。东京帝国大学是日本乃至全亚洲最好的大学。他在东京大学读的是土木工学科,课业特别繁重,每年要学十到十二门课程,学生淘汰率很高。我查到与他同入学的47名土木科学生里,到毕业只剩35人。除了他以外其他学生都是日本人,而他经过刻苦学习成功获得了工学士学位。
他后面回国后转向社会科学研究,一方面因为他早就成为民主革命阵营的一员,另一方面与他在日本接受社会主义思潮和马克思主义有关。李汉俊说他自己大约在1916到1917年在大学期间接触马克思学说。有人说他信仰马克思主义是受到师友关系的影响,但这种传言没有根据。
李汉俊是1918年7月大学毕业,年底才回国。这段时间他在日本的经历值得探讨。1918年8月,日本发生席卷全国的米骚动和罢工浪潮,大批工会和左翼组织兴起。对日本社会运动一贯关注的李汉俊阅读了一些新出版的进步刊物,结识了在日本发起解放运动的进步社团的一些成员,比如:
这是他自己文章里写到的。其中有一位是新人会的发起人宫崎龙介,是宫崎滔天的儿子,是他的老朋友,二人在高中时期就认识。李汉俊还与后来发起日本共产党的堺利彦、高畠素之等人有联系。他回国后翻译过山川均、堺利彦、福田德三、佐野学等日本马克思主义者的著作,也可能在日本就读过这些人的书。总之在日本,李汉俊经历了新思潮的洗礼后回到祖国。
因此,李汉俊一方面因家庭的革命环境而成长为革命者,另一方面因留学时期遇到日本社会主义运动的影响,成为一个在1918年前后受日本社会主义运动影响成长起来的青年。
我们也讲到他在1918年底回到中国。那时中国的现状和环境是什么样?他在1919年底在给董必武等人的信中说自己”处在惊天裂地之间,满目伤心之中”。当时中国军阀混战不已,有的地方军阀提前征收税收十几年,兵匪动不动就抢老百姓。李书城曾写当时的民国是”群雄扰攘,国困民贫”。 北洋军阀把持的中央政府与列强签订了一系列丧权辱国的条约。总之人民无法照着生活下去。
当时李汉俊内心真实的想法是什么样子的?他有什么想要改变的办法吗?他曾经说过当时的中国是一个死牢。其实像他类似看法的,比方说李大钊说中国当时的社会是死社会,鲁迅形容为一个铁屋子。
当时一些在华的外国人也有这个深刻的观察和评论。比方英国驻华领事叫Hewlett说:
中国处于最黑暗的混乱时刻。
波兰裔的美国人Sokorsky写道:中国国内要变革不可避免的要采取革命手段,也将与外部发生战争,这会使中国成为亚洲的打火侠,叫Tinderbox。一位法国传教士叫Bornat,他说被民族灾难激怒的学生喊出中国正在被处死。士兵们感到十分不满,很容易被卷入任何革命运动;而农民变得非常绝望,准备追随任何承诺给他们更好命运的政党。
这些中外人士观察到的中国情况,并不像现在有人说的那样民国岁月静好。本来李汉俊回国是要建设的,学土木工程的,可当时的中国根本没有给他应用和发挥他的专业的环境和条件。
那那个时候,就是李汉俊回国之后,他去哪了呢?他1918年末回国后,主要是住在哥哥李书城在上海的家。他居住和活动的主要范围就在现在这个黄浦区。他在这个中国最大的工商业中心和中外资本家的乐园,看到了地狱般的情景。
这是他自己写的:他工人两班倒,每班12个小时。如果没夜班,那工时可达18个小时。辛苦一天的工资甚至不够买一根冰棍;衣不能暖,居不能避风雨。一旦失去劳动机会,就会饿死。而资本家因工人的劳动,得以住豪宅、穿利服、吃山珍海味。对这种社会的不公,他感到愤慨。
作为一位有良知和强烈社会责任感的人,一贯认为知识分子不应当只图一己的安逸舒适,而无视人民的痛苦。他这个想法跟当时的很多的新青年其实都蛮像的。对,所以这样他们才又聚集在一起。
我记得李汉俊回国之后,还在留学生的《救国日报》上发过一些文章。那您可不可以跟我们聊一聊他回国之后的一些具体的活动,就是他在上海那段时期的事情?
他20年初的时候,在留学生创办的《救国日报》上发表一篇文章说:到国外留过学、深见世界情境的留学生,应当肩负及指导普通大众改造中国,使之适应世界潮流的责任。他对改造中国有一些想法,他认为挽救中国与危亡要使人民幸福,局部的改良没有用,必须进行全部改造的社会革命。而且他认为解放和改造要从努力和奋斗中去求,拿出创造的精神来。就是说大破坏与大建设的功夫,这个先破坏再建设,孙中山也说过这个。
他说留学生要指导大众适应世界潮流。当时的世界潮流是什么?他那个时期就正好是第一次世界大战结束。那时让人看到了资本主义的无序发展和恶性竞争,带来资本主义国家贫富悬殊的社会问题,导致了人类大规模屠杀的战争。然后帝国主义的侵略和掠夺,又使殖民地、半殖民地国家的人民遭受苦难。俄国十月革命以后,世界社会主义运动达到高潮。
李汉俊参与翻译的一篇日本社会主义者山川菊荣的文章《世界思潮之方向》里面写到:俄国革命发生以来,世界实在向无产阶级的解放一方面正在突飞猛进,已经成了大事。李汉俊对国民党(当时也称一度改为中华革命党)领导的旧式革命很不满。他去见过孙中山几次。那个时候是在上海的孙中山。他见过几次,不光是跟宫崎龙介见过。他自己还见过。
英国的档案里头写到了,他曾经对孙中山说过,国民党不应当只运动军队和土匪,应当注意主义的宣传。1919年春夏之交,他在达费路附近与董必武、张国恩等几个湖北国民党人一起聚谈。他们都觉得孙中山依靠军阀搞革命的路子不对,都认识到要学习马克思路线的理论和俄国革命的方法,而革命之成功必有待于新兴势力之参与。但那个时候的他所谓的新兴势力,实际上是指的是俄国的这个布尔什维克。
1920年9月发表了一篇文章,实际上是山川菊荣那篇文章的附记等于是他的提出来,不能依靠已有政党,希望平民无产阶级靠自身结合力组织起来,从事社会主义革命。他这个观点挺像是毛泽东那个平民的大联合。田子渝教授就说,这个时候李汉俊可能已经有建立无产阶级政党的打算了。我认为他至少已经有依靠劳动者另起炉灶想法。实际上是在旧民主革命向新民主革命过渡的那个时期,是一位先驱性的特殊人物。
他原来是国民党员,后来又主张搞一个新的无产阶级平民的政党。在国民党里面他其实也算老资格了。他实际上后来到孙中山成立中华革命党的时候,他没参加,他的哥哥没参加,因为不喜欢孙中山要大家打手印宣誓效忠。他个人和黄兴在欧洲美国转一圈,就是考察。
李汉俊是不是有组建政党的那个意识,这个不是很清楚。至少他认为旧的政党不行了,国民党不行了。他说没有新的思想,又没有新的力量,国民党就是那些武人官僚军阀被这些人裹挟了。他说我们自己就是平民,就是无产者,就是什么,他说过这个话。但李汉俊那个时候的主要的活动,还是在于这个理论的研究和传播这一块。
您能跟我们稍微聊一聊当时他是怎么去做这种所谓的主义的传播的吗?有人就是说他是一个马克思主义的传播者。实际上他也真的有那个意识,传播马克思主义思想的种子。1921年他对来访的日本作家芥川龙之介就说过,他要搞社会革命便不得不依靠宣传鼓动,当务之急乃是表示要不避劳苦,倾全力把手里的种子撒向中国万里荒芜的大地。他这个撒的种子实际上就是马克思主义。
刚回国不久就为上海的《星期评论》、《觉悟》、《建设》(主要是国民党系的报刊)写了多篇介绍马克思主义的文章。1919年8月,他写的《怎么样进化》就运用马克思主义观点来解释历史变化。他特别指出,在近代由于资本家垄断了生产机关和交易市场,使工人变成同机器一样的器具,并使弱小国家人民陷于贫困,更造成经济危机和世界大战。人类要改变这种薄弱社会朝幸福安定的方向发展,就要把机器的所有权普及于一般运用机器的人。
他这个说法实际上就是现在所说的以人为本,关心劳动者的解放。他是与马克思的出发点是一致的。马克思的早期文章实际上就是反异化。关于异化的一些讨论和批判,就人不能变成器具,而且是为了人类的幸福,他一开始就有这样的想法。他接受的可以说是比较原始的马克思主义。他这个理论深度感觉跟当时的李大钊有点像,因为李大钊也是在日本留过学的,他是有点像。
有一个学者在哲学研究上有一篇文章,说是价值理性还是工具理性,就认为李大钊是价值理性,说陈独秀是工具理性。我就看过这么一篇文章。其实李汉俊就有好多想法是跟李大钊类似的。
当时李汉俊他在上海。我们知道上海是一个国际性的大都市,是五方杂陈之地。然后李汉俊他又是留日学生,有这个非常复杂的社会关系。那个时候他在上海有没有跟其他的这些各种国际人有过这种交流或者是这种活动?
其实早在1919年10月份,英国情报机关通过侦查就认为李汉俊是中国的布尔什维克,就这样写的。1920年2月在上海,他又有一个情报侦查到李汉俊与一些对先进的社会主义思想有所了解的中国人,还有朝鲜人李光洙(李光洙也是一个朝鲜的小说作家),还有那个俄国人李泽洛维奇,他们一起开会商讨组成一个革命团体,筹备出版《劳动者月刊》。就这个事呢,日本的情报也记载了,说李汉俊(那时候说他是李人杰)与俄国人阿格列耶夫,还有朝鲜人吕运亨筹办《劳动》杂志。
1920年3月1日,朝鲜人在上海举办纪念三一起义周年的纪念会,李汉俊是唯一一个代表中国人致辞。朝鲜人致辞中有当时的韩人社会党的委员长李东辉。韩人社会党实际上是在哈尔滨成立的,后来到共产国际注册的一个社会主义政党。1920年5月份他又变成了高丽共产党。这个李东辉是负责人,还有那个跟他一块筹备《劳动者月刊》的那个吕运亨也是独立运动人士,后来也加入这个高丽共产党,成为党中央的翻译部负责人。他是首位把共产党理念带入朝鲜的人。上面还提到了李哲瑞,就是他们一起开会讨论的。他是来自英国的俄国人,他呢与英美社会党后来都组成共产党了,有联系。
这阿格列耶夫呢是来自海参崴(Vladivostok),这两个俄国人当时都在上海,为苏俄,后来又为共产国际工作过。杨之华就回忆曾经谈到李汉俊早年与朝、日、俄的朋友,甚至与那些地方的共产党有联系。这样他还是有点根据。一位韩国的学者的论文里认为在后来成为中共领导的人物中,1920年春以前只有李汉俊与朝、日、俄社会主义者有密切联系。
我们知道中国的共产主义运动是世界共产运动的一部分。信仰马克思主义,了解世界大事,又掌握多国语言的李汉俊是在中国较早参与国际运动的人,在早期的东亚共产主义运动中有着重要的地位。这是当时李汉俊和国际共产主义运动就有交集的那一面。
他不光是跟苏俄,他跟英美的社会主义者、共产主义也有关系,还有东亚的像韩国高丽。实际上日本的共产党和韩国共产党成立都跟苏俄有关系,但李汉俊大概是比较特殊,就是在上海就与英美的社会主义者有间接的联系。就我说的那个李哲瑞,他曾经接受过英国后来共产党的负责人Sylvia Pankhurst的信。李哲瑞从英美接受过一些像社会党的刊物,后来又是共产党的刊物,就是New York Call那些。李哲瑞和李汉俊的关系大概比较密切,因为他们都懂英语。
后来《新青年》上的好多翻译的文章,原来是美国社会党刊物刊登的一些文章,李汉俊他间接的就是与这些国际共产主义运动有关系。咱刚才聊的是国际线,接下来咱聊一聊国内线,就是在1920年到1921年这期间内,其实全国各地主要是省会城市出现了各种各样的共产主义小组。
那么当时上海的这个早期党组织,它里面有很多的成员实际上是来自于当时的杭州浙一师,这些人其实是跟一个杂志有特别大的关系,就是这个《浙江新潮》。后面还有一个很重要的杂志是那个《星期评论》。那李汉俊跟星期评论这一拨人有什么样的联系呢?
谈到中国共产党运动和组织的起源,不可不提到上海的星期评论社。《星期评论》是国民党系的刊物。李汉俊加入过同盟会,所以他回国后不久便为这个刊物撰稿,后来又成为编辑了。这个刊物刊载了不少介绍马克思主义、社会主义、提倡劳工运动的文章。与北京的《每周评论》被誉为舆论界中最亮的两颗星。
20年初,星期评论社迁到李书城、李汉俊的家,就上海法租界白尔路三益里17号一栋三楼三底的房子,比较大。到春天,俞秀松、施存统他们两个原来是浙江的浙一师,后来又到北京参加那个工读互助团,然后他们到了上海住在李汉俊家。陈望道也在这儿待过,然后他翻译《共产党宣言》,然后还有丁宝林,很多人就到星期评论社这边过来。这些人很多人就住在他们家。这样子后期的星期评论社成为南方有先进思想的人士聚集的重要中心,我觉得都值得研究。
俞秀松、施存统从北京专门跑过来,后来陈独秀也跑过来。1920年4月的时候,俞秀松在一封信里说,他那个信件还是写的星期评论社,他就说这里的同志男女大小14人主张都激进。正好英国的6月份的一份情报也写着:布尔什维克代理人在上海的活动集中于星期评论社。据说该报社聚集着14个男人和两个女人,确信他们都在为事业而工作。而这一星期评论社的思想领导中心据杨之华说是李汉俊。
20年春天起,星期评论社就是开始接受了一些来自英美社会主义、共产主义政党的刊物,李汉俊有的把他们翻译成中文了。在共产国际二大(就是7月份召开的)中国的代表刘绍周在发言中甚至称《星期评论》为马克思主义政党的周刊。那这个评价还是蛮高的。
其实我觉得可能当时就有一个计划。1926年的俄国的一个顾问卡拉乔夫在中共简史里头写,陈独秀20年去上海是因那里有星期评论社。就美国学者德里克他写中共起源,据他的研究,他说围绕着陈独秀和星期评论社的一小群人是形成中国共产党的重心,其中只有陈独秀是newcomer,新来的人。所以他指出如果上海有什么中心的话那就是星期评论社。这个后来瞿秋白、李立三在党史报告里也写到说星期评论社是形成共产党的一个细胞,的确就是参与。 筹建中共的大部分人就来自星期评论社中,有激情、有理想的群体,而其核心人物就是李汉俊,还有像李达、陈独秀。
按照石川祯浩老师的说法,大概是从1920年的4月份俄国的维经斯基来华以后,这个时候的上海的党组织可以叫发起组。4月份应该还没有发起组,是说他开始有点筹备,就开始进入一个筹备阶段了。那么从1920年的4月一直到1921年的7月份,整个过程当中都可以说是一个筹备、创建的这样的一个阶段。对,确有这么个形成过程,当然是从1920年春开始酝酿。
俞秀松在苏联写的自传里头说,”20年春我们曾想成立共产党,在第一次会议上我们之间未达成一致意见。” 在那个党的酝酿时期,实际上当时的参与者信仰什么的都有:共产主义、民主社会主义、基尔特社会主义、无政府主义都有。那时候其实有两种思路:维京司机觉得多多益善,因为你中国信仰共产主义的人就少,因此他们在酝酿讨论建党的时候就有分歧。
5月底,李汉俊在批判张东荪一篇文章中说,起了争执,是不是主义前途的障碍呢?与其由混杂分子组成一个庞大不纯的团体,不若由纯粹分子组成一个随小而纯的团体。这段话透露出在早期讨论中,李汉俊主张应该由纯粹的马克思主义信仰者组成政党,成员宁缺勿滥。他这个思路跟陈独秀的这个思路很相近。其实陈独秀自己那个时候,马克思主义不是特别的,还在学习摸索阶段。
请问一下李老师,就是在中共发起的过程当中,李汉俊他到底起了一个什么样的作用呢?首先他是一位主要的发起人;其次,又是早期党组织的负责人。所以李达他回忆他自己20年9月到上海,就听说陈独秀和李汉俊正在准备发起组织中共。李达其实是9月份回来的,他不是最早发起的。
包惠僧就说,中共成立之初,李汉俊在党内地位仅次于陈独秀。而日本的一个档案写明说李汉俊是上海共产党的副首领。所以20年底,陈独秀到广东前是让李汉俊来代理党的书记。最近在俄国档案中发现了1921年春,有书记李汉俊以上海共产党革命局书记身份为外国语学校的学员开具的赴苏学习的介绍信,盖着图章,那个图章写的就是人杰两字。
为筹备一大,李汉俊呢直接与陈独秀、李大钊通信。21年6月,共产国际的代表马林到上海,向李汉俊要工作报告、工作计划和预算。这都说明李汉俊在一大召开前不久仍然是中共临时中央的负责人,而且实际上李汉俊在中共刚刚发起的时候,他还为党写了一个等于是党纲的草案。
我们知道,中国共产党的第一次代表大会是在1921年的7月底召开的。这个会议上其实并不是说大家所有的事情都一致举手表决通过的,而是有很多的讨论,也有很多的不同的意见在互相的交流。那么在当时一大召开的过程当中,李汉俊对于当时中国共产党建党他有什么样的看法或者意见呢?他是少数发表了一些不同意见的人。
我梳理了一下,他的主要意见就是针对党纲和工作计划中的某些条款。党纲中有一条是革命军队必须与无产阶级一起推翻资本家阶级的政权。那鉴于中国当时并非资产阶级掌权,无产阶级还比较幼稚,李汉俊就主张党的当前任务不是领导无产阶级夺取资产阶级政权,而应当先支持孙中山领导的革命运动,以实现民主政治。他不赞同刘仁静说的以无产阶级专政为斗争的直接目标,和张国焘讲的”不管各国情况怎样是要无产阶级专政”的说法,认为中国国情特殊,以后是否适用于无产阶级专政还应当研究。
其次,党纲中有中共要彻底断绝同黄色知识分子阶层及其他类似党派之一切联系的条款。讨论中还有人讲知识分子都是资产阶级思想的代表者,一般应拒绝其入党;还有人说知识分子动摇不可靠,在吸收他们入党时应该特别慎重,一般不容许他们入党。李汉俊的主张是对知识分子要放宽些,只要他信仰了解和宣传马克思主义即可入党。他主张应该重视对青年学生的教育,要以掌握了马克思主义的知识分子做骨干去组织和教育工人。
还有,对于党员不得担任政府官员或国会议员的条款,和有的代表发言中说的中共目前不应参加实际政治活动的主张,李汉俊认为必须把公开的和秘密的工作结合起来,因为公开宣传我们的理论是取得成就的绝对必要条件。他建议可以挑选党员做国会议员,以利用同其他被压迫党派在国会中的联合行动部分取得成就,比如改善工人状况。同时他又指出不应该对议会斗争抱有过高幻想。他提出的那个修正案是共产党员不得做政府的政务官(即事务官)。
在讨论劳动运动方案时,张国焘和刘仁静说要尽先把产业工人组织起来,职业工人无关重要。李汉俊的意见是容许职业工会,这与毛泽东等做实际工作的代表意见是一致的。但是最后的决议为本党的基本任务是成立产业工会,没有提职业工会。
还有关于与其他政党的关系,张国焘等说不要与任何政党联合,甚至有人认为南方政府与北洋政府是一丘之貉。李汉俊则提出在目前斗争中应当支持孙中山先生的革命运动,援助国民党。最后的决议为对现有其他政党应采取独立攻击排他的态度,不同其他的党派建立任何关系。
对一些代表他认为可能不懂策略吧,李汉俊感到很遗憾,但在他自己的意见和提案遭到否决的时候,坦率地表示服从多数的决定。在一大选举中他没有被选入中央领导机构,却被委任与董必武起草给共产国际的报告。这个报告反映了李汉俊的一些观点。
其实从您刚才的讨论,我们可以看到在当时早期的这些中共一大代表里面,李汉俊按左右划分其实他是有点偏右的,所以也有人就说他说是有改良主义吗?还说他右倾机会主义者,还有合法马克思主义者。但实际上过了一年以后,随着中共二大的召开,整个的路线其实也是走向了一个很务实的角度,做了一个修正。
您刚才还聊到一个问题,我觉得特别有意思,就是毛泽东因为这种学术方面的储备是远远不如李汉俊的,但是李汉俊和毛泽东他们在一些涉及到工人运动、涉及到政党合作的方面却有着非常高度相近的看法。那么这个跟李汉俊他的工人运动观还有他的实际的革命运动有什么样的关系呢?
我先说一下毛泽东主席,虽然你说他当时可能学历各方面可能不如李汉俊,但是他比较实事求是,他始终没有对李汉俊有恶评,几次都是说李汉俊是牺牲了的。然后呢,他在七大上他说一大代表当时对马克思主义了解有多少、世界上的事如何办也不甚了了。解放以后,他是签署了给李汉俊的烈士证。我听那承武将军说在延安的时候,董老还有林伯渠,他们就谈论过,当时就认为李汉俊应该算是烈士,就是没有像张国焘他们那样给他扣帽子。董必武后来也觉得当时一些决议是关门主义的政策,是二大的时候做了适合国情的一些调整,对党的任务和策略。
然后很有意思,在三大,李汉俊又未被选为中共中央的候补委员后,马林托李大钊带了一封信给李汉俊,他说在第一次会议上小组在上海对你的态度是很错误的,现在我们的同志都同意这种意见。这就是说明李汉俊当时的主张其实是后来获得了大家还有包括共产国际的一定的认可。
对,我还是想回到刚才的那个问题。我们知道共产党他的一个很重要的活动就是从事工人运动,那李汉俊对于工人运动,包括对于当时的工人他还是怎么看的呢?
李汉俊很早他回国不久,他就很重视注意调查工人的情况,十分看重工人自发的罢工,后来又积极参与对工人运动的指导。有人甚至说他是中国工人运动的先驱。他19年就认为知识分子应该与工人结合,脑力劳动者应该从精神上打破知识阶级的牢狱,谋脑力劳动者与体力劳动者的一致团结。后来又号召知识分子要以同情互助和牺牲的精神尽力贡献自己的能力于社会改造事业,这是他的一个始终不变的初心。
19年就对上海那些罢工的现象问题做了总结。当时好多人就反对那个工人罢工,然后他就充分肯定工人罢工的合理性和正当性,就认为过着非人生活的工人怎能不进行抗争呢?他为了开阔工人的眼界,还写了不少介绍当时欧美、日、俄等国的劳工组织和运动的文章,也介绍了从第一国际到第三国际的世界劳工运动史。
他为了具体的指导一些工运,在《劳动界》他是主编,先后写了《工人如何对付米贵》、《汉口人力车夫罢工的教训》等等文章,启发指导工人提高阶级觉悟,让他们团结起来争取自己的权益,然后最后引导工人就在生产关系和政治上夺取支配权。
他是身体力行地参加了20年4月份上海船务栈房工界联合会和上海机械工会的成立会。党刚成立不久,实际上他是主持这个工运工作的,曾经派李中组织机器工会,派李启汉组织纺织工会。他代理党的那个书记,以后又成立了职工运动委员会。21年春天,他又亲自指导了上海法租界电车工人的罢工。
所以日本的21年的那个情报就是说李汉俊成为上海各种工人运动的煽动者,在蓬勃发展的工人运动中被视为中心核心人物。他虽然没有像那个报告说的是他被选为纪念五一劳动节筹备会的会长,但实际上李汉俊也参加了李启汉出面办的那个会,而且也出了主意。这个筹备会后来租界的人就把这个地方抄了。实际上在建党之前,他一直实际上在负责上海的工运,非常厉害的一个人。
我们知道中共二大以后,中国的工人运动进入的一个所谓的第一个高潮。那个时期的李汉俊他在做一些什么?21年底他离开上海,他后来写的就是说自己决心卸脱一切在上海的党的责任地位,专心教授及劳动运动。21年底到武汉之前,曾经到北京与李大钊和邓中夏等商讨过工运工作。到武汉以后,他就又跟包惠僧他们联系上了京汉铁路工人,后来又到粤汉铁路、汉阳铁厂、汉口英美烟厂等处到那里去负责指导工运,还有工人俱乐部的成立,后来又是工会的组织,他都参与了。他跟林祥谦、向警予、杨德甫等工运领袖都成了朋友。
所以日本档案甚至说他是陈独秀派遣的,在武昌城内设立支部,让包惠僧接管事务性工作开展活动。22年就成立了湖北全省工团联合会,李汉俊任职委员,还有兼教育主任委员。23年京汉铁路总工会的成立大会,他又带着几个学生到郑州参加成立大会。在总工会成立遭到阻挠的时候,当晚工会党团召开紧急会议,然后李汉俊也参加了。他赞同总罢工,但认为张国焘提的条件过多,不仅难以实现,也树敌过多。他的意见没被接受,但仍然积极参与指导罢工的准备工作,动员学界声援。有人后来认为他是二七惨案的幕后指挥者。二七惨案后,他就被湖北军阀通缉,逃到上海去了。
他在北京为二七受难者的家属捐款,积极联络湖北的国会议员胡鄂公等人在国会提出弹劾吴佩孚镇压京汉铁路工人、解散京汉铁路总工会的提案,要求政府制定保护工人权益和工会的法律。23年的4月,内阁向国会提交了工人协会法草案,李汉俊马上就写了文章,对这个工人协会法提出批评。第一次工运的高潮,它的最直接体现就是京汉铁路大罢工和香港的海员大罢工,李汉俊在当时的京汉路上他发挥的作用可以说是非常至关重要的。
工运进入第一次高潮,党内有一些失败情绪。当时总书记陈独秀就认为中国工人落后、幼稚、缺乏觉悟,不能成为独立的革命势力;资产阶级力量比农民集中比工人雄厚,应当让国民党走革命中间道路。而李汉俊在二七惨案的一周年就是24年写了《纪念二七的意义》,他仍然肯定工人是革命的中坚,直到二七年他还宣称农工是世界解放的钥匙,这是他一贯的看法。
在京汉铁路事件之后不久,在中共四大召开前,李汉俊其实就脱党了。真实原因是什么?他为什么会脱党?有对张国焘、陈独秀有不满,李汉俊认为他们有的事做得不对,尤其张国焘特别排挤他。当时矛盾就说他脱党是因为他高傲气质和坚持个人的独立见解。的确李汉俊就是有什么就说出什么来了,还有就是他也不愿意放弃共产国际籍和屈从某些党的领袖的错误领导。
21年马林刚到上海的时候,李汉俊就表示中国共产主义运动应当由中共自己负责,共产国际只能在协助地位。我们可以接受其理论指导并采取一致行动,在经费方面只能在我们感到不足的时候才接受补助,不期望靠共产国际的津贴来发展工作。
在一大,他更是发表了一些与众不同的意见。刚才说了有一个苏联顾问认为一大因为李汉俊的反对才没有通过加入共产国际的决议。二大召开前后,他又给党中央写信提出一些意见和建议,其中一条是反对领薪水,主张党员不能只靠吃革命饭,而应当有自己的职业和收入。他这个建议实际上主要是不希望党完全依赖和受制于苏联共产国际。
二三年的时候,马林以共产国际代表身份指令中共党员以个人身份加入国民党,采取党内合作的形式。 李汉俊在参加 北京党组织的讨论时,他表示国民党是代表资产阶级的政党,而共产党是代表无产阶级的。根据马克思主义原则,共产党员不应该加入国民党。他预言这样的党内合作会把中共搞垮的。这是他脱离党的一个重要原因,就是政治观点不大一样。还有一个原因就是1923年他到北京以后,在外交部、教育部任职,他的薪水除了维持家用,还用来资助:
这些湖北的女共产党人还为抚恤二七罢工的死难烈士家属捐款。他不接受北京那个党组织要他辞去政府职务,所以免于被开除。23年5月就写信声明退党。退党以后呢,没有马上被开除。一年后24年,大概在四大前被除名。
那李汉俊脱党以后呢,他在北京或者说在其他地方,他具体的生活是什么样子呢?他还是主要是教书,在湖北的武昌高等师范学校,后来又叫大学教书。他离开了党没有放弃信仰,还在那个大学里教授马克思主义,仍然也听从党安排做这些事。陈独秀给他写了一封信,让他到上海大学授课,他就去了,还曾接受李大钊的安排,去冯玉祥的部队里讲课。他跟李大钊关系一直比较好,李大钊对一些党员说要对李汉俊表示温暖。他虽然反对共产党员参加国民党的党内合作形式,但他在一大就提出过要援助国民党,所以他并不反对国共合作。
二六年春,他在怀念孙中山的文章里说:
共产党没有加入以前 国民党是一个没有气的皮球 没有煤炭的车头 共产党加入后 才成为一个有气的皮球 有煤炭的车头
很肯定共产党在国共合作中的重要作用。二六年下,他由董必武和张国恩介绍加入国民党,但是在同年秋,他又提出了恢复中共党籍的申请。湖北区委经过讨论,一致同意他的申请,但是最终被陈独秀否决了。他虽然没能如愿重回党内,但他常对人说:
“我不能做一个共产党人 做一个共产主义者 亦属心安理得”
大革命期间,他与共产党人携手合作,作为湖北省教育厅长,常与中共湖北省党委宣传部长交换意见。七一五以后,武汉方面分共清党,李汉俊有人说国民党这样清党,把一点革命力量都清去了,国民党也就要完蛋了,革命的希望还是共产党。可见他是一直心向共产党的,也以国民党的身份为共产党做了不少事。从这里可以看出来,其实李汉俊他从一开始他的建党思路都是保持党的独立性。他对这个问题他很看重。
另外就是说他的性格跟后来的李达、施存统他们比较接近,就是有点那种知识分子的性格。陈望道他们其实他们是这样的一批人。我们一说到这样的一些人,或者我们说到这个知识分子,我们经常会想到这些人其实是穿着这个西装革履的。那其实真实的李汉俊他的这个形象是什么样子?有的人大概觉得李汉俊是留日归国的应当是西服革履,其实是想当然。李汉俊这人十分朴素的,他曾经对家里人说穿着简朴一些方便与工人联系。
21年,芥川龙之介见到的李汉俊他描述是穿的是灰色大褂和中国布鞋。他的那个学生回忆老师说他衣着极为朴素,为中式蓝布打长衫。沈雁冰(茅盾)也说他是衣服朴素如乡下老。我的那个老外婆曾经告诉我一件事:有一次李汉俊和一位外国人在上海进一家饭店,门卫见李汉俊穿得太土不让他进门,还是那个外国人说了他是我的朋友才让李汉俊进去的。实际上现存的李汉俊穿西装照是他结婚的时候拍摄的,那个西装还是借他的一个兄长李书城,就是随着黄兴到美国流亡时穿过的旧的燕尾服。李汉俊也不讲究吃穿。
他嫂子回忆有一次米饭夹生,别人都没动筷子,他却匆匆吃下就没觉察出来。他写文章的收入常用来资助党的活动,如果不够甚至当掉亡妻的首饰。有人见他在上海任党组织书记时候就生活很苦。在武汉的时候,他每月把当教授的收入拿出一部分交给党组织,这是夏之栩告诉我的。夏之栩在那给他当等于是秘书跑东跑西,他就把每月给她钱然后拿到她母亲家,她母亲家是党的一个活动地点。他还经常资助一些青年党员,自己生活十分简朴却对党很慷慨。
李汉俊是在四大之前就是脱党,虽然后面还是和党组织有着密切的联系,但是在形式上其实已经脱离了党组织。既然这个样子的话,为什么在1927年的时候李汉俊会被蒋介石杀害呢?其实像蒋介石他们还有湖北的一些国民党的反动派挺恨李汉俊的,因为他虽然加入了国民党,又在改组清党以后他又留下来,但是他做的很多事情就比较为共产党做的。当时七一五以后,董必武、恽代英等人就劝他们留下来做点事,所以李汉俊就参加了改组后的省政府和省党部,安插了一些共产党人和共青团员,然后当时又组织这些革命力量和反动势力做斗争。
当时他动员很多中山大学的人到那一个广场打击那些反动派,支持工运什么的,也把一些进步人士包括李达呀到中山大学来任职。他是中山大学的校务委员嘛,所以当时那个国民党反动派对他必欲除之而后快。他知道自己这样做有被杀的可能。27年四一二政变以后,国民党在南京成立政府,一成立就秘密发布了一个通缉共产党首要令,李汉俊就名列其中。在五月份,李大钊他们在北京牺牲了,然后就在武汉举行了一次追悼南北烈士大会,他就在演说中就说我们不论何时何地均必须有牺牲的决心。后来南京方面派遣的西征军到了武汉,他很快就被武汉卫戍区的人把他以湖北共产党首领的罪名被抓了,没有审讯就杀掉了。
当时是不是也是害怕他的哥哥李书城过来救他,害怕劫狱救他。还有一个杀的原因就是怕他们响应广州起义还有好多因素吧。就有人说是胡宗铎、陶钧这两个武汉卫戍区政府司令把他们叫屠夫啊。其实这两个人的那个性格因素只是一方面,主要是南京有那么一个通缉令,就是李汉俊和詹大悲一块被杀的。刚一枪决就马上胡宗铎、陶钧就上报给国民党中央特别委员会,就说明实际上他们是在执行上级的命令。李汉俊很早其实就被国民党右派那边盯住了。
眼中间这样的角色还有一个就是说在那西征军到武汉之前,那个李书城和李汉俊他们把一些什么共产党员、国民群众给放掉了,放掉了200多人吧。他牺牲的时候只有37岁。李汉俊在这个年纪牺牲,其实算是英年早逝了。他去世的时候孩子太小了,那个李声簧。对这块我就想问一个问题,在您的生活当中有没有听到这些前辈们对李汉俊是怎么看待或者怎么评价的呢?
我多次访问过我的老外婆叫屈文淑,她做了好多口述,我给她整理成文发表。我的外婆李声韵一大的时候她那个时候10岁也在家,她说她不记得什么开会的事,就是讲的当时家里老有人来都可以算作开会吧,她都不知道哪天是开一大。她那个时候学钢琴,所以现在那个一大会址楼上有一架钢琴在那放着。我那个外婆吧保存了很多年,就是李汉俊在三益里他们全家的合影,那合影里头有李汉俊。79年的时候她拿出来给中央音乐学院当时研究者,然后呢她让我去拿回来,我就给了当时的还叫中国革命博物馆,这就是一大后来展出的那个照片。她也在八十年代初跟我和我爱人谈了一些关于她叔叔李汉俊的事。
我就念她说的,她说我在北京师范大学女附中上学时偏爱文科,叔叔知道以后对我说应当文理兼通并给我买了各类的书鼓励我阅读。而汉俊与李四光很熟有意介绍我与李四光认识,希望我多了解自然科学。我外婆还说三十年代初在为汉俊举行安葬仪式时,陈望道写了挽联”欲哭无泪”。邵力子呢打算抚养生簧,生簧就是李汉俊的儿子,我父亲没让。我的外公呢冯乃超虽然没见过李汉俊,但他从在日本第八高和东京帝大他也是在大学读书期间接受马克思主义的,与李汉俊有类似经历。后来呢他回国也间接了解一点李汉俊的情况,他对我们说二十七年我们几个人从日本回国到上海,彭康从对我说在中国第一个介绍社会主义的是冯自由,第一个介绍马克思主义的是李汉俊。冯自由他是外公的堂叔。二零年三月就曾经写过《社会主义与中国》提出中国应提前探索社会主义道路。
此外外公还几次讲有日本人称赞李汉俊的日语说得很流利。后来我知道这个日本人就是著名作家芥川龙之介,他访问过李汉俊,他就写李汉俊日语讲得极为流畅,甚至有些很复杂的道理他都让对方领会,所以他的日语可能比我还好。芥川还在信中称李汉俊堪称出类拔萃之才。我们外公呢三一年翻译过芥川龙之介,所以他应该读过芥川评价李汉俊的文字。顺便说一下外公一直很支持我们的研究。这些前辈还有很多人的当时的口述,比方说什么刘仁静、江亢虎、罗章龙很多我们当时访问了,这些口述回忆收入了我们编的《李汉俊传》这本书。
还有一本就是我们的论文集《中国共产主义运动探源》收入了我们研究李汉俊的一些论文。这两本书即将出版,期待老师的这个著作早日的上市。谢谢李老师。今天我们的节目就录到这里,感谢各位的收听。
2026-04-03 08:00:01
Marc Andreessen on AI Winters and Agent Breakthroughs
This episode originally aired on the Latent Space podcast.
Marc Andreessen has watched AI cycle through summers and winters for more than 35 years, from coding in LISP in 1989 to backing the foundation model companies today. He argues that the current moment is not another false start, but the payoff from eight decades of foundational research, catalyzed by four distinct breakthroughs,
He also makes the case that the combination of a language model, a Unix shell, and a file system represent one of the most important software architectures in a generation. Swix and Alessio Fanelli speak with Marc Andreessen, co-founder and general partner at A16Z.
Something about AI that causes the people in the field, I would say, to become both excessively utopian and excessively apocalyptic.
Having said that, I think what’s actually happened is an enormous amount of technical progress that built up over time. For example, we now know the neural network is the correct architecture. I will tell you, there was a 60-year run where that was 70 years where that was controversial.
I call it 80-year overnight success.
Which is an overnight success because it’s bam, ChatGPT hits and then 01 hits and then open call hits. And these are open, overnight, radical, overnight transformative successes, but they’re drawing on an 80-year sort of wellspring backlog of ideas and thinking. It’s not just that it’s all brand new. It’s that it’s an unlock of all of these decades of very serious hardcore research.
If I were 18, this is 100, this is what I would be spending all of my time on. This is such an incredible conceptual breakthrough.
Before we get into today’s episode, I just have a small message for listeners. Thank you. We will not be able to bring you the AI engineering, science and entertainment contents that you so clearly want if you didn’t choose to also click in and tune into our content. We’ve been approached by sponsors on an almost daily basis, but fortunately enough of you actually subscribed to us to keep all this sustainable without ads. And we want to keep it that way. But I just have one favor to ask all of you. The single most powerful, completely free thing you can do is to click that subscribe button. It’s the only thing I’ll ever ask of you. And it means absolutely everything to me and my team that works so hard to bring Latent Space to you each and every week. If you do it, I promise you we’ll never stop working to make the show even better.
Now let’s get into it.
Hey everyone, welcome to the Latent Space Podcast. This is Alessio, founder of Kernel Labs, and I’m joined by Swyx, editor of Latent Space. Hello, and we’re in A16Z with A, Mark and Jason. Welcome.
Yes. Yes. A and what? Half of 16? Half of the one. A1. Exactly.
Apparently, this is the final few days in your current office. You’re moving across the road. We have a limit of some projects underway. But yeah, this is actually, this is the original. We’re in actually the original office. We’re in the, we’re in the, we’re in the, we’re in the whole thing. It’s beautiful.
Yeah. Great. Thank you.
So I have to come out. This is a, I wanted to pick a spicy start. In October, 2022, I just made friends with Rune and I wanted to give him something to sort of be spicy about. And I said, it’ll never not be funny that A16Z was constantly going, the future is where the smart people choose to spend their time and then going deep into crypto and not in AI. And that was in October, 2022, and Rune says there was an internal meeting in A16Z to reorient around Gen AI. Obviously you have, but was there a meeting? What, what was that?
I mean, I don’t look, I’ve been doing AI since the late eighties. Yeah. So I don’t know, all that, as far as I’m concerned, this stuff is all Johnny come lately. Yeah. I mean, look, we’ve been doing AI our entire existence. I mean, we’ve been doing AI machine learning deep, deep, but we’ve been doing this stuff way from the beginning, obviously AI is just core to computer science. I actually view them as quite continuous.
Ben and I both have computer science degrees. We both, Ben and I actually both are old enough to remember the actual AI boom in the 1980s. There was a big AI boom at the time, and there was one of their names expert systems, and they were of Lisp and Lisp machines. I coded at Lisp. I was coding a Lisp in 1989 when that was the language of the AI future. Yeah. So this is something that we’re completely comfortable with and Been doing the whole time and are very enthusiastic about.
Is there a strong, this time is different because, my closest analog was 2016, 17. It was an AI boom. And it petered out very, very quickly. It’s just, it’s just in terms of investing, sort of investment, investment, excitement. Although that’s really when the, the, the NVIDIA phenomenon really, it was, it was, I would say it was in that period when it was very clear that at the time it, the vocabulary was more machine learning, but it was very clear at that time that machine learning was hitting some sort of takeoff point.
Well, and as you guys, you guys have talked about this at length on your, on your thing, but if you really track what happened, I think the real story is it was, it was the AlexNet basically breakthrough in 2013. That was the, that was the real knee in the curve. And then it was obviously the transformer breakthrough in 17.
And then everything that followed, but, but, machine learning, there were, I mean, I’ve been working, I’ve been working with one of my, kind of projects working with Facebook since 2004, and on the board since 2007. And of course that, they started using machine learning very early. And I’ve used it basically for 20 years for content, feed optimization and advertising optimization, and obviously many financial services, many, many, many companies, many different sectors have been doing this.
And so it’s like one of these things, it’s like, it’s not a single thing. It’s like layers, right. And the layers arrive at different paces, but they kind of build up, they kind of build up over time. And then, and then, in retrospect, 2017 was kind of the key point with the transformer. And that, and then as you guys know, there was this really weird four year period where the transformer existed. And then it was just like, let’s go.
But between 2017 and 2021, that was the era of which companies like Google had internal chat bots, but they weren’t letting anybody use them. And then OpenAI developed chat GPT or GPT two.
“this is way too dangerous to deploy”
And then they told everybody, this is way too dangerous to deploy. We can’t possibly let normal people, normal people use this thing. And then you guys, I’m sure remember AI Dungeon. So the only, there was like a year where the only way for a normal person to use GPT three was an AI Dungeon. And so we would do this, you’d go in there and you’d pretend to play Dungeons and Dragons and reality, you’re just trying to talk to, talk to GPT.
And so there was this long, the big, big companies, big companies are cautious and the big companies were cautious. By the way, it took OpenAI time to actually adjust, kind of redirect their research path. I think it was at Rosewood, the dinner that founded OpenAI was right there. But that dinner would have taken place in 2018. The formation of OpenAI as late as 2018. Sorry. No, I’m wrong. It should be 20. They just celebrated a 10 year anniversary. So it is 2025. So 2015, yeah, 2015.
But then, Alec Radford did GPT one in what? Probably 17, 18, 17, 18. So it is, and then they didn’t really, and then GPT three was what? 2020, 2020, 2020, because that became co-pilot immediately. Even OpenAI, which has been the leader of this thing in the last decade, even they had to adapt and lean into the new thing.
And so, yeah, I think it’s just this process of basically sort of wave after wave, layer after layer, building on itself. And then you kind of get these catalytic moments where the whole thing pops. And obviously that’s what’s happening now.
Is it useful to think about, will there be any winter? Cause there’s always these patterns. Is this endless summer? It’s something I constantly think about because do I get, do I just get endlessly hyped and just trust that I will only be early and never wrong. Well, are we, will there be a winter?
So there’s something about the following, there’s something about AI that has led to this repeated pattern. And you guys know this, but it’s summer, winter, summer, winter, summer, winter, and it goes back 80 years, 80 years.
2013
2017
2020
The original neural network paper was 1943, right. Which is, which is amazing. That was, it was far back that long.
And then there was, you guys, if you guys have ever talked about this on your show, but there was this, there was a big, there was an AGI conference at Dartmouth university in 1955. And they got an NSF grant for the all the experts at the time to spend the summer together. And they figured if they had 10 weeks together, they could get AGI on the other end. And they got there, by the way, they got the grant, they got the 10 weeks and then, making 55, no, no AGI.
And I said, I lived through the eighties version of this, where there was a big, a big boom and a crash. And so, so there is this thing and there, there is something about AI that causes the people in the field, I would say to become both excessively utopian and excessively apocalyptic. And, and it’s probably on both sides of the the boom bust cycle. You, you kind of see that play out.
Having said that, I think what’s actually happened is just in, and we now know in retrospect, an enormous amount of technical progress that built up over time. For example, we now know the neural network is the correct architecture. And I will tell you, there was a 60 year run where that was a, or even 70 years where that was controversial. And we now know that that’s the case. And so, we, we now, everything we’re building on today just sort of derives from the original idea in 1943.
And so, so in retrospect, we now know that these, these guys are right, they would get the timing wrong and they thought capabilities would arrive faster or there were, it could be turned into businesses sooner or whatever, but they were fundamentally, the scientists who worked on this over the course of decades were fundamentally correct about what they were doing and, and, and the payoff from, from, from all their work is happening now.
And so, so the way I think about what’s happening is basically, I think, I think about basically the, the, the period we’re in right now is it’s, I call it 80 year overnight success, right? Which is, it’s an overnight success. Cause it’s bam, chat GPT hits and then, and then O one hits and then, open call hits. And these are open, these are, these are overnight, radical overnight transformative successes, but they’re drawing on an 80 year sort of wellspring backlog of ideas and thinking it’s not just that it’s all brand new. It’s that it’s an unlock of all of these decades of very serious, hardcore research and thinking; look, there were AI researchers who spent their entire lives. They got their PhD, they worked for, they’ve researched for 40 years and they retired. And a lot of cases they passed away and they never actually saw it at work.
So sad. It is. It is sad. It is sad. And I knew something was the last guy.
Well, there were the guys, Alan Newell. I mean, there’s tons of John McCarthy. John McCarthy was one of the inventors of the field. He’s one of the guys that organized the Dartmouth conference. And, he taught at Stanford for 40 years and passed, passed away, I don’t know, whatever, 10, 10 years ago or something. Never, never actually got to see it happen. But it is amazing in retrospect, these guys were incredibly smart and they worked really hard and they were correct.
So anyway, so then it’s like, okay, say, say history doesn’t repeat, but it rhymes. It’s like, okay, does that mean that there’s going to be another, basically boom, bust cycle. And I will tell you, looks like in a sense, yes, everything goes through cycles and, people get overly enthusiastic and overly depressed. And there’s, there’s a time, there’s a timelessness to that.
Having said that there’s just no question. So the foremost, the foremost dangerous words, it was different. Do you know the 12 most dangerous words of investing? No, the foremost, foremost, dangerous words of investing are “this time is different.” The 12 most dangerous words. And so I’ll tell you what’s different. Now it’s working. There’s just no, I mean, look, there’s just no question. And by the way, I’ll just give you guys my take. LLMs, from basically the chat GPT moment through to spring of 25, I think you could still, I think well-intentioned, well-informed skeptics could still say, oh, this is just pattern completion. And oh, these things don’t really understand what they’re doing. And the hallucination rates are way too high. And this is going to be great for creative writing and creating, Shakespearean sonnets and, as, as rap lyrics or whatever, it’s gonna be great at all that stuff, but we’re not going to be able to harness this to make this relevant in coding or in medicine or in law or in, kind of feels that, kind of really, really matter.
And I think basically it was the reasoning breakthrough who it was a one. And then our one that basically answered that question and basically said, oh no, we’re going to be able to actually turn this into something that’s going to work in the real world. And then, and then obviously the coding breakthrough over the, or basically the coding breakthrough that kind of catalyzed over the holiday break was kind of the third step in that.
We’re just like, all right, if, if, Linus Torvalds is saying that the AI coding is not better than he is, “that’s, that’s never happened before.” That’s the benchmark. “That’s never happened before.” And so now we know that it’s, it’s going to sweep through coding. And then, and then we, we know that if it’s going to work in coding, it’s going to work in everything else.
Right. It’s just that, cause that’s, that’s the hardest, in many ways, that’s the hardest example. And now everything else is going to be a derivative of that.
And then on top of that, we just got the agent breakthrough with OpenClaw, which is fantastic, which is amazing and incredibly powerful. And then we just got the auto research, the self-improvement, we’re now into the self-improvement breakthrough.
And so the, so the way I think about it is we’ve had four fundamental breakthroughs and functionality, LLMs, reasoning, agents, and then now RSI, and they’re all actually working.
And so I’m, I’m just, as you guys, I’m jumping out of my shoes, this is it, this is the culmination of 80 years worth of work. And this is the time it’s becoming real.
Yeah. I’m completely convinced. I think the anxiety that people feel is during the transistor era, you had Moore’s Law and it’s all right, we understand why these things are getting better. We understand the physics of it. With AI, it’s so jagged in the jumps where, you said, in three months, you have this huge jump, and people are, well, this can keep happening.
Right. But then it keeps happening. It’ll keep happening. And so how do you think about also timelines of what’s worth building? I think we always have this question with guests, which is should you spend time building harness for a model versus the next model just going to do it one shot in the latent space. And how does that inform how you think about the shape of the technology? You talk about how it’s a new computing platform. If you have a computing platform that every six months it drastically changes in what it looks like, it’s hard to build companies on top of it.
Yeah. So it’s a couple of things. So one is look, Moore’s Law was what we now call a scaling law. When Moore’s Law was a scaling law and for your younger viewers, Moore’s Law was every chip, chips either get twice as powerful or twice as cheap every 18 months. And that it’s gotten more complicated in the last few years, but that was the 50 year trajectory of the computer industry. And then by the way, that’s what took the mainframe computer from a $25 million current dollar thing into the phone in your pocket being a million times more powerful than that for 500 bucks.
And so that was a scaling law. And then key to any scaling law, including Moore’s Law and the AI scaling laws is they’re not really laws, right? They’re predictions, but when they work, they become self-fulfilling predictions because they set a benchmark and then the entire industry, right? All the smart people in the industry kind of work to make sure that that actually happens. And so they kind of motivate the breakthroughs that are required to keep that going. And in chips, that was a 50 year run, right? And it was amazing. And it’s still happening in some areas of chips.
I think the same thing is happening with the core scaling laws, the core scaling laws in AI, they’re not really laws, but they are basically their predictions and then they’re motivating catalysts for the research work that is required to be. And, and, and, and by the way, also the investment dollars, required to basically keep the curves going and look, it’s, it’s going to be complicated and it’s going to be variable and they’re, they’re going to be walls that are going to look like they’re fast approaching and then they’re going to, engineers are going to get to work and they’re going to figure out a way to punch through the walls.
And obviously that’s, that’s been happening a lot, and then look, there’s going to be times when it looks like the walls have, the losses have petered out and then they’re going to, they’re going to pick up again.
Here’s what’s happening to the eyes. There’s now multiple scaling laws. There’s multiple areas of improvement. And I think I don’t know how many more there are already yet to be discovered, but there are probably some more that we don’t know about yet. They, for example, there’s probably some scaling law around world models and robotics that we don’t fully understand, kind of acquisition of data at scale in the real world that we don’t fully understand yet. So that one will probably kick in at some point here. There’s a bunch of really smart people working on that. And so, yeah, I think the expectation is that, the scaling laws generally are going to continue. The pace of improvement will continue to move really fast.
To your question on what to build. So I’m a complete believer of the scaling laws are going to continue. I’m a complete believer. The capabilities are going to keep getting amazing. Leaps and bounds, the part where I kind of part ways a little bit with what I would describe as the AI purists, which I would characterize as the people who are in many ways, the smartest people in the field, but also the people who spend their entire life in a lab and have very little experience in the outside world. The nuance I would offer is the outside world of 8 billion people and institutions and governments and companies and economic systems and social systems is really complicated. And it doesn’t, 8 billion people making collective decisions on planet earth is not a simple process of just seeing this happening now. It’s like a bunch of the AI CEOs have this thing, which is just this obvious set of things that society needs to do. And then they’re like, society’s not doing any of those things. Right. And it’s like, how can society not see X, Y, Z? And the answer is, well, society is number one, there’s no single society. It’s 8 billion people and they all have a voice and they all have a vote at the end of the day on how they react to change. And then, you know, human reality is really complicated and messy.
And so the specific answer to your question is like, as usual, it depends. It depends. Look, there’s no question people are going to like, there’s no question. They’re going to be companies. It’s already happening. There are companies that think that they’re building value on top of the models and then they’re just going to get blissed by the next model. There’s no question that’s happening. But I think there’s no question also that just the process of adaptation of any technology into the real, into the real messy world of humanity is just going to be messy and complicated. It’s not going to be simple and straightforward. It’s going to be messy and complicated and there are going to be a lot of companies and a lot of products, and in fact, entire industries that are going to get built to basically actually help all of this technology actually reach real people.
The amount of capital going into these companies. I mean, Dario talked about it on the door cash podcast and door cash was like, "why don't you just buy 10 X more GPUs?" And he’s like, "because I'm going to go bankrupt if the model doesn't exactly hit the performance level." How do you think about that? Also as a risk on, you guys are investors, and open AI and thinking machines and world apps, it seems like we’re leveraging the scaling loss at a pretty high rate. How comfortable, I guess, do you feel with the downside scenario? And say things peter out, you think you can kind of restructure these build outs and capital investment.
Yeah. So let’s just start by saying, so I lived through the.com crash. And I can tell you stories for hours about the.com crash and it was horrible. No, it was awful. It was, it was, it was, it was apocalyptic. By the way, the, a lot of the.com crash was actually at the time it was actually a telecom crash. It was a bandwidth crash. The, the thing that actually crashed that wiped out all the money was the telecom companies. Global Crossing. Global, global. Yes. I’m from Singapore and they, they laid so much cable over, over our oceans.
Well, actually there was a scaling law in the.com era. And it was literally the, the U.S. Commerce Department put out a report in 1996 and they said internet traffic was doubling every quarter. And it actually in 1995 and 1996, internet traffic actually did double every quarter. And so that became the scaling law. And so what all these telecom entrepreneurs did was they went out and they raised money to build fiber, anticipating that the demand for bandwidth is going to keep doubling every quarter. Doubling every quarter though, is, grains of chess and the chessboard. At some point the numbers become extremely large. Right.
And, and, and it really, and really what happened was the internet, the internet, by the way, continuously kept growing basically since inception. It is, it’s, it’s continuously grown. It’s never shrunk and it’s grown really fast compared to anything else, in, in, in human history, but it wasn’t doubling every quarter as of 1998, 1999. And so there was this gap in the expectation of what they thought was a scaling law versus reality. And that’s actually what caused the.com crash, which was they, they, they way over companies Global Crossing way overbuilt fiber, which is sort of the, by the way, fiber telecom equipment, so all the, all the networking gear, and then, and then by the way, the actual physical data center.
So that was the beginning of the, of the, of the data center build and then, and the data center overbuilt. And so you had that, but it was, it was literally, I think it was $2 trillion got wiped out. Right. It was a big, and by the way, the other, the other subtlety in it was the internet companies themselves never really had any debt because tech companies generally don’t run on debt, but the telecom companies run on debt, physical infrastructure companies run on debt. And so the companies like Global Crossing, not just raised a lot of equity, they also raised a lot of debt. So they’re highly levered. And so then you just do the thing. It’s just, okay, you have a highly levered thing where you’re, you’re just over, you’re overbuilding capacity. Demand is growing, but not as fast as you hoped. And then boom, bankrupt. Right.
“it’s always the third owner of a hotel that makes money, right? It has to go bankrupt twice, right? You have to wash out all of the over-optimistic exuberance before it gets to actually a stable state. And then it makes money.”
So by the way, all of those data centers and all of those, all the fiber that they’re in use, it’s all in use today, but 25 years later, but it took, and actually the elapsed time was it took 15 years. It took 15 years from 2000 to 2015 to actually fill up all that capacity. The cautionary warning is the overbuild can happen. And, and, and, and, you get into this thing where basically everybody, everybody who basically has any sort of institutional capital is wow, it’s just, I don’t know how to invest in these crazy software things, but for sure I can put, build data centers and for sure I can buy GPUs and I can deploy compute grids and, and all these things. And so, if you’re a pessimist, you can look at this and you can say, wow, this is really set up to be able to basically replicate what we went through, what we went through in 2000. Obviously that would be bad.
The counter argument, which is the one I agree with, which is the counter on the other side is a couple of things. One is the companies that are investing all the, the companies that are investing the money are the bluest chip of companies. And so back, back, back in the, in the doc, global crossing was an entrepreneur. it was a new venture, but the money that’s being deployed now at scale as Microsoft, Amazon, Google, Facebook, NVIDIA, and now, by the way, open AI and anthropic, which are now really serious size, as companies with very serious revenue, these are very large scale companies with lots, lots of cash, lots of debt capacity that they’ve, they’ve never used. And so this is institutional In a way that that really wasn’t at the time. And then the other is at least for now, every dollar that’s being put into anything that results in a running GPU is being turned into revenue right away. So, and you guys know this, everybody starved for capacity, everybody starved for compute capacity. And then, all the associated things, memory and interconnect and everything else data center space. And so every dollar right now that’s being put in the ground is turning into revenue. And, and, and in fact, I actually think there’s an interesting thing happening, which is because everybody starved for capacity, the models that we actually have that we can use today are inferior versions of what we would have, if not for the supply constraints.
If right. To pose a hypothetical universe in which GPUs were 10 times cheaper and 10 times more plentiful, the models would be much better because you would just allocate a lot more money to training and you’d just build better models and they would be better. And so we’re actually getting the sandbag version of the technology. No, everything we use is quantized because the labs have to keep the full versions, right? We’re not even getting the good stuff, but, but getting the good stuff is just, even if technical progress stops, once there’s a much bigger build of GPU manufacturing capacity and memory, all the, all the things that have to happen in the course of the next five or 10 years, once it happens, even the current technology is going to get, going to get much better. And then, as you know, there’s just a million ways to use this stuff. There’s just a million use cases for that. It, this isn’t just sending packets across a thing, whatever, and hoping people find something to do with it. This is just, we apply intelligence into every domain of human activity. And then it works incredibly well.
Here’s what I know. Here’s what I know. In the next three or four years, it’s somewhere between three or four years out, basically everything is selling out. And so the entire supply chain is, is, is sold out or selling out. And so there, there’s no, we’re just going to have chronic supply shortage for years to come. There’s going to be a response from the market that’s going to result in an enormous, it’s happening now an enormous flood of investment in a new fab capacity and everything else to be able to do that. At some point, the supply chain constraints will unlock, at least to some degree, that will be another accelerant to industry growth when that happens. Cause the products will get better and everything will get cheaper. And so, so I know that’s going to happen. I know that the deployments, the actual use cases are really compelling. And then, with reasoning and agents and so forth, I know they’re just going to get much, much better from here. And so I know the capabilities are really, real and serious.
I also know that the technical progress is not going to stop. It is, it is accelerating. The breakthroughs are tremendous. I mean, even just month over a month, the breakthroughs are really dramatic. And so, I think if you were a cynic and there are cynics, you can look at 2000, you can find echoes, but I can’t even imagine betting that this is going to somehow disappoint. And, at least for years to come, I think it would be essentially suicidal to make that bet.
“Who’s that Michael Burry?”
“Oh, that’s an interesting guy.”
We’ll pick on a guy. We’ll pick, let’s pick on one guy. Well, cause he did, he came out with, it was, it was, he doesn’t mind. It was the Nvidia short, right? He came out with the Nvidia short. And then you guys probably talked about this, which is the analysis now that the current models are getting better, faster at such a rate that if you are running an NVIDIA inference chip today, that’s three years old, you’re making more money on it today than you did three years ago, because the pace of improvement of the software is faster than the depreciation cycle of the chip. And then my understanding is Google is running, I don’t think, I don’t know exactly what, these are rumors that I’ve heard, or maybe it’s public, but, I think Google’s running very old TPUs, very profitable and very profitably. And so, so it actually turns out as far as I can tell that it’s actually the opposite of the Burry thesis is actually, he was actually 180 degrees wrong. It’s actually the, the, the old Nvidia chips are getting more valuable, which is something that’s literally never happened before. Like it’s never been the case that you have an older model chip that becomes more valuable, not less valuable. And again, that’s an expression of the, just a ferocious pace of software progress, ferocious pace of capability payoff that you’re getting on the other side of this. And so I just, the idea of betting against that, yeah, it’s an invitation to get your face ripped off.
One of my early hits was modeling the lifespan of the H100 and H200 and going, usually they advise four to seven years and it was maybe you sort of realistically cut it down to two to three, but actually it’s going up and not down. And that’s, I mean, that’s, I think that’s the dream. We are finding utilization and I think utilization solves all problems. You can find use cases for even the poor, even memory we’re having a shortage, right. And even the shittier versions of memory that we do have, we are finding use cases for it. So that’s great.
How important is open source AI and edge inference in a world in which you have three years of supply crunch? Do you think, if you fast forward five years, how do you think about inference in the data center versus at the edge?
Well, I think open source is very important for a bunch of reasons. I think edge inference is very important for a bunch of reasons. I think just practically speaking, if we’re going to have fundamental construct supply crunches for the next, if you just project forward demand over the next three years, relative to supply, one of the dismaying predictions you can do is what’s going to happen to the cost of inference in the core over the next three years. And it may rise dramatically. So what is, and then is the big model companies are subsidizing heavily right now. And so what’s the average person’s per day, per month token costs, three years from now to do all the things that they want to do. I have friends today who are paying a thousand dollars a day for OpenClaw tokens to run OpenClaw. So, okay, $30,000 a month. And by the way, those friends have a thousand more ideas of the things that they want their Claw to do. So you could imagine there’s latent demand of up to, I don’t know, five or $10,000 a day of tokens for a fully deployed personal agent. And obviously consumers can’t pay that. But it gives you a sense of the future scope of demand. So even if there’s a 10 X improvement in price performance, that’s still, it goes to a hundred dollars a day, which is still way beyond what people can pay. So there’s just going to be ferocious demand. By the way, the agent thing, the other interesting thing is I think the agent thing. Up until now, a lot of the constraints have been GPU constraints. I think the agent thing now also translates into CPU and memory constraints. CPU and memory. And so the entire chip ecosystem is just going to get with the network constraints. That will be the killer. That’s all bottlenecked and potentially for years. And so I think that Brad, and I think it’s actually possible. I mean, generally inference costs are going to keep coming down, but I think the rate of decline may level out here for a bit because of these supply constraints. And then at some point, maybe the labs stop subsidizing so much and that again will be an issue. And so there’s just going to be so much more demand for inference than can be satisfied kind of with the centralized model. And then, you know, the dramatic innovations that have happened in the Apple Silicon to be able to do inferences. It’s quite amazing. A level of effort being put, the open source guys are putting incredible effort into getting this recurring pattern where the big model will never run on a PC. And then six months later, it runs on a PC, right? It’s amazing. And there’s very smart people working on that. So there’s all that. And then there’s also other motivators, which is just, okay, how much trust are the big centralized model providers building in the market versus, at least for, in certain cases, With some people for certain use cases, people being “I’m not willing to just turn everything over.” So there’s all the trust issues. By the way, there’s also just straight up price optimization. There’s many uses of AI where you don’t need Einstein in the cloud. You just need a smart local model.
There’s also performance issues where you want your doorknob to have an AI model in it to be able to do access control. Obviously everything with a chip is going to have an AI model in it. And a lot of those are going to be local. And so, yeah, I think you’re going to have wearable devices. You don’t want to do a complete round trip. You want whatever your smart devices are to be super low latency.
The question, do we care who makes it? One of the biggest news this week was the collapse of AI to the Allen Institute, one of the actual American open source model labs. And I’m not that optimistic on American open source. You guys invested in Mistral and Mistral is doing extremely well outside of China. That’s about it. We’ll see.
Number one, I do think we care. I don’t think we care who makes it.
“the previous presidential administration wanted to kill it in the U.S.; they wanted to drown in the bathtub.”
And so they wanted to kill it. So at least we have a government now that actually wants it to happen. And you’re in the council and the new and the PCAST. This admin, for whatever other political issues people have, which are many, this administration has, I think, a very enlightened view and in particular an enlightened view on AI and in particular on open source AI. And so they’re very supportive.
My read is the Chinese companies have a very specific reason to do open source, which is they don’t fundamentally think they can sell commercial AI outside of China right now, or at least specifically not in the U.S. for a combination of reasons. And so they kind of view open source AI as a bit of a loss leader against basically domestic paid services and then kind of ancillary products; they’re very excited about it.
By the way, I think it’s great. I think it’s great that they’re doing it. I think DeepSeek was a gift to the world. I think the great thing about open source is the impact of open source has felt two ways:
And so the paper and the code.
For example, I thought this was amazing. So OpenAI comes out with o1 and it’s an amazing technical breakthrough and it’s absolutely fantastic. But of course they don’t explain how it works in detail. And then of course they hide the reasoning traces. And then everybody’s like, okay, this is great. But who’s going to be able to replicate this? Are other people going to be able to do this? Is there a secret sauce in there?
And then R1 comes out and there’s the code and there’s the paper. And now the whole world knows how to do it. And then three months later, every other AI model is adding reasoning. And so you get this kind of double: even if the Chinese models themselves are not the models that get used, the education that’s taken place to the rest of the world, the information diffusion, is incredibly powerful. So that happens.
And then I don’t know, we’ll see. There are a bunch of American open source AI model companies. I mean, look, there’s going to be tremendous competition among the primary model companies. Depending on how you count, there’s like four or five big co model companies now that are kind of neck and neck in different ways. And then obviously both X and then Meta where I’m involved are both have huge attempts to kind of leapfrog underway. And then you’ve got a whole fleet of startups, new companies, including a whole bunch that we’re back in that are trying to come out with different approaches. And then you’ve got whatever it is. I don’t know how, how many, how many main line foundation model companies are there in China at this point? It’s probably six.
“It’s five tigers is what they call it.”
Qwen is in questionable because there’s change in leadership. Right. Yeah. But that does that include, that includes Moonshot. Yes. Okay. Yeah.
And then you’d say, ByteDance would be the next year, but they weren’t as prominent. They weren’t have a, but now, yeah. But they’re at least, see, see dance is very inspiring and presumably they have more stuff coming in Tencent probably has more stuff coming and so forth.
And so, so, so look, here, here would be a thing you can anticipate, which is there are not these markets. They’re not going to be between the U S and China right now, there’s a dozen primary foundation model companies that are at scale at some level of critical mass, it’s not going to be a dozen in three years. Right. It, just because these industries don’t bear a dozen, it’s going to be three, there’s going to be three or four big winners or maybe one or two big winners.
And so there’s going to be a whole bunch of those guys that are going to have to figure out alternate strategies. And I think open source is one of those strategies. And so I think you could see a whole, I think the questions like who’s going to do open source. I think that could change really fast. I think that that’s a very dynamic thing. I think it’s very hard to predict what happens. And I think it’s very important.
NVIDIA is doing a lot.
Well, I was gonna say, well, exactly. And then you got NVIDIA and then, and then, you know, just to get an industrial, there’s an old thing in business strategy, which is called a commoditize the complement. And that’s right. And so if your Jensen is just kind of obvious, of course you want to commoditize the software and he’s, and to his enormous credit, he’s putting enormous resources behind that. And so maybe, maybe it’s literally NVIDIA and I think that would be great.
Yeah. Yeah. Narrative violation to European projects. NVIDIA. I’m hosting my Europe conference soon. And I got both of them. They got us. They got us. Okay. Well, wait a minute. Where was Peter? So where was Steinberger when he did Austria? Yeah. Yeah. He was in Vienna. Oh, he was in Vienna. And then where is he now? He’s moving to SF. Okay. Okay. All right. Okay. There we go. And then, yeah, the pie guy, right. The pie guys are European. Yeah. They’re buddies in Austria. Mario is also there. Right. And are they, yeah, they haven’t announced yet any sort of change, changed or have they? No, they have a company there. Okay. Okay. Okay. Good.
Good. Anyways, I think Pi and OpenClaw, very important software things. And I just wanted you to just go off on what do you think? Yeah. So I think in the combination of the two of them, I think is one of the 10 most important software. OpenClaw got all the attention, but right. Talk about Pi. Pi is kind of the, yeah, Pi is kind of the architectural breakthrough for those of us who are older. There was this whole thing that was very important in the world of software, basically from 1970 to, I don’t know, it still is very important, but like 19 from 1970 through to like basically the creation of Linux, which is basically this, this thing we used to call the Unix mindset. So, because there were all these different, you know, theories, there are all these different operating systems and mainframes and then, you know, all these windows and Mac and all these things. And then there was this, but kind of behind it all was this idea of kind of the Unix mindset.
And the Unix mindset was this thing where basically you don’t have these, like, in the old days, the operating system that made the computer industry really work in the 1960s was this thing called OS 360, which was this big operating system that IBM developed that was supposed to basically run everything. And it was this giant monolithic architecture in the sky. It was like a, you know, it was like a giant castle of software. And by the way, it worked really well and they were very successful with it, but it was this huge castle in the sky, but it was this thing, it was almost unapproachable, which is, you had to be kind of inside IBM or very close to IBM. And you had to really understand every aspect of the system worked.
“No, let’s have a completely different architecture.” To work is we’re going to have, we’re going to have a prompt and a shell. And then we’re going to, all the functionality is going to be in the form of these discrete modules. And then you’re going to be able to chain the modules together.
And so the, it’s almost the operating system itself is going to be a programming language. And then that led to the sort of centrality of the shell. And then that led to a sort of basically changing the other Unix tools. And then that led to the emergence of these, these scripting languages Perl, where you could basically kind of very easily do this. And then the shells got more sophisticated. And then looked like that number one, that worked.
And that was the world I grew up in. I was a Unix guy, sort of from call it 1988 to kind of all the way through my work. And it worked really well. It’s in the background. Normal people don’t need to, didn’t need to necessarily know about it, but if you were doing system architecture application development, you knew all about it. And then it’s been in the background ever since. Look, your Mac still has a Unix shell kind of in there and your iPhone still has a Unix shell kind of buried in there somewhere. So they’re kind of in there. And then the Windows shell is kind of a sort of a weird derivative of that. But look, the internet, the internet runs on Unix, and then smartphones, actually both iOS and Android are Unix derivatives. And so kind of Unix did end up winning, but anyway, we just started taking that for granted.
So basically the way I think about what happened with Pi and then with OpenClaw is basically what those guys figured out is I always say the great breakthroughs are obvious in retrospect, right? Which is the best kind, the best kind. They weren’t obvious at the time or somebody else would have done them already. And so there is a real conceptual leap, but then you look at it sort of the backwards looking and you’re just
“Oh, of course.”
to me, those are always the best breakthrough. So actually language models themselves are like that. It’s just
“Oh, next token completion. Oh, of course.”
“What other objective mattered?”
Yeah. What other objective mattered? Yeah, exactly. But she’s even saying it wasn’t obvious until somebody actually did it. Right. And so the conceptual breakthrough is real and deep and powerful and very important.
And so the way I think about Pi and OpenClaw is it’s basically marrying the language model mindset to the unit, to the Unix basically shell prompt mindset. And so it’s basically this idea that what, what, so what is an agent, right? And as many smart people have been trying to figure out what an agent is for decades. And they’ve had many architectures to build agents and the whole thing. And it turns out what is an agent. So it turns out what we now know is an agent is the following: it’s a language model. And then above that, it’s a bash, it’s a bash shell. So it’s a Unix shell. And then the agent has access to the shell and hopefully in a sandbox, maybe in a sandbox. So it’s the model, it’s the shell. And then it’s a file system. And then the state is stored in files. And then there’s the markdown format for the files themselves. And then there’s basically what in Unix is called a cron job. There’s a loop and then there’s a heartbeat for this heartbeat and the thing basically wakes up. So it’s basically
LLM + shell + file system + markdown + cron
And it turns out that’s an agent. And every part of that other than the model is something that we already completely know and understand. And in fact, it turns out the latent power of the Unix shell is extraordinary because basically there’s just enormous latent power in the shell. There’s enormous numbers of Unix commands. There’s enormous number of command line interfaces into all kinds of things already in your entire, I mean, your entire, just to start with your computer runs on a shell. If you’re running a Mac or a phone, your computer’s running on a shell already. And so the full power of your computer is available at the command line level. And then it turns out it’s really easy to expose other functions as a command line interface. And so this whole idea where we need MCP and these fancy protocols, whatever, it’s no, we don’t, we just need a command command line thing. So that’s the architecture. And then it turns out, what is your agent? Your agent is a bunch of files stored in a file system.
And then there’s the thing that just completely blew my mind when I wrapped my head around it as a result of this, which is, okay, this means your agent is now actually independent of the model that it’s running on because you can actually swap out a different LLM underneath your agent. And your, your agent will change personality somewhat because the model is different, but all of the state stored in the files will be retained different instruction sets, but you just compiled it. Right. Exactly. And it’s all right. It was right.
Swapping out a ship and recompiling, but it’s still your agent with all of its memories and with all of its capabilities. And then, by the way, you can also swap out the shell. So you can move it to a different execution environment. That is also a bash shell. By the way, you can also switch out the file system. Right. And you can, and you can, and you can swap out the heartbeat for the CRON framework, the loop, the agent framework itself.
And so your agent basically is at the end of the day, it’s just, it’s just its files. And then there’s, of course, yeah, it’s basically, it’s just the files. And then by the way, as a consequence of that, the agent, it’s, and then the agent itself, it turns out a couple important things.
So one is it, it’s, it can migrate itself. Right. And so you can instruct your agent, migrate yourself to a different runtime environment, migrate yourself to a different file system, migrate yourself to a different, we swap out the language model, your agent will do all that stuff for you. And then there’s the final thing, which is just amazing, which is the agent actually has full introspection and actually, it actually knows about its own files and it can rewrite its own files. Right.
“Oh, I have my OpenClaw, do whatever, connect to my eight sleep bed. And it gives me better advice than sleep.”
Which by the way, is basically no widely deployed software system in history where the thing that you’re using actually has full introspective knowledge of how it itself works and is able to modify itself like that, there’ve been toy systems that have had that, but there, there’s never been a widely deployed system that has that capability. And then that leads you to the capability that just completely blew my mind when I wrapped my head around it, which is you can tell the agent to add new functions and features to itself. And it can do that. Right. Extend yourself, extend yourself, give yourself a new capability. Right.
And so, and so literally it’s just like, you run into somebody at a party and they’re “Oh, I have my OpenClaw, do whatever, connect to my eight sleep bed. And it gives me better advice than sleep.” And you go home at night and you tell your Claw or if they’re at the party, by the way, you tell your Claw, “Oh, add this capability to yourself.” And your Claw will say, “Oh, okay, no problem.” And it’ll go out on the internet and it’ll figure out whatever it needs. And then it’ll go out to cloud code or whatever it’ll write, whatever it needs. And then the next thing, you know, it has this new capability.
And so you don’t even have to, you can have it upgrade itself without even having to do anything other than tell it that you want it to do that. And so anyway, so the combination of all this is just, I mean, this is just like a massive, incredible, I mean, it’s just incredible. If I were, if I were 18, this is what I would be spending all of my time on. This is such an incredible conceptual breakthrough.
And again, people are going to look at it and they already get this response. People are going to look at it. They’re going to say, “Oh, well, where’s the breakthrough? Cause these, the, all of these components were already known before,” but this is the key. The key to the breakthrough was by using all these components that were known before you get all of the underlying capability of this buried in there. And so all, and so for example, computer use, all of a sudden just kind of falls trivial, trivial. Of course, it’s going to be able to use your computer. It has full access to the shell. Right. And then you just, you give it access to a browser and then you’ve got the computer in the browser and often away it goes. And then you’ve got all the abilities of the browser also.
And so, and so the capability unlock here is profound. My friends who are deepest into this are having their Claw do a thousand things in their lives. They have new ideas every day. They’re constantly throwing new challenges. It’s the thing. And by the way, it’s early and you know, These are prototypes and there’s, as you guys know, there’s security issues. And so there’s a bunch of stuff to be ironed out, but the unlock of capability is just incredible. And I have absolutely no doubt that everybody in the world is going to, is going to have at least an agent like this, if not an entire family of agents, and we’re going to be living in a world where I think it’s almost inevitable now that this is the way people are going to use computers.
I was going to say for someone who is deeply familiar with social networks, the next step is your Claw talking to my Claw, posting on Claw Facebook, posting their jobs on Claw LinkedIn and Claws posting their tweets on Claw XAI or whatever. I do think that that is how we, we get into some danger there in terms of alignment and whether or not we want these things to, to, to run.
You guys never rent a, rent a human.com. Yeah. I mean, it’s Fiverr, it’s test. Sure. Of course. mechanical Turk. But flipped. Right. The agent hiring the people, which of course is going to happen. It’s obviously going to happen.
I’m curious if you have any thoughts on the engineering side. So when you build the browser, the internet, just a bunch of mostly plain text files, plus some images. And today every website and app is so complex and somehow the browser kept evolving to fit that in. Are there any design choices that were made early in the browser and the internet and the protocols that you’re seeing agents similar today? It’s like, Hey, this thing is just not going to work for this type of new compute. And we should just rip it out right now.
There were a whole bunch, but I’ll give you a couple. So one is, and we didn’t, to be clear, this was not, this was totally different. We didn’t have the capabilities we have today, but we didn’t have the language models underneath this, but we did have this idea that human readability actually mattered a great deal. And specifically in those days, it was not so much English language, but there was a design decision to be made between:
And basically every basically old school systems architect that had grown up between the 1960s and the 1990s basically said, “what do you know about the internet?” It’s starved for bandwidth. You just have these very narrow straws. Look people, when we did the work on Mosaic, people who had the internet at home had a 14-kilobit modem, right. And so you’re trying to hyper-optimize every bit of data that travels over the network. And so obviously if you’re going to design a protocol like
HTTP
you’re going to want it to be binary, highly compressed binary protocol for maximum efficiency. And you’re going to want to have it be a single connection that persists. The last thing you’re going to want to do is bring up and tear down new connections. And you definitely are not going to want a text protocol. And so of course we said, no, we actually want to go completely the other direction. It’s obviously we only want text protocols. By the way, same thing in HTML itself, we want HTML to be relatively verbose. We want the tags to actually be human readable. We want to use the most inefficient things possible.
We want to do the inefficient things. You’re the original token maxer. Basically it’s just, well, this was actually the conscious thing, which basically says assume, assume a future of infinite, infinite bandwidth built for that. And then basically what it was, is it was a bet that if the system was, if the latent capabilities of the system were powerful enough, and that was obvious enough to people that would create the demand for the bandwidth that would cause the supply of bandwidth to get built, that would actually make the whole thing work. And then specifically what we wanted was we wanted everything to be human readable because we, at the engineering level, wanted people to be able to read the protocol coming over the wire and be able to understand it with their bare eyes without having to disassemble it or whatever. Right. And have it converted out of binary. Right. And so all the HTTP and everything else where it was always text protocols, and the same thing with HTML. And in many ways, some people say that the key breakthrough in the browser was the view source option, which is every webpage you go to, you could view source. “Which means you could see how it worked, which means you could teach yourself how to build right new to build new web pages. There was that. So human readability and again, human readability in those days still met technical specs. Now it means English language, but there’s an incredible latent power in giving everybody who uses the system, the option to be able to drop down and actually understand. I see how it’s working and that worked really well for the web. And I think it’s working really well for AI. That was one.
What was the other, a big part of the idea of web servers was to actually surface the underlying latent capability of the operating system and to be able to surface the also the underlying latent capability of the database, because basically what was a web server, what, what, what, what is a web server fundamentally architecturally it’s, it’s, it’s, it’s the operating system.
So it’s the operating system’s ability to manage the file system and do everything else that you want to do and process everything. And then of course, a lot of early, a lot, a lot of websites are financed to databases. And so you wanted to unleash the underlying latent power of whether it was an Oracle database or some other Postgres or whatever, whatever it was. And so a lot of the function of the web server was to just bridge from that internet connection coming in to be able to unlock the underlying power of the OS and the database.
And again, people looked at it at the time and they were, well, is this really, does this really matter? Is this important because we’ve had databases forever and we’ve always had user interfaces for databases and this is just another user interface for a database. And it’s, okay, yeah, fair enough.
But on the other side of that is just, this is now a much better interface to databases and one that 8 billion people are going to use and is going to be far easier to use and far more flexible. And, and, and you’re not just going to have old databases. Now you have a system where people can actually understand why they want to build a million times more database apps than they have in the past. And then the number of databases in the world exploded.
And so again, this goes to this thing of building, building in layers. Some of the smartest people in the industry look at any new challenge and they’re, okay, I need to build a new kind of application. So the first thing I need to do is build a new programming language. Right. And then the next thing I need to do is build a new operating system. Right. And the next thing I need to do is I need to build a new chip. Right. And they kind of want to reinvent everything. And I’ve, I’ve always had, maybe it’s just, pragmatic mentality or something, or maybe an engineering over science mentality, but it’s more like, no, you have just like all of this latent power in the existing systems. And you don’t want to be held back by their constraints, but what you want to do is you want to kind of liberate that power and open it up. And so I think, I think, and I think the web did that for those reasons. And I think it’s the same thing now that’s happening. It’s a good perspective on the web.
Programming languages is another good thing. We have Brett Taylor on the podcast and we were talking about Rust and Rust is memory safe by default. And so why are we teaching the model to not write memory unsafe code? “Just use Rust and then you get it for free.” How much do you think there’s time to be spent, recreating some of these things instead of taking them for granted? I’ll be, Oh, okay. Python is kind of slow. Python type scripts. You know, it’s, as imperfect as they are, they are the Lingua Franca. I mean, I think this is going to change a lot because I don’t think the models care what language they program in. And I think they’re going to be good at programming on every language. And I think they’re going to be good at translating from any language to any other language.
So this gets into the coding side of things. I think we’re going through a really fundamental change. And I grew up, I grew up hand code, I grew up hand coding. Everything I did was actually, everything I did actually was written in C. I wasn’t back in the day. I wasn’t even using C plus plus. So I, or Java or any of this stuff. Right. And so, I, everything, everything I ever did, I was managing my own memory at the level of C. And then I, you know, I’m still from the generation that, I knew assembly language and, you know, I, I could drop down and do things, right on the ship. And so we, we’ve just, we’ve all, all of us, we’ve always lived in a world in which software is this precious thing that you have to think about very carefully. And it’s really hard to generate good software. And there’s only a small number of people who can do it. And you have to be very jealous in terms of thinking about how do you allocate what are your engineers working on and how many good engineers do you actually have and how much software can they write and how much software can human beings kind of maintain. And I think all those assumptions are being shot right out the window right now. I think they’re, I think those days are just over. And I think the new world is actually high quality software is just infinitely available. And if you need new software to do X, Y, Z, you’re just going to wave your hand and you’re going to get it. And then if it’s, if you don’t like the language is written and you just tell the thing, all right, I want the right now, I want the rest version. Or, security, security, we’re about to, by the way, go through computer security is about to go through the most dramatic change ever, which is number one, every single latent security bug is about to be exposed. Right.
So we’re going to have the, we’re, we’re set up here for the computer security apocalypse for a while, but on the other side of it, now we have coding agents that can go in and actually fix all the security bugs. And so how are you going to secure software in the future? You’re going to tell the bot to secure it and it’s going to go through and fix it all. And so this thing that was this incredibly scarce resource of high quality software is just going to become a completely fungible thing that you’re just going to have as much as you want. Right. And that has tons and tons of consequences. In some sense, the answer to the question that you posed, I think is just somewhat, I don’t know, simple or something or straightforward, which is just, if you want all your software and rest, you just tell the bot you want all your software and rest, the things that used to be the hard or even seem like an insurmountable mountain to get through all of a sudden, I think become very easy.
I think Brett had a theory that there would be a more optimal language for LLMs. And so the contention is there isn’t just don’t bother just whatever humans already use LMs are perfectly capable porting. I think we’re pretty close to being, I don’t know if this works today. I think we’re pretty close to being able to ask the AI, “what would its optimal language be and let it design it.” Okay. Here’s a question.
Let’s assume for a moment that humans aren’t coding anymore. Let’s assume it’s all bots. What levels of intermediate abstraction do the bots even need? Or are they just coding binary directly? Did you see there’s actually an experience? If somebody just did this thing where they have a, they have a language model now that actually emits model weights for a new language model, right? And so will the bots predict the weights? Yeah. Well, the bots literally be emitting, not just coding binaries, but will they, will they actually be emitting weights for new, for new models directly, directly and conceptually there’s no reason why they can’t do both of those things.
Architecturally, both of those things seem completely possible.
Very inefficient. You’re basically very inefficient simulation of a simulation in a simulation inside of weights. Yeah. Yeah. Very inefficient, but look, LLMs are already incredibly inefficient. Ask a favorite thing. Ask Claude: add two plus two equals four. Right. It’s just whatever billions and billions of times more inefficient than using your pocket calculator. But yeah, the payoff is so great of the general capability. And so anyway, I kind of think in 10 years, I’m not sure. Yeah. I’m not sure there will even be a salient concept of a programming language in the way that we understand it today. And in fact, what we may be doing more and more as a form of interpretability, which is we’re trying to understand why the bots have decided to structure code in the way that they have.
I mean, if you play it through, you don’t need browsers then that’s the death of the browser. Well, so I would take it a step further, which is you may not need user interfaces.
So who is going to use software in the future?
Other bots.
Other bots. Yeah. And so you still need to, I don’t know, pipe information in and out. Really? Well, what are you going to do then? Are you sure? You’re just going to log off and touch grass? Whatever you want. Exactly. Isn’t that better? I want software to do stuff for me. Isn’t that, but isn’t that better?
I mean, look, I, I don’t look like the arguments here, it was not that long ago that 99% of humanity was behind a plow.
Right. Right. And what are people going to do if they’re not plowing fields all day to, to, to grow food? Right. And it just turns out there’s much better ways for people to spend time than plowing fields. Yeah. Do is growing. Exactly. Talking to their friends and look, I’m not an absolutist and I’m not a utopian.
And I, and to be clear, I’ve, I have an 11-year-old and he’s learning how to code and I’m, I think it’s still a really good idea to learn how to code and so forth, but I just, if you project forward and you just have to think forward to a world in which it’s just, okay, I’m just going to tell the thing what I need and it’s going to do it.
And then, and then it’s going to do it in whatever way is most optimal for it to do it. Yeah. Unless I tell it to do it non-optimally, if I tell it to do it in Java or in Rust or whatever, it’ll do it. I’m sure. But if I’m just going to tell it to do, it’s going to do it in whatever way is the optimal way to do it.
And then I, and then if I need to understand how it works, I’m going to ask it to explain to me how it works. Right. And so it’s going to be doing its own interpreter. It’s going to be the engine of interpretability to explain itself.
And I just am not convinced that—I’m not convinced that in that world you have these historical, the goals of the abstractions will be whatever the boss need at what the human’s right. Yeah. Yeah.
Well, I’m curious, if that’s true, then shouldn’t the models providers be building some internal language representation that they can do extreme kind of RL and reward modeling around?
Because it’s today they’re kind of tied to TypeScript and Python because the users need to write in that language versus they can have their own thing internally.
And they don’t need to teach it to anybody. They just need to teach their model.
And I think that’s how you get maybe the version between the models, going back to the PI open cloud thing.
“Oh, I built all the software using the open AI model and I’ll switch to the anthropic model, but the anthropic model doesn’t understand the thing.”
So I, it feels like there still needs to be some obstruction, but maybe not, maybe that’s the lock-in that the model providers want to have. I don’t know. I’m not even sure that’s lock-in though. Cause why can’t the second model just learn what the first model has done? Exactly. Okay. So, okay. Give me an example.
So as you know, models can now reverse engineer software, but isn’t it the whole thing now where people are reverse engineering Nintendo game binaries? Yeah. So you have, I’ve seen a bunch of reports this where somebody has a favorite game from the 1980s and the source code is long dead, but they have a binary bird to do a chip or something, another reverse engineer to get a version of the rest of their Mac.
Right. And so if you reverse it, if this is what I kind of say, if you’re reversing x86 binaries, then why can’t you reverse engineer? Whatever they create.
Yeah. And because we’re all on a Unix based system, it has to be reversible because it needs to run on the target. Yeah. Yeah. Yeah. Yeah. Yeah. Basically.
And so I just, I just think it’s this thing where it’s just, and by the way, everything we’re describing is something that human beings in theory could have done before, but with enormous cost and labor for prohibitive reverse engineering. I learned how to reverse engineer. Human beings can reverse engineer binaries. It’s just for any complex binary, you need a thousand years to do it. But now with the model, you don’t.
And so all of a sudden you get, you get these things or another way to think about it is so much of human built systems are to compensate for the human limitations. Yeah. Right. And if you don’t have the human limitations anymore, then all of a sudden you have, and it’s not that you won’t have abstractions, but you’ll have a different kind of abstraction. Yep.
I have two topics to bring us to a close and you can pick whichever ones are just talking about protocols. Was it you or someone else? I forget my internet history. We said that the biggest mistake that we didn’t figure out in the early days was payments.
“Yes.”
“Was that you?”
“Yes.”
It was a 402, 402 payment required.
We have a chance now. I don’t think we’re going to figure it out. I don’t know. What’s your take? Oh, I think we will. Yeah. No, now I think it’s going to happen for sure. Yeah. Yeah. And there’s two reasons it’s going to happen for sure.
One is we actually have internet native money now in the form of stable coins, stable coins and crypto. And this is, I think this is the grand unification basically of AI and crypto is what’s about to happen now. I think AI is the crypto killer app, I think is where this is really going to come out. And then the other is, it’s just, I mean, it’s just, I think it’s now obvious. It’s obviously AI agents are going to need money and it’s already happening, right? If you’ve got a, if you’ve got a Claw and you want it to buy things for you, you have to give it money in some form. I would say the adoption is probably 0.1% if that, but yeah. Oh, today. Yeah, yeah, yeah. But think forward. It’s, where is it going? Forward thinking.
The ultimate principle of everything and everything that I think we do is the William Gibson quote, which is the
“the future is already here. It just isn’t distributed.”
It isn’t, it isn’t distributed yet.
My friends who are the most aggressive users of, of, of, of OpenClaw just have given their Claws, bank accounts, credit cards. And, and, and, and, and, and not only have they done it, it’s obvious that they needed to do it because it’s obvious that they needed to be able to spend money on their, it’s just completely obvious. And so, and again, so the number of people who have done that today to your point is like, I don’t know, probably 5,000 or something, but that’s how these things start. Actually, I mean, since you keep mentioning. And by the way, OpenClaw, by the way, if you don’t give it a bank account, it’s just going to break into your account. It’s going to break into your bank account anyway and take your money. So you, you might, you might as well do it. You might as well do it.
By the way, I really love, I got to tell you, I really love the phenomenon. I love the YOLO. I’m not doing it myself to be clear, but I love the people that are just like, what is it? Skip, skip, skip, dangerously, which by the way, it’s a Facebook thing. “Okay.” Because in Facebook, they have this culture to name the thing dangerous so that you are aware when you enable the flag that you are opting into a dangerous thing. Okay, good. And they brought it into OpenAI. And of course, that makes it enticing. Sam runs Codex with skip permissions on his laptop. Yes. A hundred percent.
And so I think the way to actually see the future is to find the people who are doing that. There’s a madness, you know. Log everything, you know, just watch it. Watch the logs. But let’s actually find out what the thing can do. And the way to find out what the thing can do is just, yeah, let it try everything. Let it unlock everything. By the way, that’s how you’re going to find all the good stuff it can do. By the way, that’s also how you’re going to find all the flaws. I think the people who turn that on for bots are like, they’re like martyrs to the progress of human civilization. I feel very bad for their descendants that their bank accounts are going to get looted by their bots in the first like 20 minutes. But I think the contribution that they’re making to the future of our species is amazing. It’s like gentleman science. Yes, it’s, yes, yes. Experiment on yourself.
Yes. So, yes, I think we should have like a glory, we should have like flags and like we should have like monuments to the people that just let OpenClaw run on their lives. More anecdotes. I was like, what are the craziest or interesting things that people listening to this should go up, go home and do? I mean, this is, this is, this is the extreme thing is just the straight YOLO. Just, yeah, turn, turn your life. That’s a general capability. Yeah. Yeah.
Like a specific story that was like, wow. And everyone in the group chat just lit up. I mean, tons of, there’s already tons of health, there’s the health dashboard stuff is just, it’s just absolutely, absolutely amazing. The number of stories on, I’m trying to just don’t want to violate people’s, obviously personal. But, one of the things OpenClaw instances are really good at is hacking into all this stuff in your land. It’s really good. So, internet of things, AKA internet of shit, super insecure, but great. Discoverable. Discoverable. OpenClaw is happy to scan your network, identify all the things.
And then my friends most aggressive at this are having OpenClaw take over everything in their house.
Yeah.
I have a friend whose Claw watches him sleep. Put a webcam in your bedroom; put the Claw in a loop.
I have it wake up frequently and have it watch it and just tell him, > “watch me sleep.”
And I’ve seen the transcripts and it’s literally like Joe’s asleep. This is good. This is good that Joe’s asleep because I have his health data and I know that he hasn’t been getting enough sleep.
And so it’s really good that he’s getting sleep. I really hope he gets his full, whatever, five hours of REM sleep.
Joe’s moving. Joe’s moving. Joe might be waking, waking up. This is a real price. Joe wakes up now. He’s going to ruin his sleep cycle. Oh, okay. It’s okay. Joe just rolled over. Okay. He’s gone back to bed. Okay, good. All right. Okay. I can relax. This is fine. He’s monitoring the situation and being a bot; it’s just very focused. It’s just like, this is his reason for existence is to watch Joe sleep.
And then I was talking to my friend who did this; on the one hand, it’s, “all right, this is weird and creepy,” and I need to maybe this has taken over my life. And then the other thing is, if I had a heart attack in the middle of the night, this thing literally would freak out and call 9-1-1. There’s no question this thing would figure out how to alert medical authorities and probably summon SWAT teams and do whatever would be required to save my life.
Right. And so that’s happening or what else?
It’s a company Unitree that makes the robot dogs. And then I actually have one at home, which is actually really fun with the Chinese companies. The Chinese companies are so aggressive at adopting a new technology, but they don’t always take the time to really package it and maybe think it all the way through.
At least the Unitree dog I have has an old non-LLM control system, which, by the way, is not very good in markets. In practice it’s not that good. It has trouble with stairs and so forth. So it’s not quite what it should be, but then the language model thing comes out in the voice, so they add LLM capability and then they add a voice mode to it.
But that LLM capability is not at all connected to the control system. So you’ve got this schizophrenic dog that is a complete idiot when it comes to climbing the stairs, but it will happily teach you quantum mechanics in a plummy English accent. It’s absolutely amazing.
Jagged intelligence. Talk about jagged. And now, obviously what’s going to happen in the future is they’re going to connect together, but right now it’s not that useful.
And so I have a friend who has one of these who had his Claw basically hack in and rewrite the code, write new firmware for the Unitree robot. And now it’s an actual pet dog for his kids.
You should do that before, after the motion.
Yeah. It’s good. You said it’s completely different. He said it’s a complete transformation.
And whenever there’s an issue in the thing, now the Claw just rewrites the code. You go, does the code. And so it kind of goes to your thing here.
So all of a sudden, this is why we want to think about AI coding. AI coding is not just writing new apps. It’s also going in and rewriting all the old stuff that should have worked that never worked.
I think the internet of shit is basically over. I think everything, there’s a potential here where all these devices in your house that have been basically marginal or basically dumb might all get really smart.
Now you have to decide if there are horror movies in which this is the premise. And so you have to decide if you want this, but this is the first time I can say with confidence I now know how you could actually have a smart home with 30 different kinds of things with chips and internet access where it actually all makes sense. It all works together and it’s all coherent in the whole thing.
And to have that unlock without a human being having to go do any of that work. I’m waiting for a story, Mark. I can’t let you open that fridge door. Exactly. Yes. Because you’re not supposed to eat right now. I have all of, yes, I have every thread of health information, and I know you think you’re doing dah, dah, dah, I don’t think you can do this, but this is a real, are you really sure? And you told me last night, you really don’t want me to let you do this. So, I’m sorry, but the fridge door is locked. Open the fridge door. Exactly. And by the way, I know you’re supposed to be studying for a test. So why don’t we, why don’t you go when you can pass the test? I will open the fridge door for you.
Final protocol.
And then we can wrap up a proof of human.
Yes.
Right.
There’s two massive, I would say sort of asymmetries in the world right now where we’ve known these asymmetries exist and we societally have been unwilling to grapple with them. And I think they’re both tipping right now and they’re the same thing as virtual world versions, physical world version.
So the virtual world version is the bot problem. We’re just like, the internet is just a wash and bots. Internet’s a wash and fake people. It has been forever. By the way, a lot of that has to do with lack of money.
This is my spicy take: these two are the same thing and corporations are people too.
Okay. So a bank account is proof of human. Until you give the bots bank accounts.
So, there’s that, but the bot problem is a big problem. Every social media user knows this: the bot problem has been a big problem forever. It’s a huge problem and it’s never really been confronted directly.
The physical world version of this is the drone problem. We’ve known for 20 years now that the asymmetric threat, both in military conflict but also in security on the home front, the big threat is the cheap attack drone, the cheap suicide drone with a bomb. And we’ve known that forever. It’s very disconcerting how every office complex in the world is unprotected from drone attacks. Every stadium, every school, every prison—okay, we’ve known that and we’ve never done anything about it.
One possibility is just leave them unprotected forever and live in a world of asymmetric terrorism forever. The other is take the problem seriously and figure out the set of techniques and technologies required to be able to deal with that. Whether those are:
In both cases, these are economic asymmetries. It’s really cheap to feel the bot, but it’s very hard to tell something about it. It’s really cheap to feel the drone. It’s very expensive to defend against a drone. But you see what I’m saying: it’s the virtual version of the problem and it’s the physical version of the problem. The virtual version of the problem: what we need quite literally is proof of human.
The reason is because you’re not going to have proof of bot, especially now that the bots are too good; the bots can pass the Turing test. And if the bots can pass the Turing test, then you can’t screen for bot. You can’t have proof of not a bot, but what you can have is you can have proof of human. You can have cryptographically validated: this is definitely a person and this is cryptographically validated: this is definitely like something that a person said. This video is real.
Just to double click on, do you think Alex Blania with world, do you think he’s got it or is there an alternative? Oh, so I mean, there’s going to be, I think many people will try. We’re one of the key participants in the world, in the world project. And so we’re partisans, but yeah, I think, so we think world is exactly correct. And the reason is it has to be, it has to be proof of human. It has, because you can’t do proof of not bot. You have to do proof of human. To do proof of human, you need, you need biological validation. You needed to start with, this was actually a person, right? Because otherwise you have bots signing up as fake people, right? And so you, you have to have like something, you have to have a biometric and then you have to have cryptographic validation and then the ability to do, to do, to do the lookup. And then by the way, the other thing you need, which that you also need selective disclosure. So you need to be able to do proof of human without revealing all the underlying information.
By the way, another thing you’re gonna need, you’re gonna need proof of age, right? Because there’s all these laws in all these different countries now around, you need to be 13 or 16 or 18 or whatever to do different things. So you’re gonna, you’re gonna need, you know, sort of validate a proof of age to be able to legally operate. Right. And so that, that’s coming. And then you’re going to want like proof of credit score and, you know, proof of like, you know, a hundred other, that’s a tricky one.
It is a tricky one, but you’re going to, you’re going to, there’s no reason, like if somebody’s checking on your credit, somebody shouldn’t give you an example, somebody shouldn’t need to know your name in order to be able to find out whether you’re credit worthy. I see independently verifiable pieces of information, pieces of information. It’s like just likely disclosed. And this is the answer to the privacy problem writ large, which is, I only need to prove I need to prove at that moment. So like, you’re going to need that. And I think their, their, their architecture makes sense. So that needs to get solved.
I think language models have tipped the bots are now too good. And so they’re undetectable. And so as a consequence, we now need to go confront that problem directly. And then, like I said, and then the other problem is we need to go actually confront the drone problems. The Ukraine conflict has really unlocked a lot of thinking on that. Now the Iran situation is also unlocking that. And so I think there’s going to be just like this incredible explosion of both drone and counter drone. Our drones are better than their drones. It’s supposed to keep it that way. Yeah. And counter drones.
I think we can sneak in one more question. I’m trying to tie together a lot of things that you said over the year. So at the Milken Institute debate with Teal, which is amazing. You talked about the lag between a new technology and kind of like the GDP impact of it, the other idea you talked about is bourgeois capitalism and how, you know, it’s kind of managerial class was needed because of this complexity. And I think if you bring it into the fold, you have like much higher leverage people. So like if you have the Musk industries, and you give Elon a GI, you can run a lot more things at once. That’s right. And then you have the social contract. And I know you received a clip of some moment saying, “we’re rethinking the whole thing.” and you’re like, absolutely not. I was at an event with Sam last night. And he actually said in the last couple of weeks, he felt like now people are taking that seriously. So I’m just curious, like how you’re seeing the structure of organization changing, especially when you invest in early stage companies and, yeah, just like how the impact of work structure and all of that is playing out.
Yeah. So there’s a whole bunch of, there’s a whole bunch of times. I know. We could spend, by the way, we’d be happy to spend more time, but we could, we could spend more time on all that. So just for people who haven’t followed this, so this, this, this, this term managerial comes from this thinker in the 20th century, James Burnham, who just one of the great kind of 20th century political thinkers, societal thinkers. And he sort of said as, and he was writing in like the 1940s, 1950s. And he said kind of the whole history of capitalism until that point had been in two phases.
Number one had been what he called bourgeois capitalism, which was thinking about as like name on the door, like Ford motor company. Cause Henry Ford runs the company. And Henry, it’s like a dictate dictatorial model. And Henry Ford just like tells everybody what to do. And he said, the problem with bourgeois capitalism is it doesn’t scale. Cause Henry Ford can only tell so many people to do so many things. And then he runs out of time in the day.
And so he said the second phase of capitalism was what he called managerial capitalism, which was the creation of a professional class of managers that are trained not to be like Car experts or to be whatever experts in any particular field, but are trained to be experts in management.
And then that led to the importance of Harvard Business, management consulting firms and all these things.
And then you look at every big company today and most of the executives and most of the Fortune 500 companies are not domain experts in whatever the company does. And they’re certainly not the founders of those companies, but they’re professional managers. And in fact, in the course of their careers, they’ll probably manage many different kinds of businesses. They’ll rotate around and they might work in healthcare for a while and then work in financial services and then go work in something else, come work in tech.
And what Burnham said is he said that transition is absolutely required because the problem with bourgeois capitalism is it doesn’t scale. Henry Ford doesn’t scale. And so if you’re going to run capitalist enterprises that are going to have millions to billions of customers, you’re going to need to operate at a level of scale and complexity that’s going to require this professional management class. And he said, “whether you think that’s good or bad or whatever, it’s what’s going to be required.” And basically that’s what happened.
Right. And so he wrote that book originally in the 1940s. Over the course of the next 50 years, basically managerialism took over everything. And what I’m describing is basically how all big companies run and how all governments run and how large-scale nonprofits run and kind of everything runs.
Basically, what venture capital does is we basically are a rump sort of protest movement to that, to try to find the next Henry Ford, or just to say Elon Musk, or the next Elon Musk, or the next Steve Jobs, the next Bill Gates, the next Mark Zuckerberg. And so we start these companies in the old model. We start them out in the Henry Ford model. And so we start them out with a founder or a founder with colleagues, but you know, there’s a founder CEO. And then we basically bet that the startup is going to be able to do things specifically innovate in ways that the big incumbents in that industry are not going to be able to do.
And so it’s a bet that by relighting this sort of name on the door, this new innovative thing with a king, monarchical political structure, that they’re going to be able to innovate in a way that the incumbent is not going to be able to because the incumbent is being run by managers. And by the way, and of course, venture being what it is, sometimes that works, sometimes it doesn’t, but we’re constantly doing that. But I’ve always viewed it in my entire life as, “we’re like raging against the dying of the light.” We’re constantly trying to fight off managerialism swamping everything and everything getting basically boring and gray and dumb and old. We’re trying to keep some level of energy and vitality in the system.
AI is the thing that would lead you to think, wow, maybe there’s a third model. Maybe it’s a combination of the two. Maybe the new Henry Ford or the new Elon Musk or the new Steve Jobs plus AI is the best of both. Because it’s the spark of genius of the name on the door model, the Henry Ford model, but then give that person AI superpowers to do all the managerial stuff and let the boss do all the managerial stuff. That may be the actual secret formula.
And we’ve never even known that we wanted this because we never even thought it was a possibility. But what is the thing that these bots are really good at? “They’re really good at doing paperwork. They’re really good at filling out forms. They’re really good at writing reports. They’re really good at reading. They’re really good at doing all the managerial work.” And so, yeah, I think the answer very well might be to get the best of both worlds by doing this.
Do you feel like that structure accelerates the impact on the actual GDP and economy? If you look at SpaceX, it’s the growth is so fast. And instead of having these companies peter out and growth and impact, they can keep going if not accelerating.
That’s for sure. The hope, the challenge and look, the AI utopian view is of course that’s going to be the future of the economy. And it’s going to grow 10 X and a hundred X and a thousand X.
And we’re entering this regime of much higher economic growth forever and consumer cornucopia of everything. And it’s going to be great. And I hope that’s true. I hope that’s the current kind of utopian vision. I hope that’s true.
The problem is it goes back again. The real world is really messy. And I’ll give you an example of how the real world is really messy. It requires 900 hours of professional certification training to become a hairdresser in the state of California. So it’s 35% of the economy. You have to get some sort of professional certification to do the job, which is to say that the professions are all cartels, right?
And so you have to get licensed as a doctor. You have to get licensed as a lawyer. You have to get licensed as a, you have to get into a union. By the way, to work for the government, you need to have both civil service protections and you have public sector unions. You have two layers of insulation against ever getting fired for anything or anything ever changing. I’ll give you another example: the dock workers went on strike a couple of years ago. Because robotics, if you go look at a modern dock in Asia, it’s all robots. If you go to American docks, it’s still guys, dragon, strike, dragon stuff by hand.
The dock workers went on a strike. It turns out there are 25,000 dock workers working on docks in America. It turns out they have incredible political power because it’s a unified block of things. They won their strike. And so they got commitments from the dock owners to not implement more automation. We learned a couple of things in that. So number one, we learned that even a union, the smallest 25,000 people still has tremendous political stroke. We also learned that it actually turns out the dock workers union has 50,000 people in it because they have 25,000 people working at the docks. They have 25,000 people during full paycheck sitting at home from prior union agreements.
I’ll give you another great example. There are government agencies. There are federal government agencies where the employees have civil service protections and they’re in public sector unions. There are entire federal government agencies that struck new collective bargaining agreements during COVID. Not only do they have their jobs guaranteed in perpetuity, but they only have to report to work in an office one day per month. And so there are entire office buildings in Washington, D.C. that are empty 29 out of 30 days of the year that are still operating and we’re all still paying for it. And so what the employees do is they’re very smart in this way. And so they figure out, they come in on the last day of a month and the first day of the next month. And so they’re in the office two days per 60 days, which means these buildings are empty for 58 days at a time.
And you see where I’m heading with this, this is locked in, right? This is locked in in a way that has nothing to do with capitalists, it’s restrictions on trade. It’s restrictions on the ability to change the workforce. And so so much of our economy is the, I’m describing the entire healthcare system. I’m describing the entire legal profession. I’m describing the entire housing industry. I’m describing the entire education system, right? K through 12 schools in the United States, they’re a literal government monopoly. How are we going to apply AI on education? The answer is we’re not because it’s a literal government monopoly. It is never going to change the end and there is nothing to do. By the way, you can create an entirely new school system. That’s the one thing you can do is you can do what alpha school is doing. You can create an entirely new school system. Other than that, you’re not going to go in and change what’s happening in the American classroom. K through 12, there’s no chance. The teachers are 100% opposed to it. It’s a hundred percent not going to happen.
So you see what I’m saying is, there’s this massive slippage that’s going to take place. Both the AI utopians and the AI doomers are far too optimistic, right? You see what I’m saying? Because they believe that because the technology makes something possible, that 8 billion people all of a sudden are going to change how they behave. And it’s just, nope, so much of how the existing economy works. It’s just, it’s just wired in. And so we’re going to be lucky as a society. We’re going to be lucky if AI adoption happens quickly, right? Cause if it doesn’t more, we’re just going to have a stagnation.
I know you got to run. Yeah. I don’t know if you’re still welcome, but it was such a pleasure talking to you.
“We’re truly living in an age of science fiction coming to real life.”
Yes. Yes. Could not be more exciting. Yeah. Really. Thank you, Mark. You guys. Awesome. Thank you. That’s it. Good. Thank you.


